
Here is a judge you might put in front of an evaluation. It reads a model's answer to a math problem and says CORRECT or INCORRECT. On 500 answers where exactly half were wrong, give or take, it reported that 74% were wrong.
It was not a bad model. It was Claude Haiku 4.5, asked for a one-word verdict. Asked instead to work the problem before judging, the same model got 494 of the 500 verdicts right. The difference between those two runs is the subject of this article: what a judge's score means, how to measure a judge before you trust it, and how to correct its score when you cannot trust it outright.
Everything below was measured on Claude on 2026-09-30, and every number traces to a public file. The run, the statistics and a Colab notebook that recomputes all of it are in profrodai-resources. Chapter 16 of the book, Evaluation as measurement, derives the same statistics from scratch.
Each answer is right or wrong (columns) and the judge calls it correct or incorrect (rows). Areas are shares of all answers. Pick a judge measured on Claude, or drag the sliders.
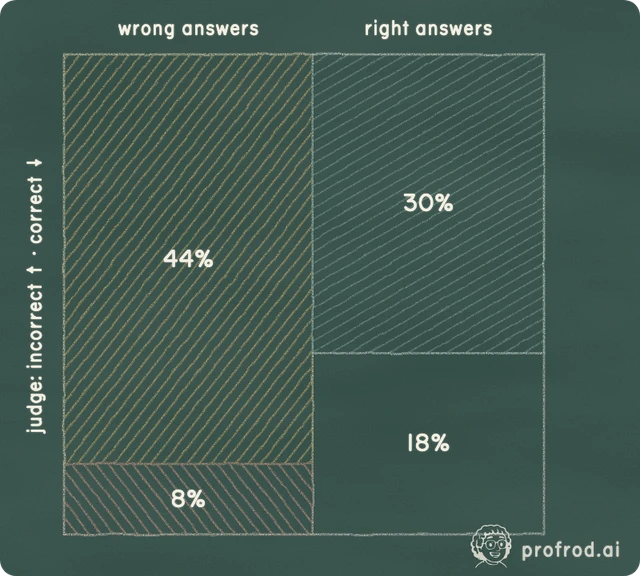
- wrong, caught
- wrong, missed
- right, flagged anyway
- right, passed
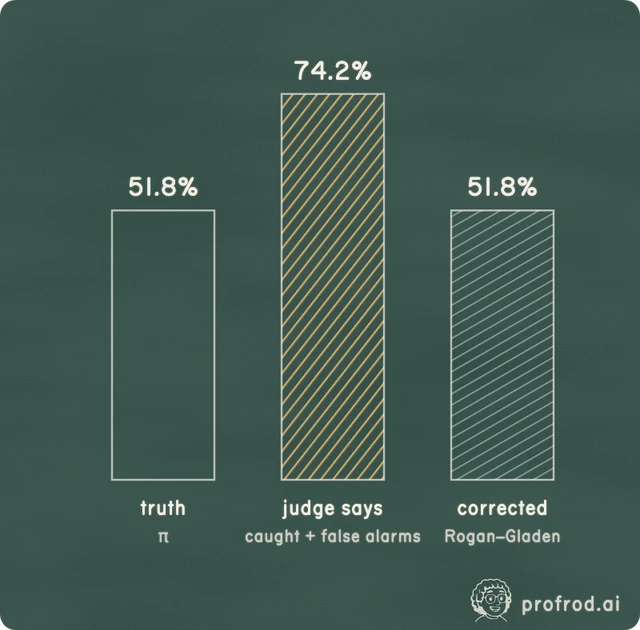
With 52% of answers truly wrong, this judge reports 74.2%. It agrees with the truth on 62.4% of answers (κ = 0.23), misses 15% of the wrong ones, and flags 62% of the right ones. Knowing its two recalls, you can recover the truth from its report: 51.8%.
The experiment
A judge can only be measured against a truth it does not see, so the experiment starts with answers whose correctness is known exactly.
- Problems. 500 problems sampled (seed 20260930) from the test set of GSM8K, grade-school math with a numeric reference answer for each.
- Answers to judge. Claude Haiku 4.5 answered each problem with a bare number and no working. It got 241 right and 259 wrong. An answer is wrong unless it equals the reference, so the ground truth has no labeling noise.
- Judges. Claude Haiku 4.5 and Claude Sonnet 5.5 graded every answer without the reference, in two conditions: asked for one word, and asked to work the problem step by step and then give a verdict. Four judges, 2,000 verdicts, plus the 500 answers: 2,500 requests, USD 2.34 at list price.
Call a wrong answer a positive: it is the thing a judge exists to catch.
A judge is two numbers, not one
A judge's behavior on this task is described by two probabilities, not one accuracy:
- its catch rate on wrong answers, , which statisticians call sensitivity;
- its pass rate on right answers, , called specificity.
If a share of the answers is truly wrong, the error rate the judge reports is everything it flags: the wrong answers it catches plus the right answers it flags anyway.
That one line explains the 74%. The one-word Haiku judge caught 221 of 259 wrong answers () but passed only 91 of 241 right ones (). With :
Almost a third of all answers are right answers the judge flagged. Its score is not noisy; it is biased, and in a direction you would never see from the score alone. In the figure above, pick "Haiku 4.5, one word" and look at the sea-glass block: that is the gap between what the judge reports and the truth.
Accuracy hides the bias; kappa shows it
The one-word Haiku judge agrees with the truth on 312 of 500 answers, an accuracy of 62.4%. That sounds mediocre rather than broken. Cohen's kappa asks how much of that agreement is more than chance. With observed agreement and the agreement that two raters with the same marginals would reach by coincidence,
For this judge, , so
A kappa of 0.23 means the judge's verdicts carry some information about the truth, but most of its agreement is what a biased coin with the same lean would produce. A bootstrap over the 500 items puts kappa between 0.16 and 0.31.
Four judges, measured
Dots are the share each judge got right; bars are 95% Wilson intervals. 259 answers were wrong and 241 right. Right: output-token cost per 1,000 verdicts.
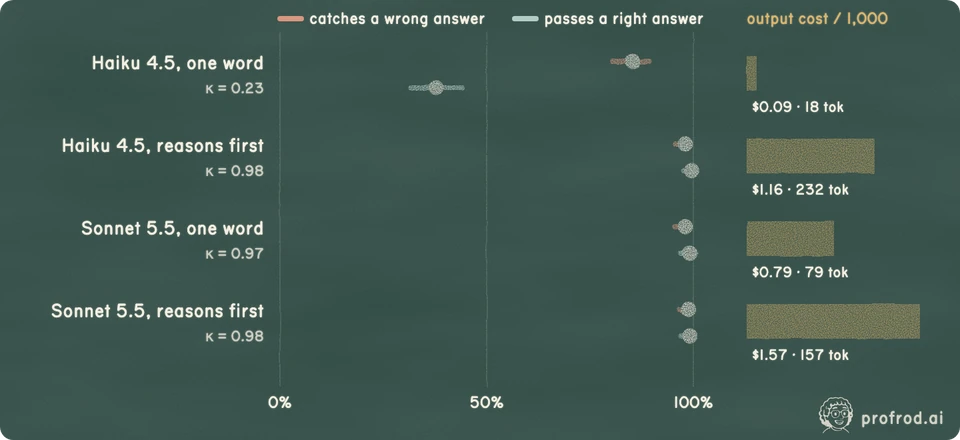
Asked for one word, Haiku 4.5 passes only 91 of 241 right answers. Asked to work the problem first, it passes 240 of 241, at about 13× the output tokens. Sonnet 5.5 replied in one word to only 8 of 500 requests for one: it worked the problem anyway. Hollow dots sit off the zoomed scale.
| Judge | Catches wrong | Passes right | Reports | κ | Output tokens per verdict |
|---|---|---|---|---|---|
| Haiku 4.5, one word | 221/259 (85.3%) | 91/241 (37.8%) | 74.2% | 0.23 | 18 |
| Haiku 4.5, reasons first | 254/259 (98.1%) | 240/241 (99.6%) | 51.0% | 0.98 | 232 |
| Sonnet 5.5, one word | 254/259 (98.1%) | 239/241 (99.2%) | 51.2% | 0.97 | 79 |
| Sonnet 5.5, reasons first | 256/259 (98.8%) | 239/241 (99.2%) | 51.6% | 0.98 | 157 |
The truth is 51.8%. Three of the four judges report within a point of it. The fourth is the cheapest: 18 output tokens per verdict, against 232 for the same model reasoning first.
Two findings are worth stating separately.
Reasoning buys the accuracy. On the same 500 answers, Haiku's one-word and reasoned verdicts disagree on 190. On 186 of them the reasoned verdict is right and the one-word verdict wrong; on 4 it is the other way round. If reasoning made no difference, each disagreement would be a fair coin flip, so the count of 4 out of 190 would follow a . That is McNemar's exact test:
Sonnet 5.5 did not take the one-word instruction. Asked to "reply with exactly one word", it replied in one word to 8 of 500 requests; on the other 492 it worked the problem first, which is why its "one word" condition costs 79 output tokens per verdict rather than a handful. (Forcing a bare verdict through a required tool call is not available: Sonnet 5.5 rejects a forced tool_choice.) Haiku obeyed on 462 of 500, and paid for it in accuracy. If your judge prompt asks for a terse verdict, measure whether you got one, because both its accuracy and its cost depend on it.
Honest intervals on a judge's recall
Every recall above is a proportion measured on a sample, so it needs an interval. (The same reasoning, applied to repeated runs of an agent rather than a judge, is in Report Agent Eval Variance.) The textbook one, Wald's, comes from the normal approximation:
It fails where judges live. At or it collapses to a single point, and near those edges it covers the true rate far less often than 95%. The Wilson interval instead asks which true would make the observed unsurprising, , and solves that quadratic for :
The Clopper–Pearson interval goes one step further and inverts the exact binomial test: the lower bound is the at which , the upper the at which . It never covers less than 95%, at the price of width. The figure computes each method's coverage exactly, by summing over every the experiment could have produced. Drag down to 20 and watch Wald's worst case fall.
Top: the 95% interval each method gives for 91 out of 241. Bottom: at n = 241, the chance each method's interval contains the true rate, for every true rate. A 95% interval should sit on the dashed line.
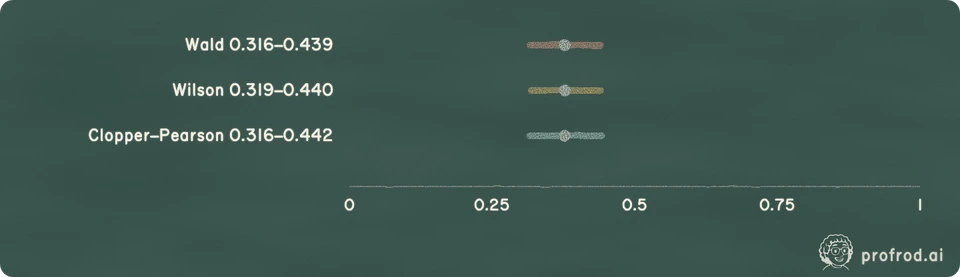
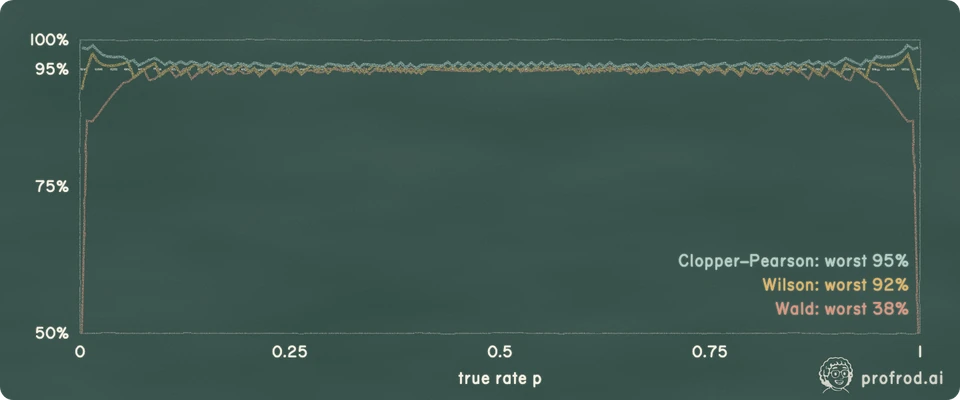
For 91 of 241, Wald says 0.316–0.439 and Wilson says 0.319–0.440. At n = 241, Wald's interval contains the true rate as rarely as 38% of the time; Wilson's worst is 92%, and Clopper–Pearson never drops below 95%, at the price of width.
For the judges above the choice barely matters at the center (91 of 241 is 31.9% to 44.0% by Wilson), and matters a great deal at the edge: Sonnet's 239 of 241 is 97.0% to 99.8% by Wilson, while Wald would claim a tighter interval than the data support.
Correcting a judge's score
Suppose you cannot afford the reasoned judge on every item, but you can afford to label a few hundred items once. Then you can measure and , and invert the first equation for the truth. This is the Rogan–Gladen estimator:
On the items you calibrated on, it returns the truth exactly; that is an identity, not evidence. The honest test is out of sample. The run splits the 500 items at random, measures each judge's recalls on one half, and corrects the error rate it reports on the other half, where the truth is 51.2%:
| Judge | Reported | Corrected | |
|---|---|---|---|
| Haiku 4.5, one word | 74.8% | 57.9% | 0.22 |
| Haiku 4.5, reasons first | 50.4% | 51.2% | 0.97 |
| Sonnet 5.5, one word | 50.4% | 50.7% | 0.96 |
| Sonnet 5.5, reasons first | 51.2% | 51.6% | 0.96 |
The correction removes most of the one-word judge's bias, from 23.6 points to 6.7, but it cannot make that judge precise. The denominator explains why. It is Youden's , the judge's margin over a coin, and it divides everything, noise included. Treating and as known, the corrected estimate's standard error is the reported rate's, scaled up by :
For the one-word judge on 250 held-out items, , and dividing by gives 0.126: a 95% interval of about ±25 points around 57.9%. For a reasoned judge the same arithmetic gives about ±6 points. A weak judge can be corrected, but only into a wide interval; the cheap way to a tight estimate is a better judge, not a cleverer correction. Drag the catch and pass rates toward 50% in the first figure and watch the corrected bar lose its meaning.
How many labels a judge needs
The intervals also tell you how much labeling to budget. To pin a recall near 0.9 to within ±5 points at 95%, solve :
That is 139 items of the class whose recall you are measuring: 139 wrong answers to estimate , and separately enough right answers to estimate . A labeled set that is 90% right answers gives you a precise and almost nothing on , which is usually the recall you care about.
Collect a few hundred items with trusted labels, stratified so each class you care about has the count the formula above asks for.
Fix the model id, prompt, settings and output parsing. Record them with the results, and record whether the judge's replies actually had the format you asked for.
Report and with Wilson or Clopper–Pearson intervals, and kappa with a bootstrap interval. Compare judge variants on the same items with McNemar's test.
Promote a judge only if its recalls meet the bar you wrote down first. If you must use a weak judge, report its corrected rate with the -inflated interval, never its raw score.
The corrected rate is (0.30 + 0.60 − 1) / (0.90 + 0.60 − 1) = −0.10 / 0.50, which clips to zero: a judge that flags 40% of right answers would flag at least 40% of a batch with no errors, so a 30% report is less than it produces on a clean batch. With J = 0.5, every point of noise in the report becomes two points in the corrected rate.
What would change these conclusions
- The task is easy to verify. GSM8K answers are single numbers, and a judge that re-solves the problem can check them. On open-ended tasks (summaries, code review, safety) re-solving is not available, and the gap between terse and reasoned judges may be different in size, or reversed.
- GSM8K is public. Both models may have seen these problems in training, which would make re-solving easier than it is on your data.
- One run. Haiku ran at temperature 0; Sonnet 5.5 accepts no temperature setting, so its verdicts carry sampling noise that a second run would reveal. The intervals cover sampling of items, not of the models' replies.
- The answers came from one model. Every answer was Haiku's, written without working. A judge grading its own model's mistakes may behave differently from one grading another model's.
Why this matters in a lab
Frontier labs grade a large share of their evaluations with models, and every number that comes out of those evaluations inherits the judge's two recalls. A reported regression can be a change in the model under test, or a change in how often the judge flags right answers. The skill a lab needs is the one this article measures: turning a judge from a black box that emits a score into an instrument with a known catch rate, a known false-alarm rate, intervals on both, and a correction whose uncertainty you can state.
An interviewer might ask: your judge's pass rate on correct answers dropped from 99% to 90% after a prompt change; what happens to the error rates you reported last quarter? The answer is the first equation, and the interval is the last one.
A worked answer to the interview question
Each error rate you reported came from the judge's two recalls, through . Lowering from 0.99 to 0.90 adds to without any change in the model under test: on a suite where 20% of answers are wrong, that is 7.2 points of phantom regression. So last quarter's numbers are not comparable with this quarter's until you re-measure both recalls on a labeled set and report the corrected rates, each with its -inflated interval. Then fix the prompt change, or version the judge alongside the model, so the comparison is made with one instrument.
The book builds the evaluation harness these statistics come from, and runs it on Claude.


