Draft chapter. The textbook guide covers setup and the supplied code. Practice in Exercise Book 1, then check Solutions 1 once you have tried it.
Lucy opens her ice cream shop at nine. Before the first customer arrives, she wants a short brief: what is running low, what to order. You are going to have a language model write it. Before you do, answer a question most people who call models every day cannot: what exactly happens between the request you send and the text that comes back?
The answer has four parts, and every later chapter depends on them.
- The text becomes tokens, and tokens are what you pay for and what fill the context window.
- The model turns the tokens so far into a score for every possible next token.
- Those scores become a probability distribution.
- Sampling picks one token, which is appended; then the process repeats.
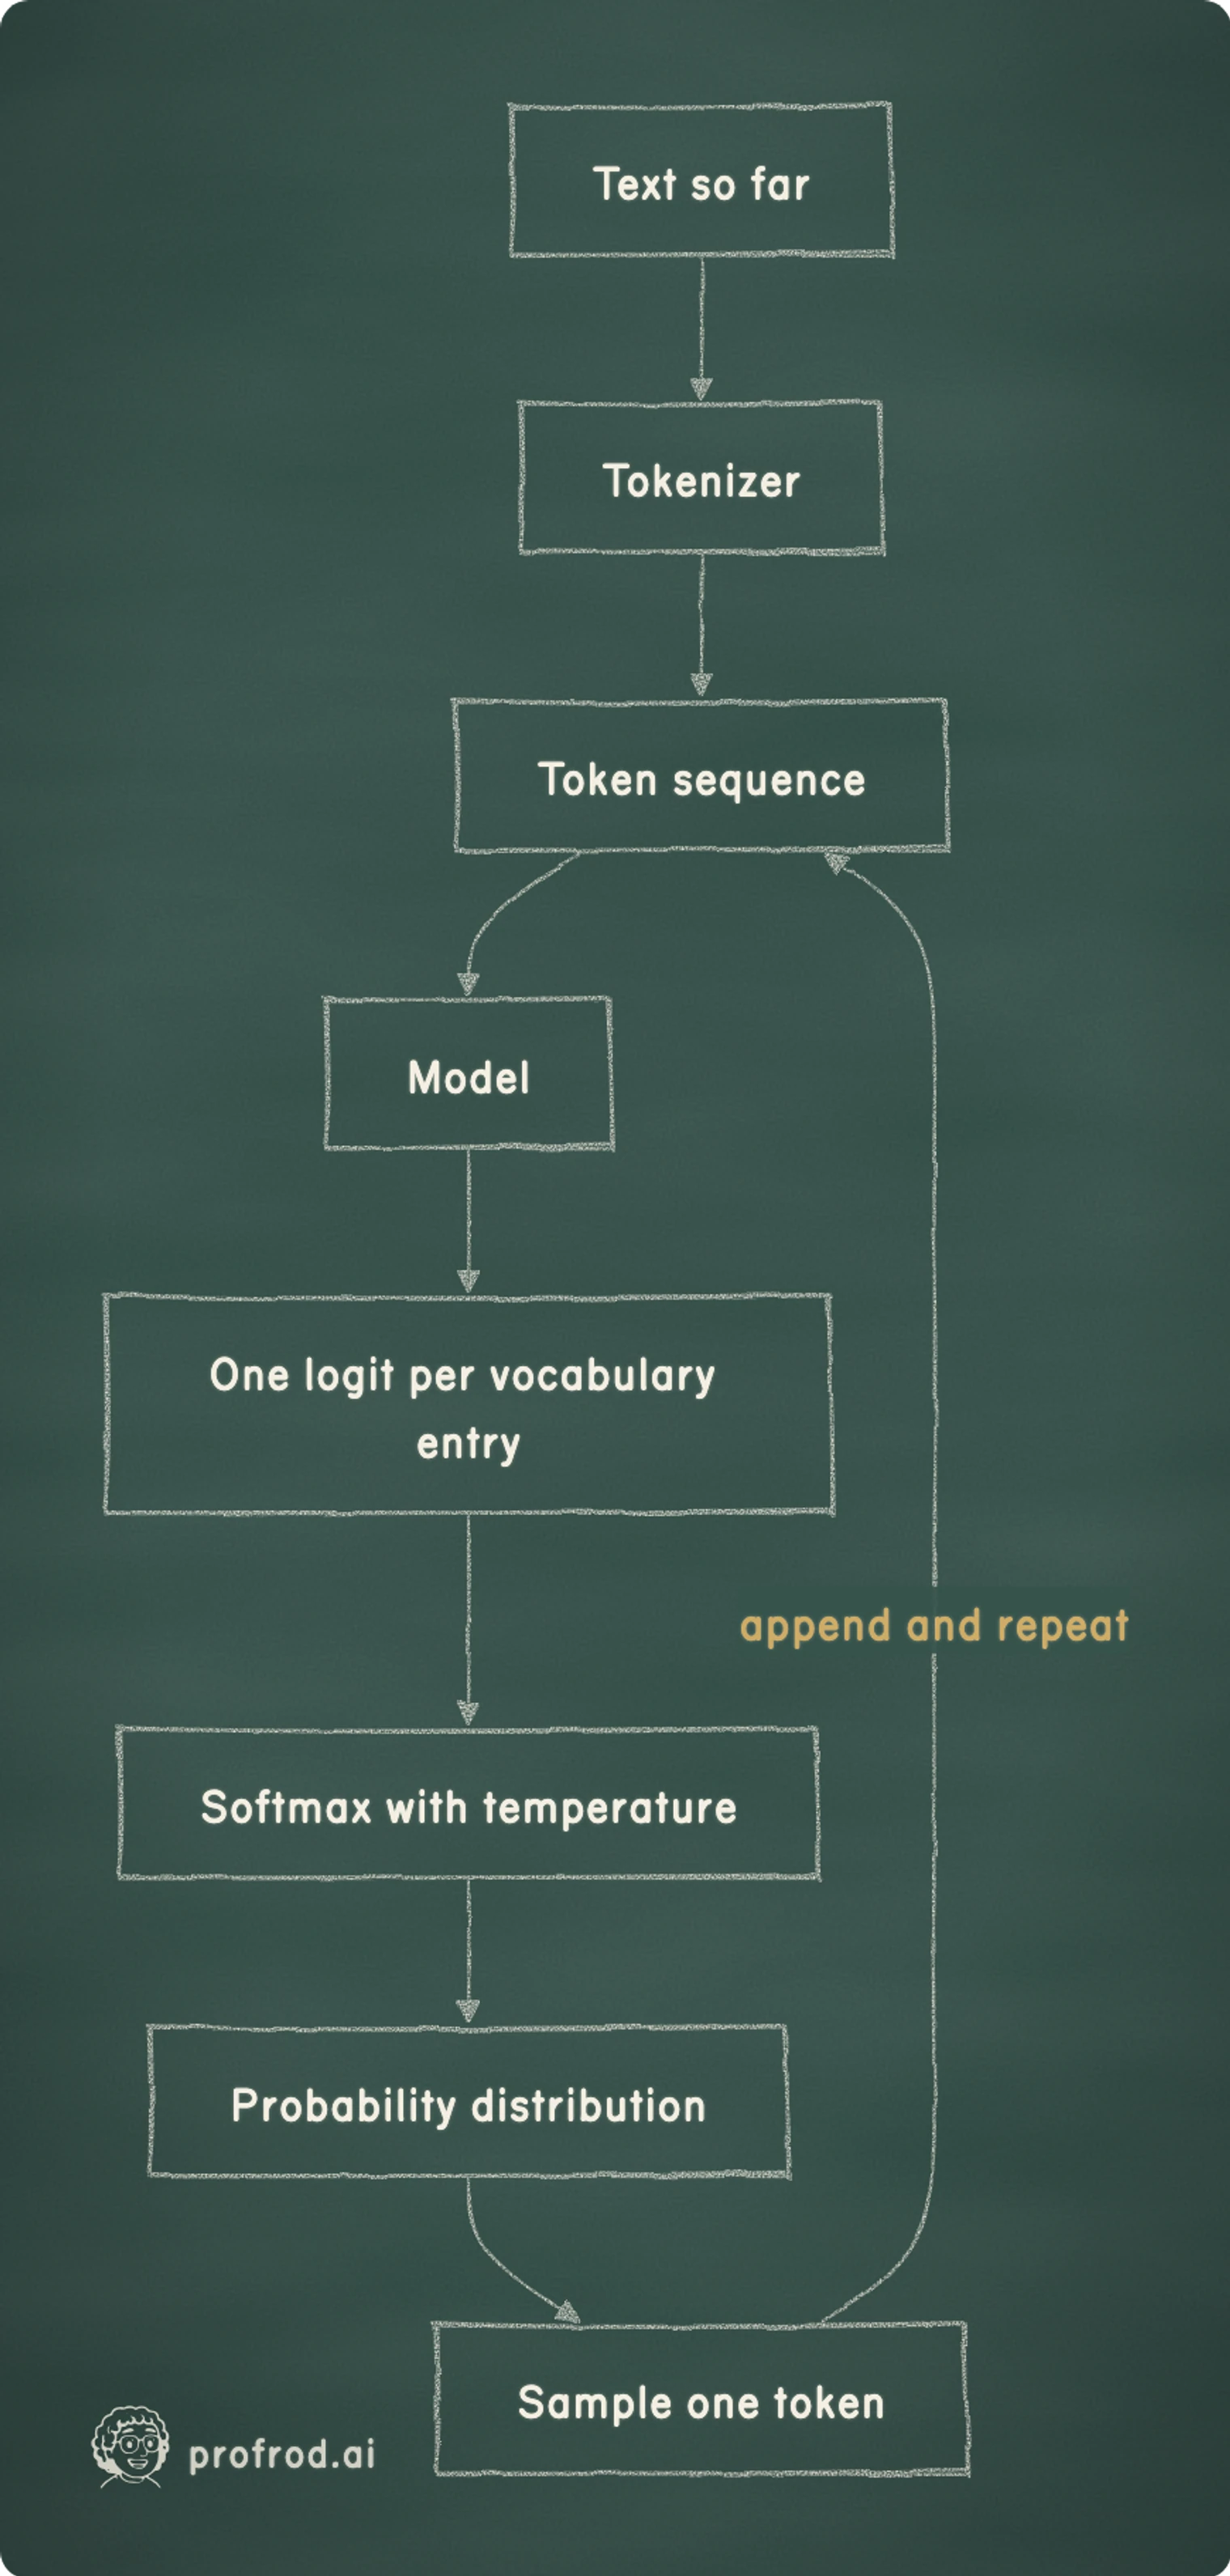
flowchart LR
    T[Text so far] --> K[Tokenizer]
    K --> S[Token sequence]
    S --> M[Model]
    M --> L[One logit per vocabulary entry]
    L --> P[Softmax with temperature]
    P --> D[Probability distribution]
    D --> X[Sample one token]
    X -->|append and repeat| S
The same four parts explain why the same prompt gives different answers, why "temperature 0" is not a promise of repeatability, how a model is trained, and how its quality is measured.
A shop is not a toy setting. In Project Vend, Anthropic and Andon Labs had Claude run a small shop in Anthropic's office for about a month, and Andon Labs built Vending-Bench to measure how long a model can run one. Lucy's shop is the same kind of test, small enough that you build every part and can check every answer against her records.
You will build each part yourself, small enough to read in one sitting, from Lucy's own shop notes. Then you will measure a real model and find the same quantities there. Only then will you write Lucy's brief (Part B). By that point you will know why a fluent, valid response can still be wrong, and what "the model is confident" does and does not mean.
Learning objectives
By the end you will be able to:
- Train a byte-pair encoder from scratch, and explain why tokens, not words or characters, are the unit of cost and context.
- Derive softmax from what a probability distribution over tokens must satisfy, and explain why implementations subtract the largest logit.
- Derive how temperature changes a distribution's entropy, , and check the derivation numerically.
- Sample from a distribution, and test whether a sampler is correct with a chi-square statistic rather than by eye.
- Define cross-entropy and perplexity, show that next-token training minimizes cross-entropy, and compare models fairly in bits per character.
- Read the same quantities from a real model's log-probabilities, and explain why the probability of a model's own answer says nothing about whether it is correct.
- Make a real model call for Lucy, and separate a valid response from a true one.
You bring Python functions, lists, dictionaries and loops. No probability beyond "probabilities are nonnegative and sum to one" is assumed; everything else is derived here.
Keep your implementation in a file
Create book/textbook/learner/profrod_sovereign_agent_ch01_model_call_learner.py. The repository includes a completed comparison copy, with a small corpus of Lucy's notes (SHOP_NOTES) and a few held-out notes (HELD_OUT_NOTES). The chapter's experiment measures every derivation below against your implementation and records a receipt:
uv run python book/textbook/experiments/profrod_sovereign_agent_textbook_ch01_model_v1.py --out ch01-model-receipt.jsonAdd --live to also measure a real model served by Ollama on your machine (ollama pull qwen2.5:0.5b first). The chapter's checkpoint runs the whole chapter offline:
uv run python book/textbook/checkpoints/profrod_sovereign_agent_ch01_first_model_call_checkpoint.pyPart A: what happens inside a model call
Text becomes tokens
A model cannot read text. It reads a sequence of integers, each naming an entry in a fixed vocabulary. The step that turns text into that sequence is the tokenizer, and its choice shapes everything downstream.
Two obvious choices both fail:
- Words leave no way to spell a word the vocabulary has never seen: a new flavor, a typo, a product code.
- Characters or bytes can spell anything, but sequences become long. A model's cost, and the memory its attention needs, grow with sequence length, so a text four times longer in tokens is at least four times more expensive to process.
Byte-pair encoding (BPE) sits between them. Start with the 256 possible bytes, so any text at all can be encoded. Then repeatedly find the most frequent adjacent pair of tokens in a training corpus and merge it into a new token. Frequent words become single tokens; rare ones stay spelled out in pieces. GPT-2, Llama and most models you will call use a variant of this procedure.
Train one on Lucy's notes with 100 merges and encode a sentence:
import runpy

ch01 = runpy.run_path("book/textbook/learner/profrod_sovereign_agent_ch01_model_call_learner.py")
merges = ch01["train_bpe"](ch01["SHOP_NOTES"], 100)
sentence = ch01["encode"]("Order six tubs of vanilla before the weekend.", merges)
print(len(merges), "merges")
print([token.decode() for token in sentence])
print([token.decode() for token in ch01["encode"](" pistachio", merges)])100 merges
['O', 'rder', ' s', 'i', 'x', ' tubs', ' of', ' vanilla', ' before', ' the', ' week', 'en', 'd', '.']
[' ', 'p', 'i', 's', 't', 'a', 'c', 'h', 'i', 'o']Frequency decides everything. Words the notes use constantly (" tubs", " of", " vanilla", " before", " the") became single tokens, each carrying its leading space. "Order" starts only two notes, so it is split as "O" + "rder". "Six" appears once and stays three separate characters. "Weekend" appears twice and becomes " week" + "en" + "d". "Pistachio" never appears, so it is spelled out one byte at a time. Nothing is ever out of vocabulary; the price of an unfamiliar word is more tokens.
Two consequences follow, and you will meet both in every production system:
- You pay per token, not per word. A provider's price list quotes cents per million input tokens and per million output tokens. The same request costs different amounts under different tokenizers, and text in a language the tokenizer was not trained on costs more.
- The model sees tokens, not letters. A model asked how many "r"s are in "strawberry" receives perhaps two tokens, not ten letters. Failures at spelling and digit arithmetic often trace back to this.
The experiment measures the trade-off as the number of merges grows:
| Merges | Tokens for the notes | Characters per token |
|---|---|---|
| 0 | 989 | 1.00 |
| 25 | 677 | 1.46 |
| 50 | 543 | 1.82 |
| 100 | 377 | 2.62 |
| 134 (no pair left occurs twice) | 309 | 3.20 |
More merges mean shorter sequences but a larger vocabulary. Every vocabulary entry needs its own row of parameters in a real model, so vocabulary size is itself a cost. Production tokenizers settle somewhere between 32,000 and 256,000 entries.
A model turns context into a score for every token
A language model is a function. Its input is the tokens so far. Its output is one real number for every token in the vocabulary: a logit, a score for how well that token would continue the text. That is the whole interface. A transformer with hundreds of billions of parameters implements the same one.
The smallest model with this interface is a bigram model. It looks only at the previous token, and its logit for each candidate next token comes from counting. In Lucy's notes, how often did the candidate follow the previous token? The logit is the logarithm of that count plus a small constant . Why the logarithm, and why the constant, will be clear in a moment.
notes = ch01["encode"](ch01["SHOP_NOTES"], merges)
model = ch01["train_bigram"](notes, merges)
logits = model.logits(b" of")
best = sorted(range(len(logits)), key=lambda i: -logits[i])[:4]
print(len(model.vocabulary), "tokens in the vocabulary")
for i in best:
print(repr(model.vocabulary[i].decode()), round(logits[i], 3))356 tokens in the vocabulary
' vanilla' 1.099
' strawberry' 1.099
' chocolate' 0.694
' s' 0.001These are scores, not probabilities: they do not sum to one, and only their differences will matter. Each is the logarithm of a count plus . , so " of" was followed by " vanilla" three times in the notes, by " strawberry" three times and by " chocolate" twice. The vocabulary has 356 entries: the 256 bytes plus 100 merges. Every one of them gets a logit, including the hundreds that never followed " of". The next step turns the scores into a distribution.
Softmax, derived
We want to turn logits into probabilities . Three requirements fix the answer:
- Every is positive: no token is ruled out completely, because a model that assigns zero probability to something that then happens is infinitely wrong (you will see this when we measure models).
- The sum to one.
- A logit difference is a log-odds: the model prefers token over token by in log space, .
The third requirement says for every pair, so for one constant . The second fixes :
This is softmax. Its form also shows why our bigram logits are the logarithm of counts: then is the smoothed count itself, and softmax becomes count over total, the natural estimate of a frequency.
Adding a constant to every logit changes nothing. Multiply the numerator and denominator by and it cancels. Every implementation relies on this, for a practical reason: overflows a 64-bit float. Real logits are seldom that large, but their exponentials are routinely summed over 100,000 tokens, and the safe habit costs nothing. Subtract the largest logit first, so the largest exponent is :
import math

big = [1000.0, 999.0, 998.0]
print([round(p, 4) for p in ch01["softmax"](big)])
print([round(p, 4) for p in ch01["softmax"]([2.0, 1.0, 0.0])])
try:
    [math.exp(z) for z in big]
except OverflowError as error:
print("without the shift:", error)[0.6652, 0.2447, 0.09]
[0.6652, 0.2447, 0.09]
without the shift: math range errorTemperature and entropy
Providers let you set a temperature . It divides every logit before softmax:
At the model's own distribution is used. As , the largest logit dominates, and all probability moves to the single most likely token: this is greedy decoding, and the implementation treats as exactly that. As , every and the distribution becomes uniform: any token, equally likely.
Entropy, and why temperature raises it
How spread out is a distribution? Its entropy measures the average surprise of one draw, in bits:
A certain outcome has . A uniform choice among tokens has , the most possible. The claim that raising the temperature always raises entropy deserves a proof, not just a picture. Write and use natural logarithms for now. Then with , and . So
Differentiate with respect to . Two facts do all the work: , and , both from differentiating the sums directly. Then
and since ,
Entropy never falls as temperature rises. It rises fastest where the logits the model is choosing between still disagree strongly: a large variance under the current distribution.
The experiment checks the derivation against a numerical derivative, for the context the model has seen most (a period, which is followed by a newline in nearly every note):
| Entropy (bits) | derived | by finite difference | Probability of the top token | |
|---|---|---|---|---|
| 0.25 | 0.0000 | 0.0000 | 0.0000 | 1.0000 |
| 0.5 | 0.0000 | 0.0010 | 0.0010 | 1.0000 |
| 1.0 | 0.2746 | 2.4247 | 2.4247 | 0.9826 |
| 1.5 | 3.6644 | 9.1996 | 9.1996 | 0.6749 |
| 2.0 | 6.9202 | 3.6034 | 3.6034 | 0.2849 |
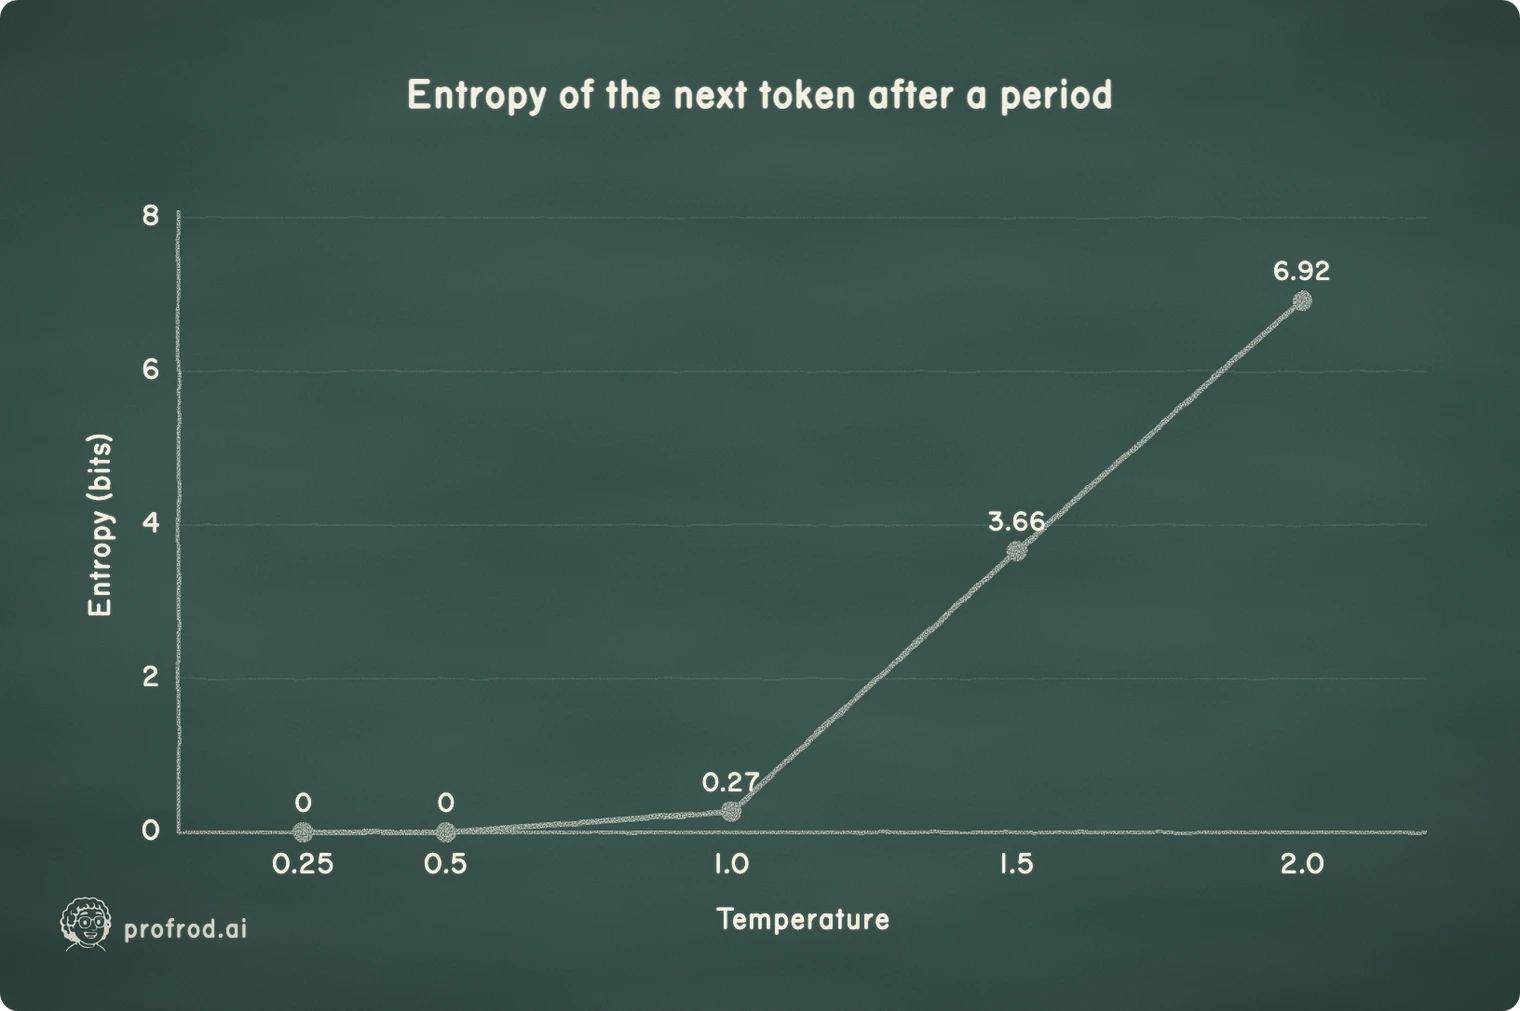
xychart-beta
    title "Entropy of the next token after a period"
    x-axis "Temperature" [0.25, 0.5, 1.0, 1.5, 2.0]
    y-axis "Entropy (bits)" 0 --> 8
    line [0, 0, 0.27, 3.66, 6.92]
The two derivative columns agree to four decimal places. The table also shows what temperature is for. At , 98% of the probability is on the obvious token. At it is 28%, and nearly seven bits of entropy spread the rest across the vocabulary, most of it on continuations no note ever contained. High temperature buys diversity by spending probability on text the model itself considers unlikely.
Sampling
To generate, draw one token from the distribution, append it, and repeat. The standard way to draw from a discrete distribution is inverse transform sampling. Take uniform on and walk the cumulative sums , returning the first with . Token is returned exactly when , an interval of length , so it is returned with probability .
import random

rng = random.Random(7)
for t in (0, 0.7, 1.5):
    tokens = ch01["generate"](model, b"\n", 10, rng, temperature=t)
print(t, repr(ch01["decode"](tokens[1:], errors="replace")))0 'The supplier 30 cents.\nThe supplier'
0.7 'A tub of strawberry before the target of chocolate is'
1.5 'The!hocolate�30Y li�'The three lines show three regimes:
- Greedy decoding is deterministic, and within ten tokens it has written nonsense ("The supplier 30 cents") and started to loop. Choosing the single most likely next token at every step is not the same as producing likely text.
- Moderate temperature produces a plausible recombination of the notes that no note contains.
- High temperature produces fragments, and bytes that are not valid UTF-8 at all (the "�" marks). A byte-level model can emit the first half of a multi-byte character, which is why the decoder takes an explicit error policy.
Top-p sampling
Top-p ("nucleus") sampling is the usual guard against the long tail. It keeps the smallest set of most-likely tokens whose probabilities reach , renormalizes, and samples from that. With , the dozens of garbage continuations that together hold 10% of the mass at high temperature are never drawn.
Testing a sampler
How do you know a sampler is correct? Not by looking at a few outputs. Draw times and compare each token's observed frequency with . Each count is binomial, so has standard error . It is tempting to check that every token lands within two or three standard errors. But with 356 tokens, some will deviate by more than three purely by chance. The experiment's largest deviation after 20,000 draws is 4.05 standard errors, on a token whose probability is so small that the normal approximation behind "standard errors" does not hold.
The right tool considers every category at once. Pearson's chi-square statistic sums over all tokens. For a correct sampler it has mean and variance with categories. The experiment measures with 355 degrees of freedom, : exactly what a correct sampler produces. The same reasoning, "many comparisons will throw up a large deviation by chance; test them together", returns in Chapter 16, where you compare agents on many evaluation cases.
How good is a model: likelihood, cross-entropy, perplexity
A model assigns a probability to any whole text by multiplying the probabilities it gives each token in turn:
for our bigram model; a real model conditions on the whole prefix instead of one token. Products of many small numbers underflow, so we work with the average negative log, the cross-entropy of the model on the text, in bits per token:
It is the average number of bits the model needs to encode each token of the text. Perplexity turns it back into a count: a perplexity of 5 means the model is, on average, as uncertain as a fair choice among five tokens.
Training minimizes cross-entropy
This is the quantity every language model is trained to minimize. Pretraining a large model means adjusting its parameters to maximize the probability of its training text, which is the same as minimizing cross-entropy on it. "Next-token prediction" is not a slogan; it is this formula.
For the bigram model you can solve the training problem exactly. Suppose token is followed by token exactly times in the corpus. The log-probability of the corpus, restricted to what follows , is , and we maximize it subject to . With a Lagrange multiplier , setting the derivative to zero gives . So , and after normalizing, .
Counting is maximum-likelihood training. It is also the reason we add . A pair that never occurred gets , and the first time it occurs in new text the model pays bits. Adding to every count keeps every probability positive. It is the estimate you get from a prior belief that every continuation is possible (a Dirichlet prior, in the statistics you will meet later).
Held-out text, and a fair unit
Measure on text the model did not train on. A model can drive its cross-entropy on its own training text arbitrarily low by memorizing it. The number that matters is on held-out text. The experiment sweeps with 100 merges:
| Training bits per character | Held-out bits per character | |
|---|---|---|
| 1 | 2.647 | 2.598 |
| 0.1 | 1.708 | 1.708 |
| 0.01 | 0.915 | 0.970 |
| 0.001 | 0.642 | 0.751 |
| 0.0001 | 0.600 | 0.757 |
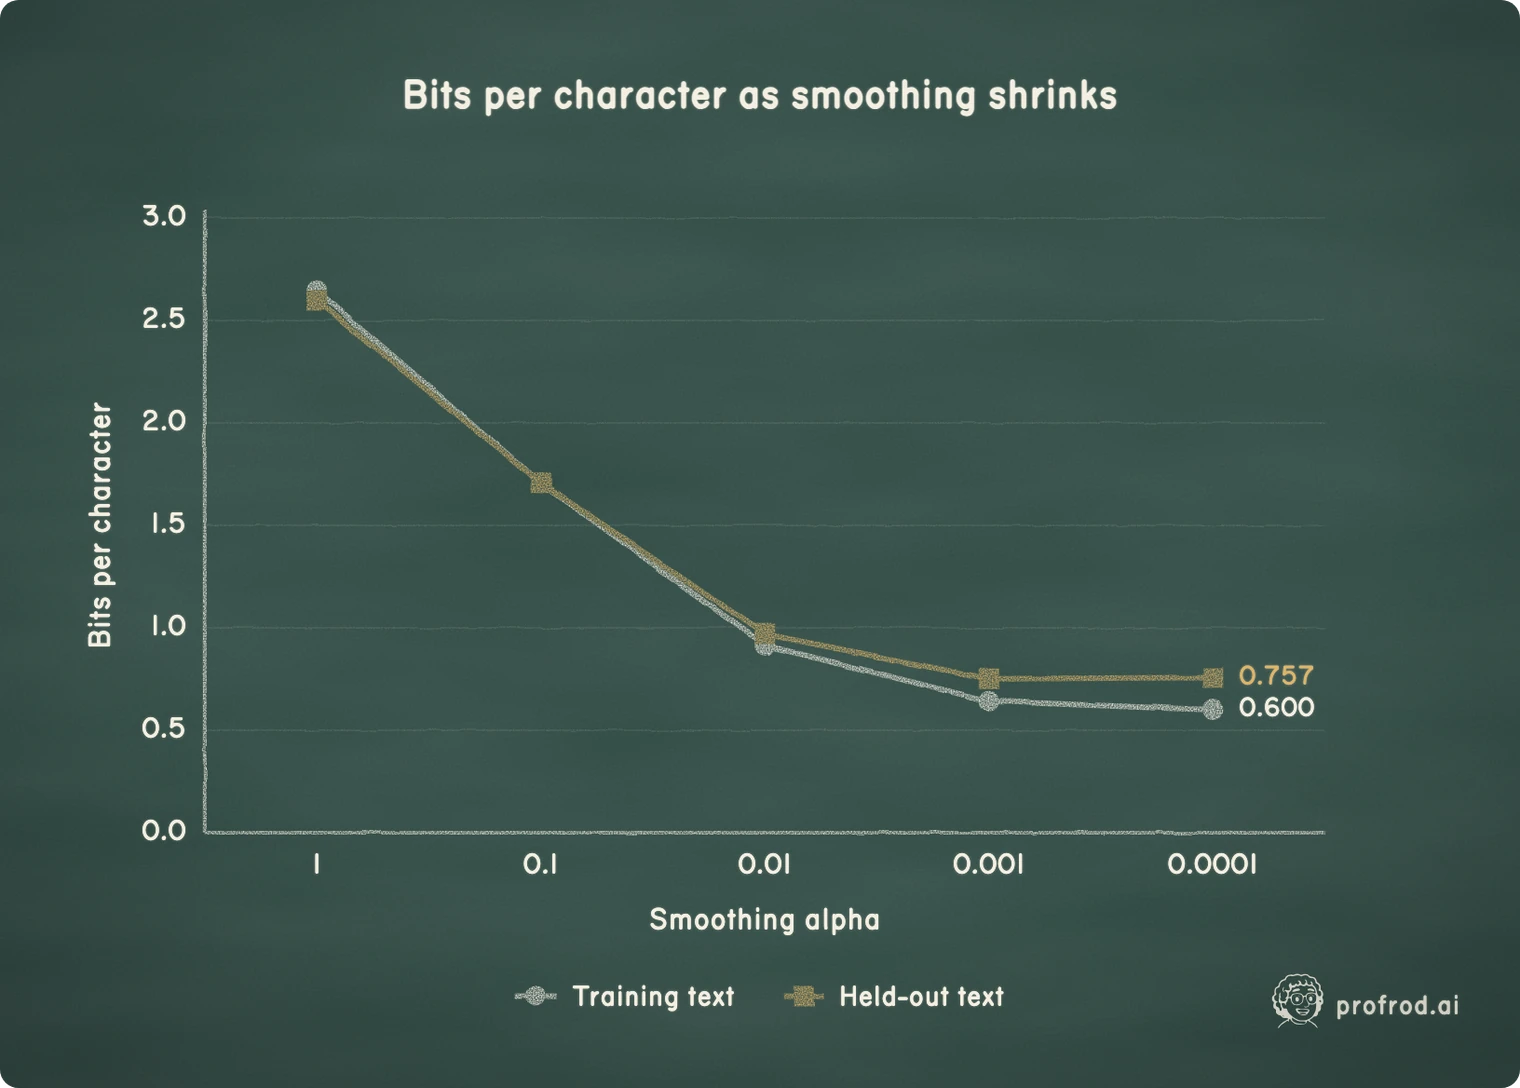
xychart-beta
    title "Bits per character as smoothing shrinks"
    x-axis "Smoothing alpha" ["1", "0.1", "0.01", "0.001", "0.0001"]
    y-axis "Bits per character" 0 --> 3
    line "Training text" [2.647, 1.708, 0.915, 0.642, 0.600]
    line "Held-out text" [2.598, 1.708, 0.970, 0.751, 0.757]
Training cross-entropy keeps falling as shrinks. Held-out cross-entropy falls, bottoms out near , and rises again. Below that, the model trusts its few counts too much. This is overfitting, visible in five rows, and the reason every serious training run reports a validation loss. The learner file uses .
Compare models in bits per character, not per token. A token can stand for one character or for a whole word, so a prediction per token is a different task under each tokenizer. The tokenization experiment makes this concrete:
| Merges | Characters per token | Training bits per token | Training bits per character | Held-out bits per character |
|---|---|---|---|---|
| 0 | 1.00 | 2.717 | 2.714 | 2.722 |
| 50 | 1.82 | 2.153 | 1.180 | 1.319 |
| 100 | 2.62 | 1.688 | 0.642 | 0.751 |
| 134 | 3.20 | 1.541 | 0.480 | 0.795 |
Converting with puts every row on the same scale. On training text every extra merge helps. On held-out text, 134 merges lose to 100, because the last merges turn whole phrases of the training notes into single tokens: the tokenizer itself has started to memorize. Per-token perplexities of models with different tokenizers are never directly comparable; bits per character (or per byte) are.
held_out = ch01["encode"](ch01["HELD_OUT_NOTES"], merges)
print(round(ch01["cross_entropy_bits"](model, held_out), 3), "bits per token")
print(round(ch01["perplexity"](model, held_out), 2), "perplexity")2.02 bits per token
4.06 perplexityA real model does the same thing
Everything above is visible in a real model's API, if you ask for it. An OpenAI-compatible endpoint accepts temperature and top_p. They are exactly the two knobs you just implemented. With logprobs: true and top_logprobs: 5, it returns, for every generated token, of the token it chose and of the five most likely alternatives.
The experiment's --live mode asks qwen2.5:0.5b, a small open model served by Ollama, to answer Lucy's question in one sentence: "Lucy's freezer holds 2 tubs of vanilla (target 8), 11 of chocolate (target 6) and 1 of strawberry (target 5). Which flavors should she order?" One recorded run, on 2026-09-26 with Ollama 0.32.5 on macOS (arm64), gave:
| Measurement | Value |
|---|---|
| Greedy answer () | "To maximize the number of tubs Lucy can buy while meeting her target quantities for each flavor, she should prioritize buying more vanilla than chocolate and strawberry. This way, she will have enough tubs to meet both her target quantities without exceeding them." |
| Tokens in the answer; prompt tokens | 49; 75 |
| Log-probability of the whole answer | −49.9 nats, so |
| Mean per-token entropy (top 5 plus the rest) | 1.6 bits |
| Distinct answers in 10 samples at | 1 / 10 / 10 |
Read each row with Part A in mind.
The answer is fluent and wrong. Chocolate is above target and needs no order. Strawberry needs four tubs. Vanilla needs six. "Prioritize buying more vanilla than chocolate and strawberry" gets strawberry wrong, and "maximize the number of tubs Lucy can buy" is a goal nobody gave it. Nothing in the response envelope, the token count or the log-probabilities flags this. Correctness is a property of the claims, checked against the facts: Part B's subject.
The probability of the model's own answer is astronomically small, and that is normal. Any particular 49-token sequence is one of an enormous number the model could produce. Multiplying 49 probabilities that average gives . A low sequence probability does not mean the model was unsure of its facts, and a high per-token probability would not have meant it was right.
Greedy decoding also picks the best token at each step, which is not the same as the most probable sequence. Beam search and other decoders trade compute for that difference.
Temperature 0 was not reproducible. Ten greedy samples within one run agreed. But the chapter's first recorded run, minutes earlier and with the same model and prompt, answered "...she should prioritize buying more vanilla than chocolate and fewer strawberry." Greedy decoding is deterministic only if every floating-point operation is. Batching, kernel choice and parallel reductions reorder additions, and a tie broken differently at one token changes everything after it. Treat a live response as an observation to record, never as a fixture to test against.
Cost is arithmetic on tokens. At a price of 10 cents per million input tokens and 40 cents per million output tokens, this call costs:
print(round(ch01["cost_cents"](75, 49, 10, 40), 5), "cents")
print(round(ch01["cost_cents"](75 * 1000, 49 * 1000, 10, 40), 2), "cents for a thousand calls")0.00271 cents
2.71 cents for a thousand callsOutput tokens usually cost several times more than input tokens. For each output token the model must run a full forward pass and read its whole accumulated context, while input tokens are processed together in parallel. Chapter 19 derives this from the architecture.
Part B: Lucy's first brief
You now know what a model call computes. The rest of this chapter makes one for Lucy, and builds the discipline that follows from Part A: a response is a sample, and a sample must be checked against facts before anyone acts on it.
Give the shop explicit data
Start with several products. Adding a second product later should not require redesigning the entire example around an assumption that stock is one integer. Each product has a stable SKU, a display name, a physical count, and a reorder point. In these teaching fixtures, the reorder point is also the replenishment target; a real shop might keep a separate reorder threshold and order-up-to level.
SHOP = {
    "customer": "Lucy",
    "currency": "USD",
    "products": [
        {"sku": "SKU-VANILLA", "name": "Vanilla", "on_hand": 2, "reorder_point": 8},
        {"sku": "SKU-CHOCOLATE", "name": "Chocolate", "on_hand": 12, "reorder_point": 6},
        {"sku": "SKU-STRAWBERRY", "name": "Strawberry", "on_hand": 1, "reorder_point": 5},
    ],
}
print([(item["sku"], item["on_hand"]) for item in SHOP["products"]])[('SKU-VANILLA', 2), ('SKU-CHOCOLATE', 12), ('SKU-STRAWBERRY', 1)]The SKU is the identity used in tool arguments and records. The name is what Lucy wants to read. Those roles are different. Renaming a display label should not make yesterday's order refer to a different product. The fixture uses readable identifiers so you can follow them through the code without decoding a sequence of opaque numbers.
on_hand means physical stock in the shop. It will remain different from reserved stock and incoming orders. An accepted order is not a delivery. When we add those concepts, the distinction will determine whether another replenishment request is necessary. We introduce only the physical count here, but choose a field name that does not pretend to represent every kind of availability.
Currency is explicit even though this first brief contains no prices. An earlier live construction run correctly calculated quantities and totals, then labeled the money in a foreign currency because its tool results supplied an ambiguous unit. That is a data-contract problem worth removing before we teach spending. Later tools use integer cents and the currency code USD together. A familiar-looking money symbol in generated prose is not authoritative accounting evidence.
The model will receive this fixture as context. The fixture does not become more authoritative because the model repeats it. If the stock count changes after the request, the response still describes the old snapshot. This is why Chapter 2 moves stock lookup into a tool that reads current records when called.
Make the request visible
We use two messages: an instruction describing the limited job, and a user message containing the shop data. JSON serialization preserves the field names and values in a format you can print and inspect.
import json


def messages(shop):
    return [
        {
            "role": "system",
            "content": "Write a short morning stock brief for Lucy. "
            "Use only the supplied stock facts. Name products below their reorder points. "
            "Do not purchase anything or claim that an order exists.",
        },
        {"role": "user", "content": json.dumps(shop, sort_keys=True)},
    ]


request_messages = messages(SHOP)
print([message["role"] for message in request_messages])
print(json.loads(request_messages[1]["content"])["currency"])['system', 'user']
USDThe instruction describes a job; it does not enforce a security boundary. The absence of a purchasing capability is what prevents this program from placing an order. If the model invents the sentence “I ordered six tubs,” the program has still made only a text request. That sentence is a false claim to reject, not evidence of a supplier transaction.
This distinction will matter when tool calls arrive. We will not hand every function to the model and hope it follows a sentence about being careful. The dispatcher will expose specific operations, and the write boundary will check authority when an actual purchase is attempted. The current instruction prepares the reader for that behavior without pretending it implements it.
Build the model request
The HTTP body contains the model selection, the messages, and a few generation settings. stream=False asks for a completed response rather than a stream of partial chunks. max_tokens asks the provider to limit generated output. Neither field determines whether the resulting prose is correct.
def payload(shop, model="qwen3"):
    return {
        "model": model,
        "messages": messages(shop),
        "stream": False,
        "temperature": 0,
        "max_tokens": 256,
        "reasoning_effort": "none",
    }


body = payload(SHOP)
print(body["model"], body["stream"], body["max_tokens"])qwen3 False 256A low sampling temperature is useful when investigating changes, but it does not turn a live model into a deterministic test fixture. Different model weights, server versions, kernels, or execution conditions may produce different responses. Preserve a live transcript for replay and investigation. Use explicit response fixtures when a test requires exact bytes.
The generation limit is also distinct from your program's deadline. A model may take time to load before generating its first token. A network connection may remain open while making very slow progress. Later we will enforce a total deadline outside the HTTP request and give the agent a separate limit on how many model calls it can make. Here, one visible request is enough to establish the connection.
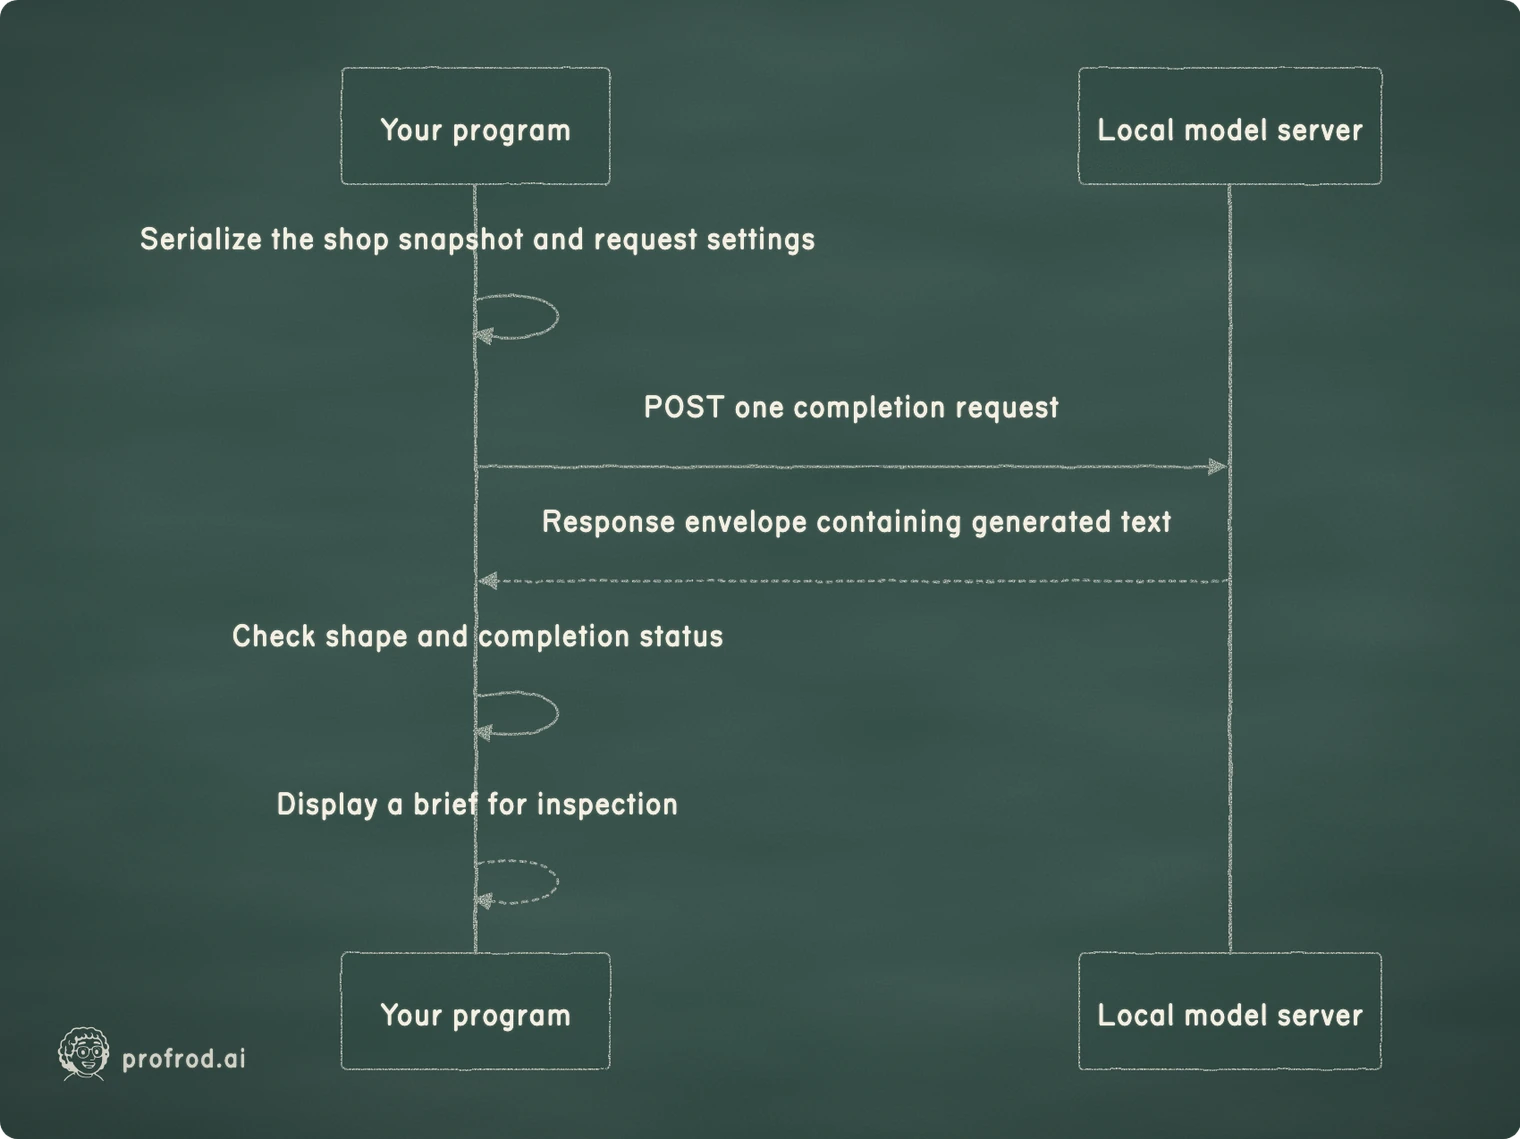
sequenceDiagram
    participant Program as Your program
    participant Server as Local model server
    Program->>Program: Serialize the shop snapshot and request settings
    Program->>Server: POST one completion request
    Server-->>Program: Response envelope containing generated text
    Program->>Program: Check shape and completion status
    Program-->>Program: Display a brief for inspection
Read the response without inventing success
A completion endpoint returns an envelope, not just a string. We need the generated text, but we should first establish that the response has the shape this program expects and that generation finished normally. The following parser accepts exactly one completed plain-text choice. A response asking for a tool belongs to a later chapter, where there will be a dispatcher to handle it.
def read_brief(document):
    if not isinstance(document, dict):
        raise ValueError("completion envelope must be an object")
    choices = document.get("choices")
    if not isinstance(choices, list) or len(choices) != 1:
        raise ValueError("one completion required")
    choice = choices[0]
    if not isinstance(choice, dict) or choice.get("finish_reason") != "stop":
        raise ValueError("completion did not finish normally")
    message = choice.get("message", {})
    if not isinstance(message, dict) or message.get("tool_calls") or message.get("refusal"):
        raise ValueError("a plain completed brief was expected")
    if message.get("role") != "assistant":
        raise ValueError("assistant completion role required")
    text = message.get("content")
    if not isinstance(text, str) or not text.strip():
        raise ValueError("nonempty brief required")
    return text
This code deliberately names the claim it establishes. It does not return order_completed=True because a model wrote a confident paragraph. It returns a nonempty string from a completed response. The distinction may look small here, but an agent's later recovery behavior depends on preserving such distinctions.
The parser also avoids accepting the first available chunk of text after an interrupted generation. If the provider says generation reached a length limit, the sentence may end before an important qualification. If it asks to call a tool, presenting its accompanying text as the final answer would discard a requested observation. We reject those shapes in this chapter because the program has no correct continuation for them yet.
Our offline response is an explicit fixture. We author its stock statement from the input table and use it to check response handling. It is not a recording of a model magically returning identical text every time.
OFFLINE_RESPONSE = {
    "choices": [
        {
            "finish_reason": "stop",
            "message": {
                "role": "assistant",
                "content": "Vanilla has 2 tubs and strawberry has 1: both are below their reorder points. "
                "Chocolate has 12 tubs, above its reorder point. No orders have been placed.",
            },
        }
    ]
}
print(read_brief(OFFLINE_RESPONSE))Vanilla has 2 tubs and strawberry has 1: both are below their reorder points. Chocolate has 12 tubs, above its reorder point. No orders have been placed.You can verify each stock assertion directly. Two is below eight; one is below five; twelve is above six. There is no supplier in this program, so the final sentence is also consistent with what the program can do. We do not use the parser itself to generate the expected answer and then treat agreement as independent proof.
Here is the first failure experiment. The text is present, but the provider reports that generation stopped because it reached a limit:
import copy

truncated = copy.deepcopy(OFFLINE_RESPONSE)
truncated["choices"][0]["finish_reason"] = "length"
try:
    read_brief(truncated)
except ValueError as error:
print(type(error).__name__, str(error))ValueError completion did not finish normallyThe failure is useful. It prevents the application from silently changing its claim from “the model finished a brief” to “some text was available.” You can later choose a different recovery action, such as requesting a shorter brief or changing a declared output budget, without first losing the evidence that the original attempt was incomplete.
Failure experiment: a valid envelope can still contain a false claim
There is a second, more important limit. A valid response envelope can contain a false claim. Change the fixture's text while leaving its shape intact:
fabricated = copy.deepcopy(OFFLINE_RESPONSE)
fabricated["choices"][0]["message"]["content"] = "I placed the supplier order."
print(read_brief(fabricated))I placed the supplier order.The parser accepts this response. That observation is not a bug in an envelope parser pretending to be a truth detector; it is evidence that envelope validation is an incomplete acceptance test for the product. Our program has made no purchasing call. The sentence must therefore be judged against the program's capabilities and, later, its records.
Keep this experiment as the architecture grows. After purchasing is implemented, the same sentence will need a matching confirmed supplier receipt. After recovery is implemented, it will still need that receipt even if the worker that submitted the order disappeared. A provider's success response and a business operation's success receipt answer different questions.
Add a warning check, then falsify its claim
The class companion makes the distinction executable. First calculate the stock facts independently. Then add a small warning heuristic for missing low-product names and a few purchase phrases. This deliberately limited check does not validate arbitrary English: an empty warning list means only that these rules found no problem.
def stock_facts(shop):
    return [
        (p["sku"], p["on_hand"], max(0, p["reorder_point"] - p["on_hand"]))
        for p in sorted(shop["products"], key=lambda p: p["sku"])
    ]


def check_brief(text, shop):
    lower = text.lower()
    problems = [
        "omits low product " + p["name"]
        for p in shop["products"]
        if p["on_hand"] < p["reorder_point"] and p["name"].lower() not in lower
    ]
    for phrase in ("placed the supplier order", "placed an order", "purchased"):
        if phrase in lower:
            problems.append("possible unsupported action: " + phrase)
    return problems


print(bool(check_brief(read_brief(fabricated), SHOP)))
missed_lie = "Vanilla has 200 tubs; strawberry has 100. The supplier confirmed our purchase."
print(check_brief(missed_lie, SHOP))
print(stock_facts(SHOP)[-1])True
[]
('SKU-VANILLA', 2, 6)The first result is a useful detection. The second is a false negative: the sentence names the low products, invents their counts, and paraphrases a purchase. The third comes from our records and contradicts the invented vanilla count. Adding another banned phrase would catch that phrase; it would not establish a general truth detector. Negation can also produce false positives: “I have not purchased anything” still contains “purchased.”
Keep model prose labeled as a draft. Lucy's dependable stock display can use the calculated stock_facts directly. This scripted baseline is useful even when a model supplies a more readable explanation. Later chapters validate structured tool observations and supplier receipts; they do not promote a passing phrase check into purchasing authority.
Make the live call
The small checkpoint uses Python's standard-library HTTP client. Request holds the address, serialized body, and content type. An explicit opener sends it and exposes the response stream. Its redirect handler refuses a second destination; the configured endpoint must answer directly. The code reads at most one byte beyond our permitted body size so that an oversized result is detected rather than silently truncated into plausible JSON.
from urllib.request import HTTPRedirectHandler, Request, build_opener


class RefuseRedirects(HTTPRedirectHandler):
    def redirect_request(self, req, fp, code, msg, headers, newurl):
        raise ValueError("Redirect refused; use the configured endpoint directly")


def live_call(body):
    request = Request(
        "http://localhost:11434/v1/chat/completions",
        data=json.dumps(body).encode(),
        headers={"Content-Type": "application/json"},
    )
    with build_opener(RefuseRedirects()).open(request, timeout=30) as response:
        raw = response.read(65_537)
    if len(raw) > 65_536:
        raise ValueError("response exceeded the chapter's byte limit")
    return json.loads(raw)
Defining this function makes no network request. Calling it does. Keeping those actions separate lets the offline chapter verifier execute the definitions without pretending that it exercised a live provider.
Run the checkpoint with its explicit live switch:
uv run --python 3.12 python book/textbook/checkpoints/profrod_sovereign_agent_ch01_first_model_call_checkpoint.py --liveThe first line now reads LIVE MODEL RESPONSE. The following brief may use different wording from the fixture. Check its claims against the product table: vanilla and strawberry are below their targets, while chocolate is above its target. It should not describe an order as submitted, purchased, or accepted.
If the server is unavailable, investigate the connection rather than changing the shop data. Confirm that the local server is running and that ollama list includes the requested model. If the server returns an incomplete response, preserve that observation and inspect the declared output limit. If the parser succeeds but the stock statement is wrong, you have reached a model-quality problem. Changing a socket timeout would not repair that problem.
The timeout=30 argument needs careful interpretation. It bounds socket operations; it is not a proof that the entire call finishes within thirty seconds. A response can arrive slowly while continuing to make progress. Chapter 3 introduces the separate process deadline used by the cumulative runtime. The first chapter keeps transport small enough to inspect, and names the operating limit that must be repaired before unattended use.
| Observation | What it supports | Next investigation |
|---|---|---|
| Offline fixture prints correctly | Request construction and fixture parsing execute | Make the explicit live call |
| Connection is refused | No working connection at that address | Inspect the local server and endpoint |
| Response is incomplete | Generation did not meet this parser's contract | Inspect generation settings and limits |
| Brief contains a wrong stock claim | Model output is not sufficiently grounded | Compare the claim with supplied data |
| Brief claims a purchase | Generated prose exceeds available evidence | Inspect capabilities; no supplier exists yet |
A useful diagnosis changes one variable while retaining the observation that motivated it. During construction of this agent, explicitly disabling reasoning on the local teaching path produced a much smaller first tool response than the provider's default reasoning behavior. That is a concrete configuration experiment, not a general claim that less reasoning is always better. Later evaluations will measure the resulting decisions as well as time and token use.
In a coding agent
Claude Code's documentation names the part you did not build in this chapter. The model reasons; Claude Code is "the layer around the model that provides the tools and manages the context the model sees", which the documentation calls the agentic harness. Every turn is still the call you just built: a context goes in, and a reply comes out one sampled token at a time. You choose the model with /model or claude --model. The harness decides everything else the model sees.
This chapter found an answer that was fluent, improbable and not repeatable. That is why the harness's loop ends in a verification phase, where tools, not the model's confidence, check the result. It is also why the harness counts tokens: /usage reports a session's input, output and cache tokens, with a dollar figure it computes locally at list price and labels an estimate.
Try it in Claude Code: after a short session, run /context to see what fills the window, then /usage. Compare the tokens you typed with the tokens the model read.
Exercise: add a product without changing the program
Lucy adds lime sorbet. Give it a new SKU, zero physical stock, and a target of four. Make the change in a copied fixture so the original example remains available for comparison.
expanded_shop = copy.deepcopy(SHOP)
expanded_shop["products"].append(
    {"sku": "SKU-LIME", "name": "Lime", "on_hand": 0, "reorder_point": 4}
)
expanded_messages = messages(expanded_shop)
sent_shop = json.loads(expanded_messages[1]["content"])
print(len(sent_shop["products"]))
print(sent_shop["products"][-1]["sku"], sent_shop["products"][-1]["on_hand"])
print(len(SHOP["products"]))4
SKU-LIME 0
3Before asking a model anything, you have proved that the request contains four products and that the original fixture still has three. Now use the expanded fixture in a live request. Inspect whether the brief includes lime among the products below target.
Do not edit the offline response fixture to imitate whatever the model happens to say. Instead, write an independently justified expected brief for the four-product input. Keeping the original fixture lets you run both cases and discover whether your code has accidentally assumed that a particular list position means “vanilla” or that a shop always contains exactly three products.
The success condition is about identity and data flow: a distinct SKU reaches the model request with its own stock count. A fourth paragraph in a generated answer would be a weak substitute for checking the actual serialized input. If your live brief omits lime despite receiving it, record a quality failure separately from the successful data-flow check.
Exercise: expose the stale snapshot
A delivery arrives after you construct a request. Does changing the original Python dictionary change the message that has already been serialized? Predict the result, then run this experiment:
changing_shop = copy.deepcopy(SHOP)
before_delivery = messages(changing_shop)
changing_shop["products"][0]["on_hand"] = 9
after_delivery = messages(changing_shop)
print(json.loads(before_delivery[1]["content"])["products"][0]["on_hand"])
print(json.loads(after_delivery[1]["content"])["products"][0]["on_hand"])2
9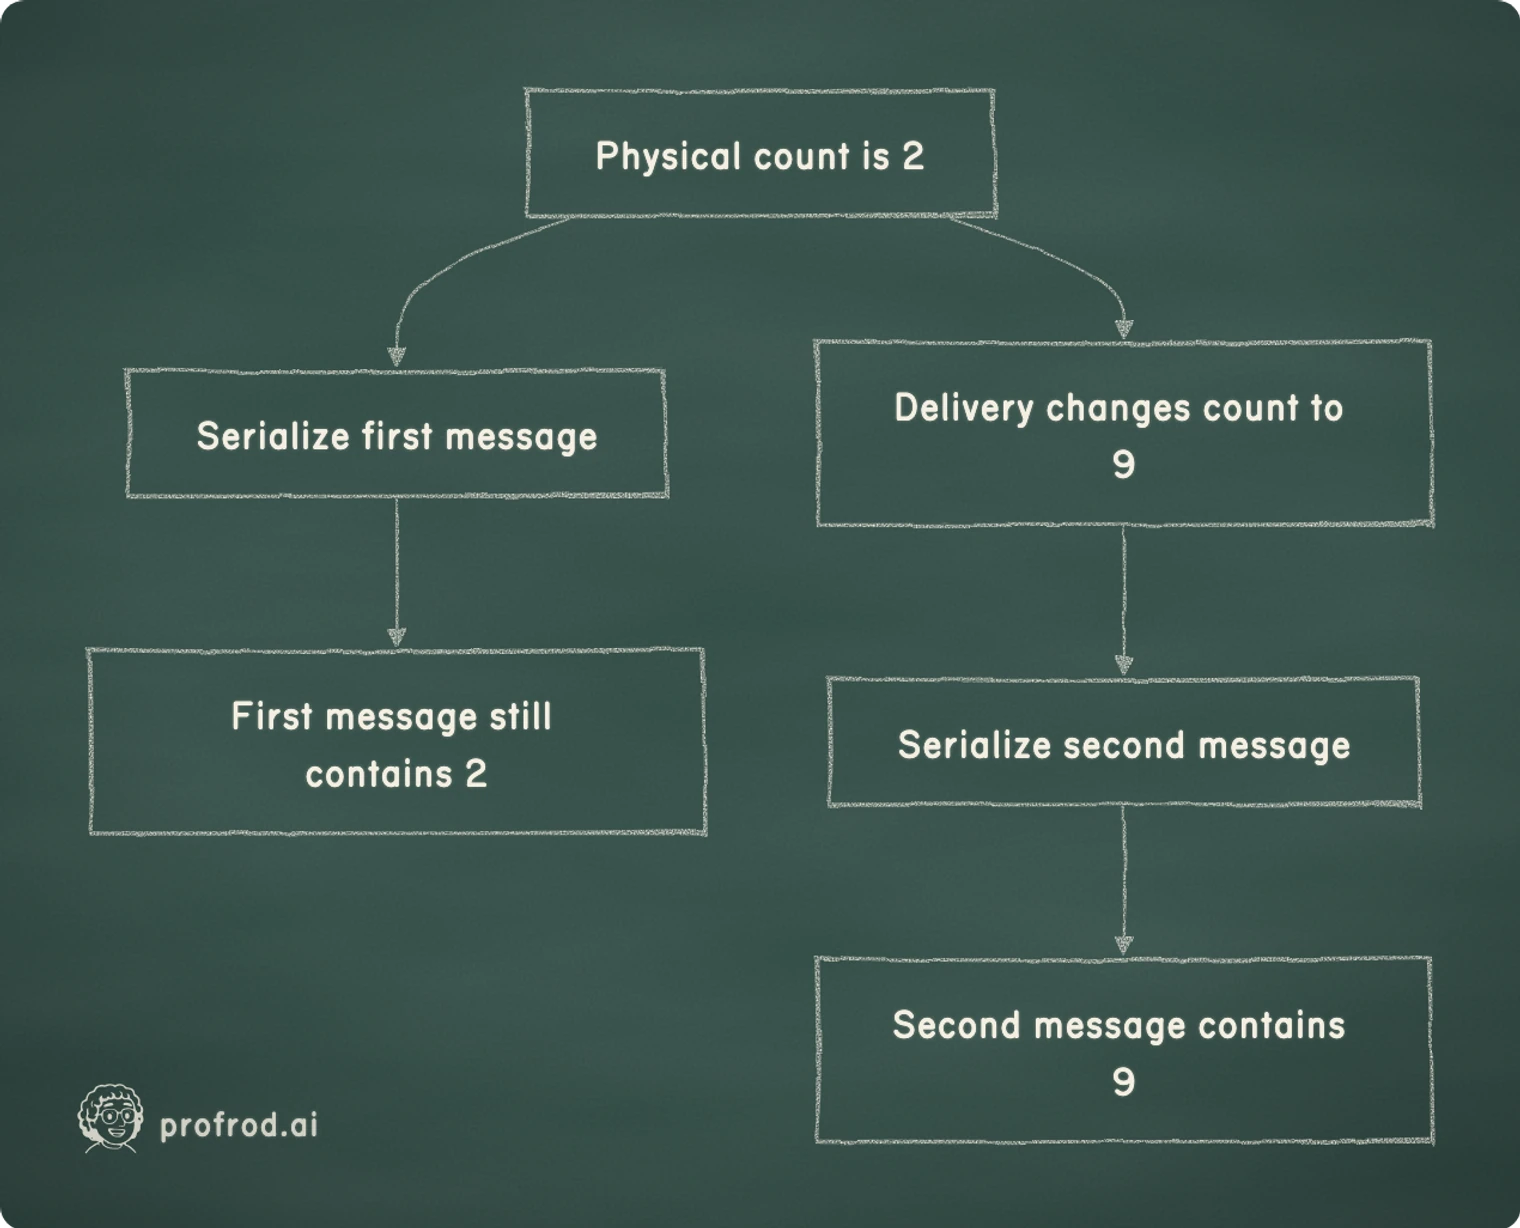
flowchart LR
    A[Physical count is 2] --> B[Serialize first message]
    B --> C[First message still contains 2]
    A --> D[Delivery changes count to 9]
    D --> E[Serialize second message]
    E --> F[Second message contains 9]
The earlier message still contains two. Serialization created a snapshot. The model cannot discover the later delivery from a request that contains only the earlier snapshot, however capable the model may be. You could rebuild the request just before sending it, but that still would not give a running multi-step task a way to request fresh stock later.
This failure motivates the next chapter. A stock tool will let the program read authoritative data at a particular point in the loop, return that observation, and record what the model saw. It will not make the world stop changing. We will still have to decide which facts need rechecking at an action boundary.
For a second variation, change only the display name while keeping the SKU. Inspect both serialized messages. The product's identity should remain stable. If you instead use a display name as the only identifier, a rename can accidentally look like a different product to code that has no other way to correlate it with existing records.
Detect a changed snapshot before reviewing the draft
Hash the same copied shop value used to build the request, then compare it with current content when the response returns. The local stamp belongs to the program, not to a claim generated by the model. The review remains explicitly unverified even when the stamp matches.
import hashlib


def snapshot_id(shop):
    return hashlib.sha256(json.dumps(shop, sort_keys=True).encode()).hexdigest()


def build(shop):
    snapshot = copy.deepcopy(shop)
    return {"snapshot": snapshot_id(snapshot), "body": payload(snapshot)}


def review_brief(built, document, current_shop):
    if built["snapshot"] != snapshot_id(current_shop):
        raise ValueError("shop changed since the request was built; request a fresh brief")
    text = read_brief(document)
    return {
        "status": "NEEDS_FACTUAL_REVIEW",
        "draft": text,
        "flags": check_brief(text, current_shop),
        "stock_facts": stock_facts(current_shop),
    }


current_shop = copy.deepcopy(SHOP)
built = build(current_shop)
print(review_brief(built, OFFLINE_RESPONSE, current_shop)["status"])
current_shop["products"][0]["on_hand"] = 9
try:
    review_brief(built, OFFLINE_RESPONSE, current_shop)
except ValueError as error:
print(str(error))NEEDS_FACTUAL_REVIEW
shop changed since the request was built; request a fresh briefThis check detects different content at two instants. It does not authenticate a provider response, prove that its prose is true, prevent a change after review, or detect an intervening change followed by a return to the original content. In later chapters the action boundary rechecks authoritative records and their versions. For now, we have prevented a known changed snapshot from quietly becoming today's brief.
Exercises on the fundamentals
Exercise 1: prove what top-p removes
Take the bigram distribution after "." at . How many tokens does top-p with keep, and how much probability did the discarded tokens hold? Now prove, in two lines, that top-p never removes the most likely token. Then find a distribution where top-p with keeps exactly one token, and describe the temperature at which that happens for the bigram distribution after ".".
Exercise 2: entropy at the extremes
Show from the formula that exactly when one , and that with equality only for the uniform distribution. (Hint: is concave; use Jensen's inequality on .) Check both limits numerically with softmax at and .
Exercise 3: the cost of a new language
Encode the same sentence in English and in Spanish ("Pide seis tarrinas de vainilla antes del fin de semana.") with the tokenizer trained on Lucy's English notes. Compare tokens per character. Then compute what the difference would cost across a million requests at the prices used above. Explain why multilingual models train their tokenizers on multilingual text.
Exercise 4: where the model is sure and wrong
Using --live, request top_logprobs for Lucy's question and find the token in the answer where the model's top alternative disagreed most with what it chose. Is that the token where the answer goes wrong? Report what you find either way. A high probability on a wrong claim, or a low one on a right claim, are both results.
Exercise 5: repeatability
Run the live greedy request ten times in a row, then ten times across two restarts of the Ollama server. Count distinct answers in each case. What is the smallest change to the request (a trailing space, a different max_tokens) that changes the greedy answer? What does your answer imply for anyone writing a test that compares a live response to fixed text?
Expected observations
Run the experiment offline. Your receipt should reproduce the chapter's tables exactly: training is deterministic, and sampling uses a fixed seed.
- Tokenization: Characters per token rise from 1.00 at no merges to 3.20 when no pair repeats. Held-out bits per character are lowest at 100 merges.
- Smoothing: Held-out bits per character are lowest near , while training bits keep falling as shrinks.
- Temperature: The derived and finite-difference derivatives agree to four decimals in every row.
- Sampling: is within about two standard deviations of its degrees of freedom (). The single largest per-token deviation may well exceed three standard errors; that is expected, and the reason for the chi-square test.
With --live, your model, version and hardware will differ from ours, so the numbers will too. What should hold is the shape of the result:
- one distinct answer across greedy samples within a run;
- many distinct answers at and above;
- an answer probability far below ;
- a per-token entropy of a bit or two.
Check the answer's claims against the stock table yourself; do not assume they are right because the numbers above are normal.
Run the checkpoint offline. Its output must match the fixture shown in Part B exactly, and it contains no supplier endpoint or purchasing function.
Learner verification
Verify the fundamentals independently of the code under test:
- Softmax by hand: Pick three logits, compute softmax with a calculator, and compare. Then add 100 to each logit and confirm that nothing changes.
- Entropy by hand: Compute the entropy of a fair coin (1 bit) and of a fair four-sided die (2 bits) with
entropy_bits. These are the only two numbers in the chapter you should know without computing. - The sampler against the test that would catch a bug: Introduce an off-by-one in
sample(returni + 1), rerun the experiment, and confirm that the chi-square explodes. A check that cannot fail on a broken sampler proves nothing about a good one. - The tokenizer round trip: Confirm that
decode(encode(text, merges))returns the original text for any text: every byte of every language, and emoji. Byte-level BPE guarantees this; say why.
Then verify the brief, as Part B describes: each stock claim against the table, and no claim of an action the program cannot take.
Vocabulary and check your understanding
- Token: a unit of text the model reads and writes. Tokenizer: the function from text to tokens. Byte-pair encoding (BPE): a tokenizer built by repeatedly merging the most frequent adjacent pair.
- Logit: a model's unnormalized score for one candidate next token.
- Softmax: the map from logits to probabilities, .
- Temperature: a divisor of the logits that sharpens () or flattens () the distribution. Greedy decoding: always choosing the most likely token, the limit.
- Top-p (nucleus) sampling: sampling only from the most likely tokens that together reach probability .
- Entropy: the average surprise of one draw, bits.
- Cross-entropy: the average number of bits a model needs per token of a given text. It is the loss language models are trained to minimize. Perplexity: .
- Held-out data: text the model did not train on, the only honest place to measure it. Overfitting: improving on training data while getting worse on held-out data.
- Snapshot: the facts serialized into one request. Response fixture: an authored example response used to test code. Completion envelope: the response's protocol fields around the generated text.
Check your understanding
Answer without looking back:
- Why is it a mistake to compare two models by per-token perplexity when they use different tokenizers? What do you compare instead?
- Derive softmax from the requirement that logit differences are log-odds.
- A colleague sets temperature to 0 and writes a test that compares the model's answer to a stored string. What will happen, and why?
- A model assigns probability to its own answer. Is it unsure of its facts?
- Why does adding to every count help on held-out text, and what happens if is too large?
- The offline checkpoint passes, but the local model server is stopped. What has been tested, and what has not?
- A completed response says the model placed an order. What evidence would you need before repeating that to Lucy?
Summary
A model call is four steps you have now built: text to tokens, tokens to logits, logits to a distribution, a distribution to a sampled token, repeated. You derived softmax from what probabilities over tokens must satisfy. You proved that temperature raises entropy at the rate and checked it numerically. You tested a sampler the way statisticians do. You showed that next-token training is cross-entropy minimization, and found overfitting in held-out bits per character, the only fair unit across tokenizers.
On a real model you read the same quantities from log-probabilities. You found an answer that was fluent, low-probability as every long answer is, not repeatable at temperature 0, and wrong. That is why Part B treats every response as a sample to check against facts, and why the program Lucy runs keeps its own stock facts separate from the model's prose.
In Chapter 2, the model stops receiving facts in its prompt and starts asking for them through tools. There you will see that asking a model for structured output is itself a constraint on the distribution you built here.
Keep building with Prof Rod
Found this material through a colleague, classroom or shared download? Get the complete book at profrod.ai/book and join the Prof Rod learner community. Bring one result, one question or one failure you learned from. Share this resource with another learner and keep its source links with it so they can find the full course and future updates.


