
What an accepted sweep proves
You give a coding agent access to your research repo and ask it to set up a LoRA sweep. It writes configs/lora_sweep.yaml and proposes twelve runs at 8 GPU-hours each: 96 GPU-hours against the 120 your team has left this week. It also proposes deleting three old checkpoint directories to free disk. A validator checks the proposal: the config parses, every path is inside the project's scratch directory, the GPU-hours fit, and the proposal names the commit it was written against. Every check passes, and the validator returns accepted_draft.
Has the sweep started?
No. You have an accepted proposal. There is no scheduler job ID, no reservation against the allocation, and the checkpoints are still on disk. Getting from here to a running sweep needs a separate component that checks the authority to act and then acts. This article builds that boundary, shows the arithmetic for what it buys, and says how you would measure it.
Chapter 11 of the book derives when an agent may act without asking, from a measured calibration curve, and builds the approval records in full. This article adds three things the chapter does not cover: the expected-harm arithmetic for stacked checks, sorting actions by how reversible they are, and how to split validation from execution in a coding agent's tool list.
Two functions with different jobs
Give validation and execution separate interfaces. A validator takes a proposal and returns a judgment: typed, internally consistent, inside budget, consistent with known facts. You can call it a hundred times and nothing in the world changes. Its answer stays the same while the proposal and the reference data stay the same.
An executor takes an approved proposal and changes the world: it submits jobs, deletes directories, posts results to a shared tracker, or emails co-authors. Calling it twice may submit the sweep twice. The two functions differ in what can go wrong, so they need different shapes.
Four states between a proposal and an effect
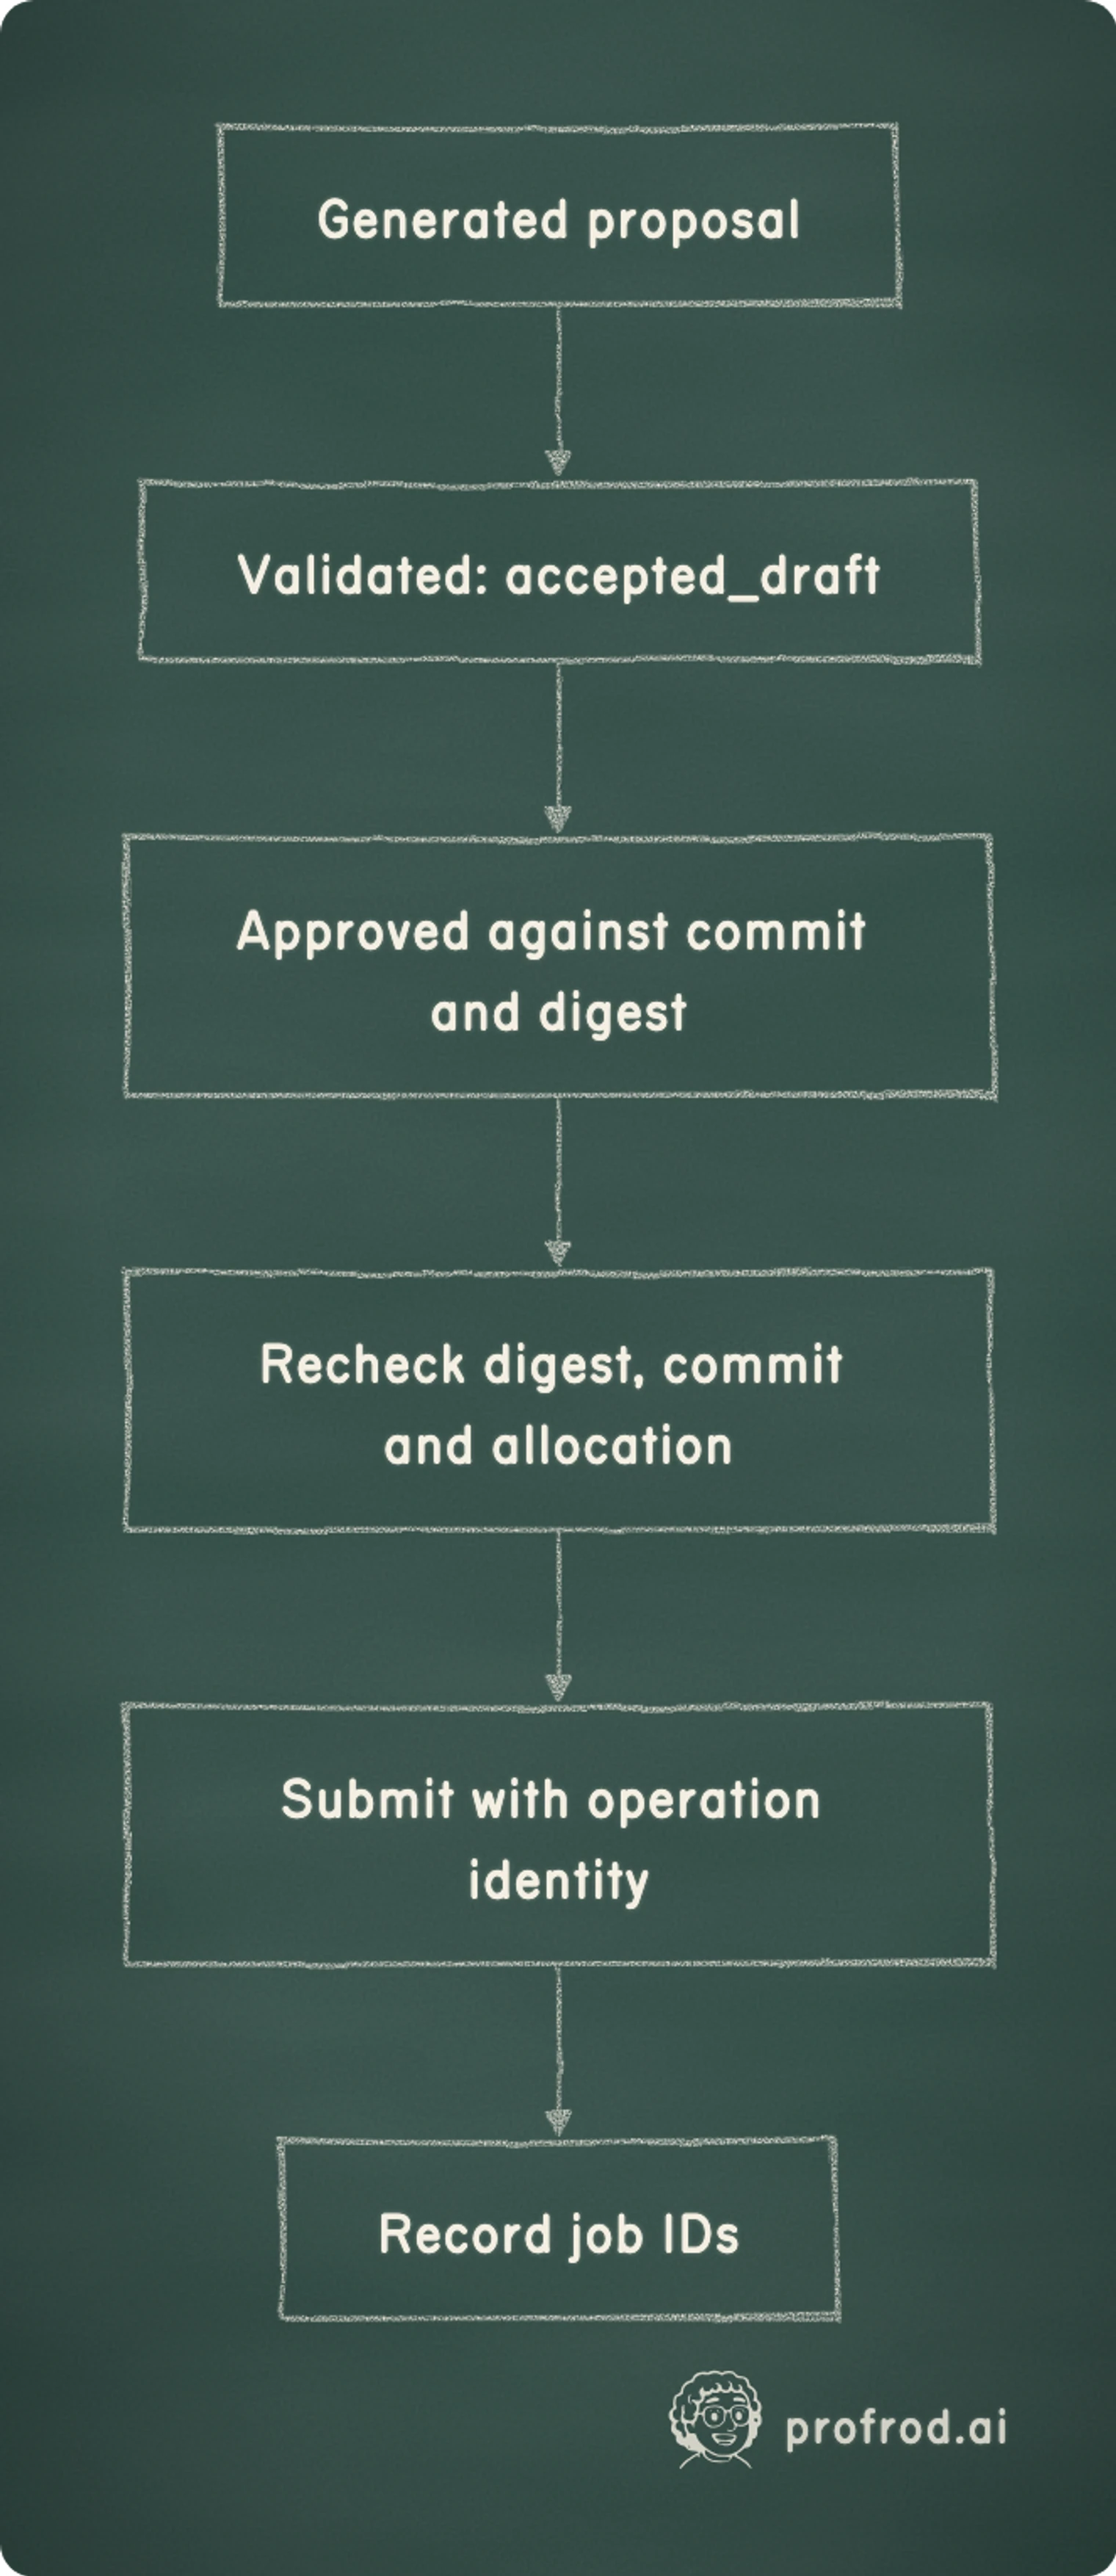
"The agent's output" passes through at least four states before it has any effect, and most confusion comes from treating them as one.
| State | What it means | What confirms it |
|---|---|---|
| Generated | The model produced a config and a plan | The files exist, nothing more |
| Validated | The proposal passed schema and policy checks | accepted_draft, with the computed GPU-hours |
| Approved | A person or a policy signed off on this exact proposal | An approval record naming a proposal digest and a commit |
| Executed | The scheduler accepted the jobs; the directories are gone | Job IDs from the scheduler; a deletion log |
Scroll horizontally to view columns.
What stacked checks buy, in numbers
Suppose the agent proposes n actions over a week, and each is wrong with probability e. With no boundary, the expected number of wrong actions that reach the world is n·e. Put a validator in front that catches a fraction c of the wrong proposals, then a reviewer who catches a fraction h of what gets past it. The expected number of wrong effects becomes
E[wrong effects] = n · e · (1 − c) · (1 − h)With illustrative values n = 200, e = 0.05, c = 0.6 and h = 0.5: ten proposals are wrong, four pass the validator, and two reach the cluster. These are not measurements of any agent. They show the structure: each layer multiplies, and a layer you have not measured contributes an unknown factor.
So measure c. Plant 40 known-bad proposals (a path outside scratch, a sweep over budget, a stale commit) and count what the validator catches. If it catches 24, the estimate is 0.6, and the binomial interval is
0.6 ± 1.96 · √(0.6 × 0.4 / 40) = 0.6 ± 1.96 × 0.077 = 0.6 ± 0.15Forty planted cases cannot tell a validator that catches 45% from one that catches 75%. Chapter 16 covers error bars and paired comparisons if you want to compare two validators properly.
Execution has its own arithmetic. If each of the twelve submissions succeeds independently with probability 0.99, all twelve succeed with probability 0.99¹² ≈ 0.886. About one sweep in nine ends partly submitted. An executor that records one success flag for the whole sweep cannot say which runs exist, so record a receipt per action.
Sort actions by how reversible they are
A boundary costs a person's attention, so spend it where mistakes cannot be undone.
| Class | Example in a research repo | Boundary it needs |
|---|---|---|
| Read-only | Read logs, query the results table | Validation only |
| Reversible at a cost | Submit a job (you can cancel it, but GPU-hours already burned are gone) | Validation, a budget check and a recorded operation identity |
| Irreversible | Delete checkpoints, publish results, email a collaborator | Explicit approval bound to exact data, then a recheck |
Scroll horizontally to view columns.
The three checkpoint deletions sit in the last row. The twelve submissions sit in the middle row, where a policy can approve automatically if the amount fits the budget. Chapter 11 builds exactly that split between automatic and operator approval.
Bind the approval to exact data
Suppose you approve the sweep at 10 a.m. Forty minutes later, a teammate merges a change to the training loop, and the proposal you read no longer describes the code that will run. An approval that does not name what it approved cannot tell the difference. The companion article on rechecking the snapshot at approval time derives how often this happens as a function of approval delay.
Bind the approval to a digest of the canonical proposal and to the commit, then check both again at the moment of execution, together with the allocation that remains. The example below uses only the Python standard library and runs on Colab's Python 3.12.
import hashlib
import json
from dataclasses import dataclass


def digest(proposal: dict) -> str:
    canonical = json.dumps(proposal, sort_keys=True, separators=(",", ":"))
    return hashlib.sha256(canonical.encode()).hexdigest()[:12]


@dataclass(frozen=True)
class Approval:
    proposal_digest: str
    repo_commit: str


def may_submit(approval: Approval, proposal: dict, repo_commit: str, gpu_hours_left: int) -> str:
    if digest(proposal) != approval.proposal_digest:
        return "refuse: proposal changed after approval"
    if repo_commit != approval.repo_commit:
        return "refuse: code changed after approval"
    if proposal["gpu_hours"] > gpu_hours_left:
        return "refuse: allocation no longer covers the sweep"
    return "eligible"


sweep = {"config": "configs/lora_sweep.yaml", "runs": 12, "gpu_hours": 96}
approval = Approval(digest(sweep), repo_commit="3f9c2e1")

print(digest(sweep))
print(may_submit(approval, sweep, "3f9c2e1", 120))
print(may_submit(approval, sweep, "8d04a7b", 120))
print(may_submit(approval, {**sweep, "runs": 16, "gpu_hours": 128}, "3f9c2e1", 200))
print(may_submit(approval, sweep, "3f9c2e1", 80))
Running it prints:
eb0b74f57db1
eligible
refuse: code changed after approval
refuse: proposal changed after approval
refuse: allocation no longer covers the sweep
The last line matters most in a shared lab: nothing about the sweep changed, but another team's jobs consumed the allocation in the meantime. The check refuses anyway, because the approval never covered spending hours that no longer exist.
This function checks eligibility and nothing else. It does not reserve the GPU-hours, so two executors could both see 120 hours left and both submit. Chapter 11 reserves the amount in the same transaction that records the approval. It also does not make submission safe to retry: if the scheduler call times out, you do not know whether the jobs exist. Chapter 12 gives each intended effect a stable operation key and reconciles before any resend. LangGraph's documentation makes the same point for agent workflows in general: resuming an interrupted node can rerun work done before the interrupt, so side effects must be idempotent (LangGraph: interrupts).
The eligibility function has nothing to undo because it sends nothing. Once the scheduler accepts a job, canceling it stops future spending, not past spending, and a deleted checkpoint does not come back. Keep the original job IDs and record any cancellation as a separate event.
Why a repair loop is not execution
Many harnesses wrap generation in a repair loop: if the validator rejects a proposal for a fixable reason, such as a malformed YAML key, the model tries again, up to a fixed number of attempts. That loop decides how many times to regenerate a proposal. It says nothing about whether an accepted proposal may act. Some rejections should stop the loop at once. A stale commit or an exhausted allocation is a missing authority, and regenerating the YAML cannot supply it.
Anthropic's guidance on writing tools for agents covers how tool definitions, responses and evaluations shape what an agent does. Apply it here: if validate_sweep and submit_sweep share a name pattern, a return type and a calling convention, the agent's tool list invites confusion. Keep them visibly distinct. The validation tool returns judgments and imports no scheduler client. The execution tool requires an approval record as an argument, and it is the only module in the repo allowed to import the scheduler client.
Check the proposal against the schema and against trusted state: paths, allocation, commit. Return accepted_draft or a named rejection. Make no external call.
A person or a policy approves a specific proposal digest and commit. An approval that names neither is not usable.
At execution time, recompute the digest, read the current commit and the remaining allocation, and proceed only on an exact match.
Record a job ID per run. A timeout leaves the outcome unknown; reconcile it by the operation identity before you submit anything again.
What would prove this design wrong
A boundary should come with tests that would show it failing. Run these three.
- Pass a stale approval to the eligibility check and confirm it refuses. Then, in an integration test, confirm that a refusal means the scheduler client is never called.
- Approve one proposal, then execute a different one with the same run count. The digest check should refuse.
- Make the scheduler call time out after the scheduler has accepted the jobs, then let the harness retry. If the retry submits twelve more runs, the boundary you built in application code has been undone by the transport layer.
The third test is the one teams skip, and it is the ordinary way a demo-safe design fails under real retries.
Check the decision
Why this matters in a lab
Research teams increasingly let agents touch shared infrastructure: clusters, eval harnesses, results tables, storage. The failures that cost a team a week are rarely a wrong answer in chat. They are a sweep launched twice, a checkpoint deleted, or results posted from the wrong commit.
An interviewer for an applied-AI or research-engineering role might ask: "Your agent can launch jobs on our cluster. What stops it launching an unapproved sweep, or the same sweep twice?" A strong answer names the four states, the digest-and-commit binding, the recheck at execution, the per-action receipt, and how you measured the validator's catch rate with an error bar. A work sample might hand you a tool list where one function both validates and submits, and ask you to split it.
To practice, build the chapter's spending permissions checkpoint in the course repo (profrod_sovereign_agent_ch11_spending_permissions_checkpoint.py), then re-theme its fixture as a job queue with a GPU-hour allocation.
Measure when an agent may act without asking, bind authority to an exact proposal, reserve spending, and recheck it at the send boundary.


