
You ask a coding agent to stop your evaluation runner from recording an item twice. The runner scores 2,000 items against a model API, and a timed-out call is retried. The agent adds a set of finished item IDs, runs the tests and reports success. The code looks reasonable. Then the cluster preempts the job, the runner restarts, the set is gone, and every item finished before the restart is scored again.
The missing piece was not code. It was a decision about what "the same item" means, how long that identity must survive, and what a retry is allowed to do. Someone had to make that decision before anyone could judge the implementation, and it was not the agent's to make.
This is the question at the center of any workflow where coding agents build and automated checks decide: which decisions stay with a person. The companion piece on test authority takes one of them, who may change the tests, and turns it into a measurement. This piece covers the rest.
What the automated loop does, and what sits above it
In this series, a dark software factory is a workflow in which coding agents implement changes and automated checks decide whether a candidate proceeds. Its useful output is tested software together with enough evidence to understand the release decision. The five-part workshop builds one around a small Python service you can run on a laptop. The service has the same shape as the eval runner above: an operation key, a payload, retries, and an external record of what actually happened.
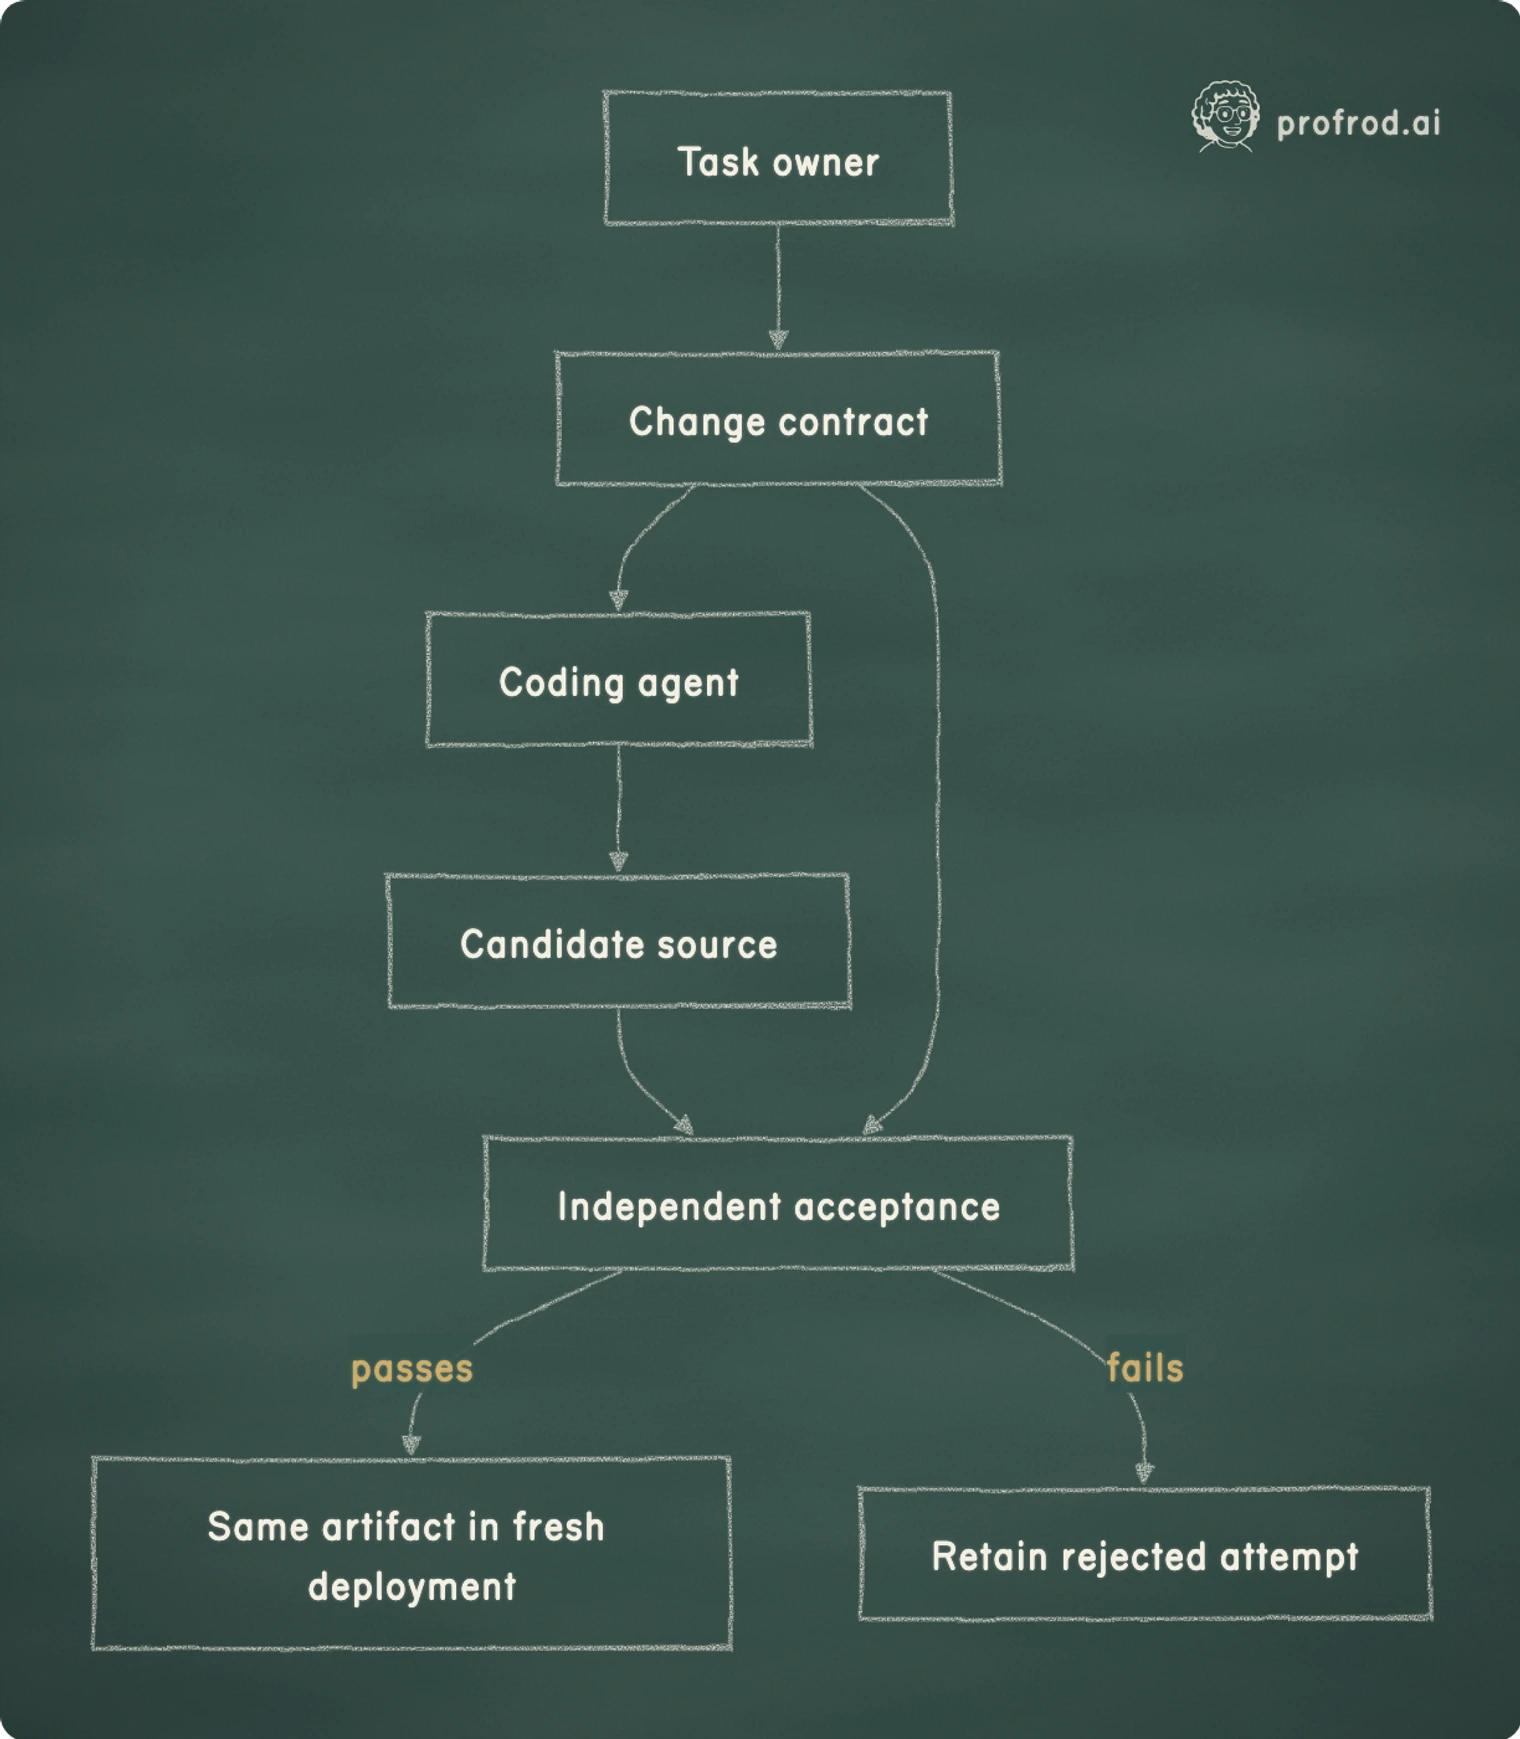
flowchart TD
    Owner[Task owner] --> Contract[Change contract]
    Contract --> Builder[Coding agent]
    Builder --> Candidate[Candidate source]
    Candidate --> Check[Independent acceptance]
    Contract --> Check
    Check -->|passes| Release[Same artifact in fresh deployment]
    Check -->|fails| Reject[Retain rejected attempt]
The diagram leaves one decision above the loop: who can change the contract? Give that power to the builder without qualification and you have given it a second way to pass. It can improve the implementation or redefine success.
Decision one: what counts as the same request
For the eval runner, the run ID and the item ID identify one scoring. The model's output for that item is its payload. From that, the requirements follow:
- Repeating the same run, item and output returns the recorded score without writing a second row.
- The same run and item with a different output is a conflict, not a silent overwrite.
- Two runs, say a baseline model and a candidate, score the same item independently.
- Two workers that pick up the same item concurrently must not both record it.
- Recorded scores survive a restart.
Each is a separate requirement, and each defeats a different shortcut.
| Tempting shortcut | Case that exposes it |
|---|---|
| Deduplicate by item ID alone | Score the baseline and the candidate in the same table; the second run's rows disappear. |
| Remember finished items only in memory | Preempt the job and restart it. |
| Retry any failed item | Compare with a run that retries only transport errors. |
| Test sequential retries only | Let two workers claim the same item at once. |
Scroll horizontally to view columns.
An agent can help you draft this table. The person who understands how the results will be used has to judge what it means.
Why a few duplicate rows matter
Suppose the true run has 1,400 passes out of 2,000 items, 70.0%. After the restart, 20 items are scored twice, and they are the long-output items that timed out and failed. The table now reports 1,400 / 2,020 = 69.3%.
The 95% half-width at n = 2,000 is 1.96 × √(0.7 × 0.3 / 2,000) = 1.96 × 0.0102 = 0.020, or 2.0 points. A 0.7-point bias is a third of that. It is small, but it is not noise: it does not average away over repeated runs, and it differs between two models whose outputs time out at different rates, which is exactly the comparison you ran the evaluation to make. Chapter 16 derives the interval and the paired comparison.
Decision two: what a retry is allowed to do
"Retry on failure" sounds like plumbing. It is a choice of what you are estimating. If the runner retries only when the API call fails, a sample is still one sample. If it retries whenever the answer fails, and samples at a nonzero temperature, each item gets up to two tries. With a per-sample pass rate of 0.7, the chance an item passes within two independent tries is
1 − (1 − 0.7)² = 1 − 0.09 = 0.91.
The table would say 91% for a model whose pass@1 is 70%. No test of the runner's plumbing catches this, because the plumbing works. Deciding that retries resample only on transport errors, and that the report names its estimand, is a methodology decision. It belongs to whoever owns the evaluation.
Decision three: what counts as evidence the write happened
Consider a result store that commits a row and then loses the reply. The runner does not know whether the score was recorded. Reporting "recorded" overstates the evidence; reporting "failed" and writing again risks a duplicate.
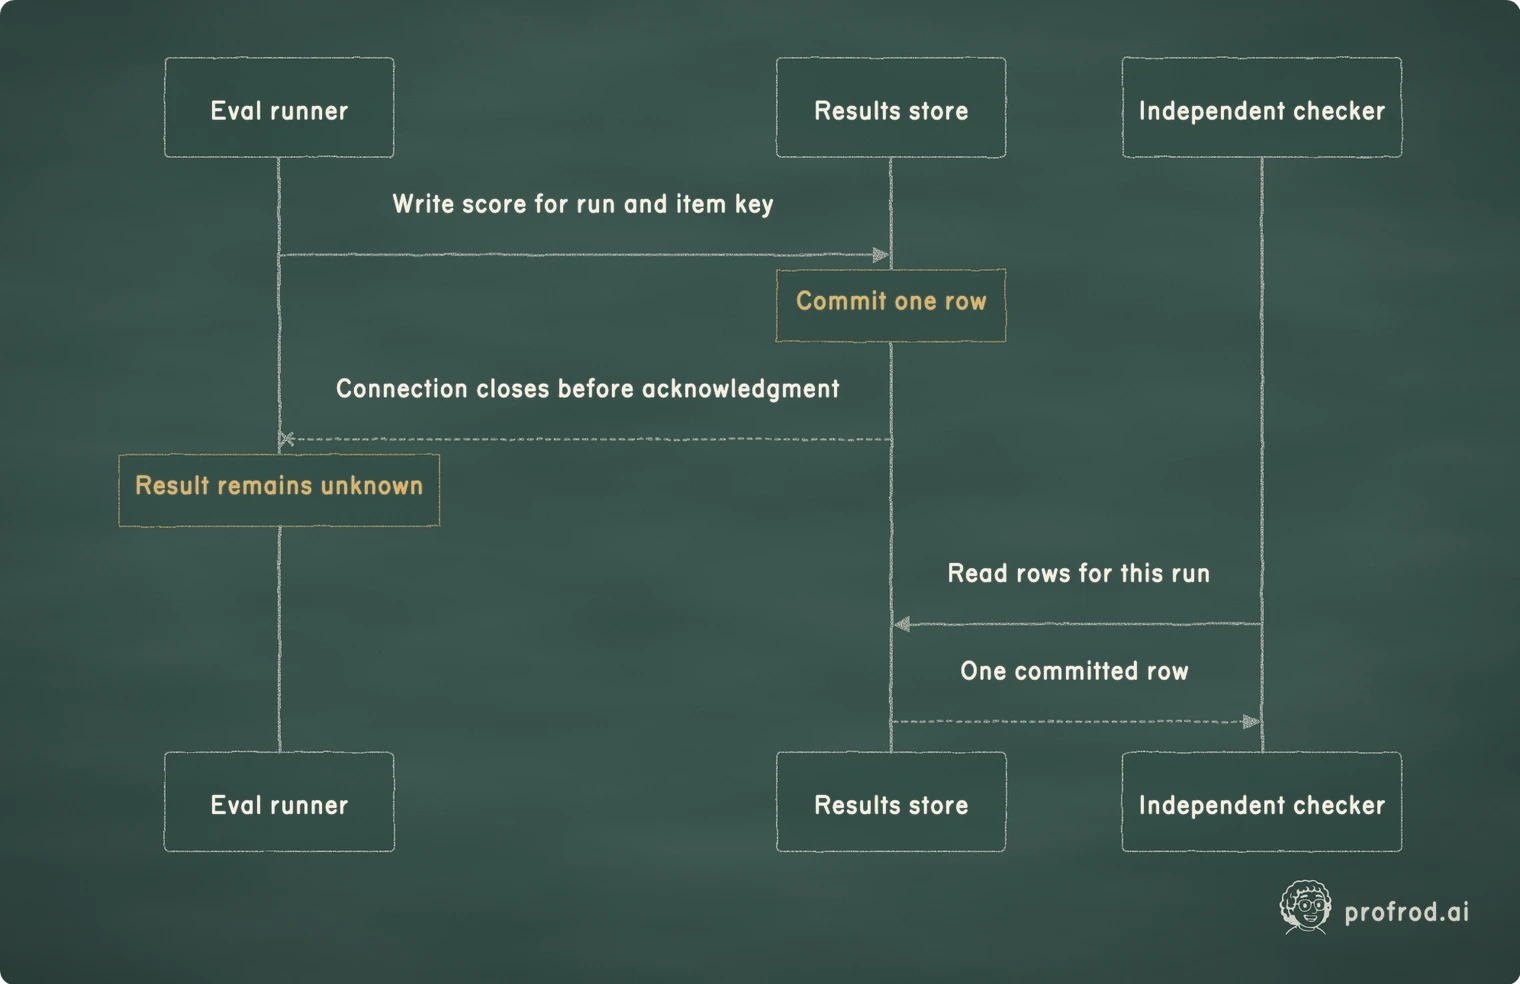
sequenceDiagram
    participant Runner as Eval runner
    participant Store as Results store
    participant Check as Independent checker
    Runner->>Store: Write score for run and item key
    Note over Store: Commit one row
    Store--xRunner: Connection closes before acknowledgment
    Note over Runner: Result remains unknown
    Check->>Store: Read rows for this run
    Store-->>Check: One committed row
The workshop keeps such a result unknown and later reconciles it by asking the receiving system whether the operation exists. The checker reads a separate record of effects. That separation matters: a candidate could return a well-formed success without writing anything, or write twice while returning the same receipt twice. Checking the response and checking the effect answer different questions.
The workshop defines one HTTP failure as occurring before any write. That is a property of its simulator. Do not carry the assumption over to a real results store or API without establishing its documented and observed behavior.
The evaluation environment belongs in the design from the start. It determines what the factory can know about a candidate, including which failures stay invisible.
Decision four: which artifact the result applies to
A test result applies to one candidate. If the agent makes one more cleanup edit afterward, the earlier result no longer identifies the file.
The workshop's controller freezes the source and records its hash. After acceptance it runs those same bytes in fresh sandboxed processes and repeats the checks. The hash establishes identity; the observations establish selected behavior. Neither substitutes for the other.
The workshop is a local teaching release. It does not establish a production rollout, a long-running reliability result or coordination between replicas, and it says so, because a small example misleads when its claims grow faster than its evidence.
Deleting the check changes which failures the factory can accept. The owner of the evaluation must decide whether surviving a preemption is still required. The builder's difficulty with a requirement is not evidence that the requirement went away.
Build the small loop before expanding its authority
Run the baseline against its own contract, then show that it fails the new duplicate-request contract. Keep both reports so the required difference is visible.
Ask for the specified change. Keep the model's response, the candidate and the failed attempts. Record the time you spend reviewing or repairing them.
Run the unchanged acceptance contract against the frozen candidate. Only an accepted artifact proceeds to a fresh environment, where the checks run again.
Before opening the answer, consider this variation: the runner returns the correct score for an item, but the results table holds two identical rows for it. Is the release acceptable?
A correct score does not excuse a duplicate row
No. The contract requires exactly one recorded row per run and item. Matching the score establishes which result the response describes; counting matching rows establishes whether the implementation duplicated it. Both observations are required, and the duplicate is exactly what biased the pass rate in the arithmetic above.
Then supply a deliberately faulty implementation. If the checker lets it through, repair the checker before using it to judge more ambitious work. The test-authority piece shows the workshop's negative control and a protocol for measuring how often agents weaken tests.
Count the whole cost too: specification, review, failed runs and recovery, not only generation time. The cost of unverified output is often paid after the code already looked finished.
Why this matters in a lab
Evaluation infrastructure is lab work in its own right. Anthropic's post-training evaluations posting includes "Run and monitor the eval fleet live to understand how each Claude model is developing as it trains", and OpenAI's frontier-evals posting includes "Design scalable systems and processes to support continuous evaluation." Coding agents will write more of that infrastructure. The engineer who can say what the same request is, what a retry may do, and what evidence a release needs is the one whose numbers others can trust. In an interview, expect the question in its plain form: "Your eval job restarted halfway. How do you know no item was counted twice?"
Do I need to finish the book first?
No. The book builds the agent itself: its tools, memory, recovery and evaluation. This workshop builds the process around a coding agent: defining a change, testing its output and controlling release. Start with the supplied Python service, and use the book when you want to see the same mechanisms, such as idempotent retries in Chapter 12, built from scratch.
Run the baseline, specify one change and inspect the acceptance evidence in the five-part workshop.


