
The judge said false. The harness counted a pass.
You run a model-graded evaluation. A judge model reads each answer and returns a verdict, and your harness adds up the passes. One verdict comes back as {"case_id": "q-0417", "passed": "false"}: the word false, in quotes. A quick parser does bool(verdict["passed"]), and bool("false") is True, because any non-empty string is truthy. The case is counted as a pass. Nothing crashes. Your pass rate is now wrong by one case, and you have no record that it happened.
Switch the verdict to a 0–4 rubric score and the same kind of bug moves around. The judge returns "score": true. A lax integer field converts it to 1. The case fails a pass threshold of 3, silently, when the judge probably meant something else entirely and should have been asked again.
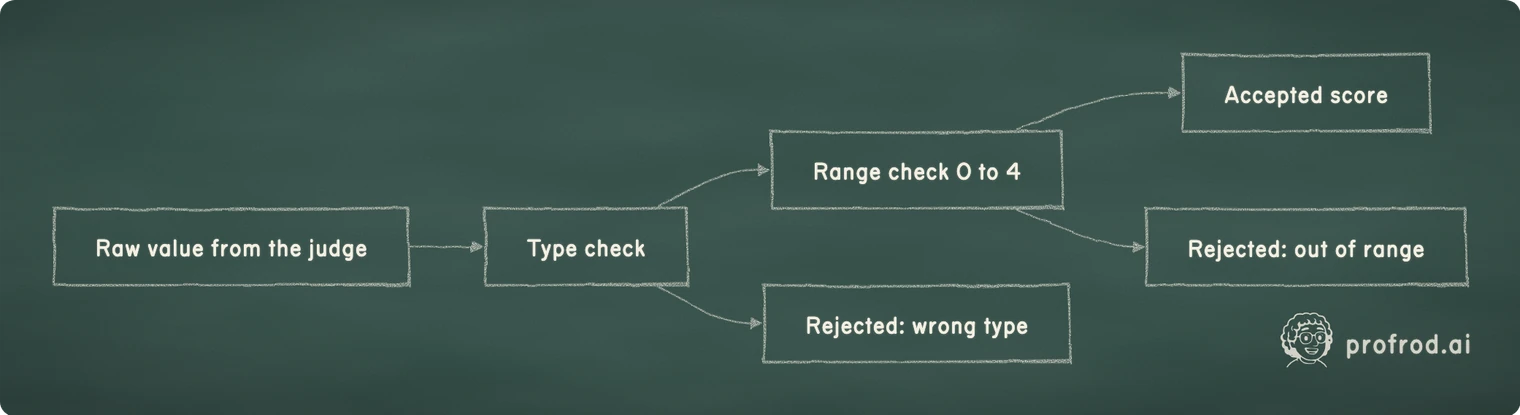
The bug is not that the judge was sloppy. Models will sometimes be sloppy. The bug is that nobody decided, in code, which representations of a score the harness is willing to accept. Prompting the judge to "return an integer" asks for good behavior; a runtime type boundary checks for it.
Why isinstance is not enough
Python has a trap that makes hand-rolled checks unreliable: bool is a subclass of int. True behaves as 1 in arithmetic, isinstance(True, int) is True, and sum([True, True, False]) is 2. That is convenient for counting. It is wrong for a field whose contract is "a rubric score from 0 to 4". A score of True is not a score.
So write the contract before the code. For the judge's score field: accept a Python or JSON integer from 0 through 4; reject Booleans, floats and strings, and send the case back to the judge or to a person. Now a reviewer can check the implementation against an explicit list rather than guess what "a number" meant.
What strict mode changes, measured
Pydantic's strict-mode documentation describes reduced coercion, with behavior that depends on the field type and on whether input arrives as a Python object or as JSON text. Rather than restate the documentation, here is what one environment did. On 2026-09-30, on Python 3.12.13 with Pydantic 2.13.5, the same seven values went through a strict model and a default (lax) model, each once as a Python dict and once as JSON text:
from pydantic import BaseModel, ConfigDict, Field


class Verdict(BaseModel):
    model_config = ConfigDict(strict=True, extra="forbid")
    case_id: str
    score: int = Field(ge=0, le=4)


class LaxVerdict(BaseModel):
    case_id: str
    score: int = Field(ge=0, le=4)
Value sent as score | Strict model | Lax model | Why it matters |
|---|---|---|---|
3 | accept 3 | accept 3 | A valid score |
True / JSON true | reject int_type | accept 1 | A Boolean becomes a failing score |
3.0 | reject int_type | accept 3 | A float passes as a score |
'3' | reject int_type | accept 3 | A string passes as a score |
-1 | reject greater_than_equal | reject greater_than_equal | Below the rubric |
5 | reject less_than_equal | reject less_than_equal | Above the rubric |
0.5 | reject int_type | reject int_from_float | Fractional, rejected by both |
Scroll horizontally to view columns.
The Python-dict path and the JSON path gave the same outcome for every row in this run. That holds for this integer field in this version. It is not a promise about dates, decimals or nested models, which have their own documented exceptions; test each field type you use.
The bold cells are the ones that change an evaluation. Lax mode is a reasonable default for a web form, where every field arrives as text and "3" really does mean 3. It is the wrong default for a grader, where a wrong type is evidence that the judge did not follow its format, and that evidence is exactly what you want to keep.
How often do models send the wrong type?
Less often than the fear suggests, and in a different way. Chapter 2 of the book recorded 120 prompt-only answers from qwen2.5:0.5b and qwen2.5:1.5b asked for {"sku", "quantity"}. Counting the quantity types in that receipt, after removing the Markdown fences that caused every parse failure:
| Model, prompt only | Integer | Float | String |
|---|---|---|---|
qwen2.5:0.5b | 56 | 4 | 0 |
qwen2.5:1.5b | 60 | 0 | 0 |
Scroll horizontally to view columns.
Zero strings in 120 answers. With no events, the Wilson upper bound at 95% is z²/(n + z²) = 3.84 / (120 + 3.84) = 0.031, so on this task the string rate is plausibly below 3.1%. The four floats were all 0.5, from the request "half a dozen pistachio": the model read "half". The type error was a meaning error in disguise, which is why rejecting it and asking again beats converting it.
That is one task, two small models and one prompt. A judge model writing rubric scores is a different distribution. If your grader depends on it, measure it: run your judge over a few hundred stored answers, count each non-integer type, and report the rate with a Wilson interval before deciding how much ceremony the boundary needs.
| Recheck item | Recorded basis | What to verify locally |
|---|---|---|
| Strict and lax integer rules | Run on 2026-09-30, Python 3.12.13, Pydantic 2.13.5 | Your installed version and field configuration |
| Python dict versus JSON input | The seven-value table above | Both entry points your harness uses |
| Rubric range | The 0–4 fixture | Your rubric, and who owns changes to it |
Scroll horizontally to view columns.
Decide the policy before writing the field
The task is not memorizing that Booleans get rejected. It is deciding what each field means and encoding that so it does not depend on which code path touches the value first.
Write one sentence a colleague can check: "score is the judge's rubric grade, an integer from 0 to 4." Do this before choosing a Pydantic type.
For a grader, a wrong type is information about the judge; keep it by rejecting. For a form field that arrives as text, converting may be correct. Pick per field, with a stated reason. A companion article turns a strict verdict parser into a function every entry point of a harness shares.
Run the seven values above against your field. A field that has only seen valid input has not been tested against the thing it exists to catch.
A rejected verdict should go back to the judge once with the field and error code, or to a person, and be counted in a separate "unparsed" column. Never drop it from the denominator.
Strict validation on an integer field says nothing about a date, a decimal or a nested list. A valid integer can also be the wrong grade: strict typing proves the judge returned a score, not that the score is right. Grader accuracy is a separate measurement, covered in Chapter 16.
Tightening the parser changes your metric
Switching a grader from lax to strict parsing is a change to the measuring instrument. Verdicts that were quietly converted now fail to parse, so the pass rate can move even though no model changed. If last week's baseline was scored with the lax parser and this week's candidate with the strict one, the comparison between them mixes a model change with a parser change.
Do this instead. Keep every raw judge output. Re-parse all stored outputs, for the baseline and the candidate, with the new parser. Report how many verdicts changed, and compare the two arms on the same cases with the same parser, as a paired comparison. To see why the count matters, take a hypothetical: if 6 of 400 stored verdicts flip from pass to unparsed, the pass rate moves by 6/400 = 1.5 points. The 95% half-width at 400 cases is at most ±4.9 points, so that one parser change uses up almost a third of your error bar. Chapter 16 derives the interval and the paired test.
The check that must hold is narrow: every value the old parser accepted as a valid integer must still be accepted, with the same value. If a plain 3 now fails, the new configuration is wrong. A string "3" failing is the intended change.
Check the decision
What would show this reasoning is wrong
This account rests on checkable claims. If a strict integer field in your installed Pydantic version accepts True, 3.0 or "3", then either the library's behavior changed or the field is not actually strict; rerun the seven-value table and read the current documentation. If your judge, measured over a few hundred outputs, never emits a non-integer score, the strict boundary is still correct but costs you little either way. And if re-parsing your stored verdicts with the strict parser changes none of them, the migration is free. Each of those is a measurement to run, not an assumption to carry.
What an interviewer would ask
"Your eval harness reports 71% on the new prompt and 68% on the old one. What could make that three-point gap an artifact?" The parser is one answer that separates people who have run evals from people who have read about them. A strong answer names the instrument: were both arms scored by the same grader version and the same parser, were unparsed verdicts counted in the denominator, and is the gap larger than the paired error bar? A work sample that stores raw judge outputs and re-scores them makes those questions answerable in minutes.
Chapter 2 introduces Pydantic one step at a time, observes conversion before choosing strictness, and measures what a schema does and does not guarantee on a real model.


