From Chat to Agent: The Loop in a Research Repo
In a chat window, you paste a function and a traceback, the model answers, and you run the fix yourself. You are the loop: you decide what to run, you read the output, you decide whether it worked.
A coding agent takes the loop over. Claude Code reads files in the folder you start it in, runs shell commands, reads their output, edits files, and repeats until it decides the task is done. That is why it can rerun an evaluation for you, and also why it can finish a session with a confident summary of work you never saw.
The loop, one step at a time
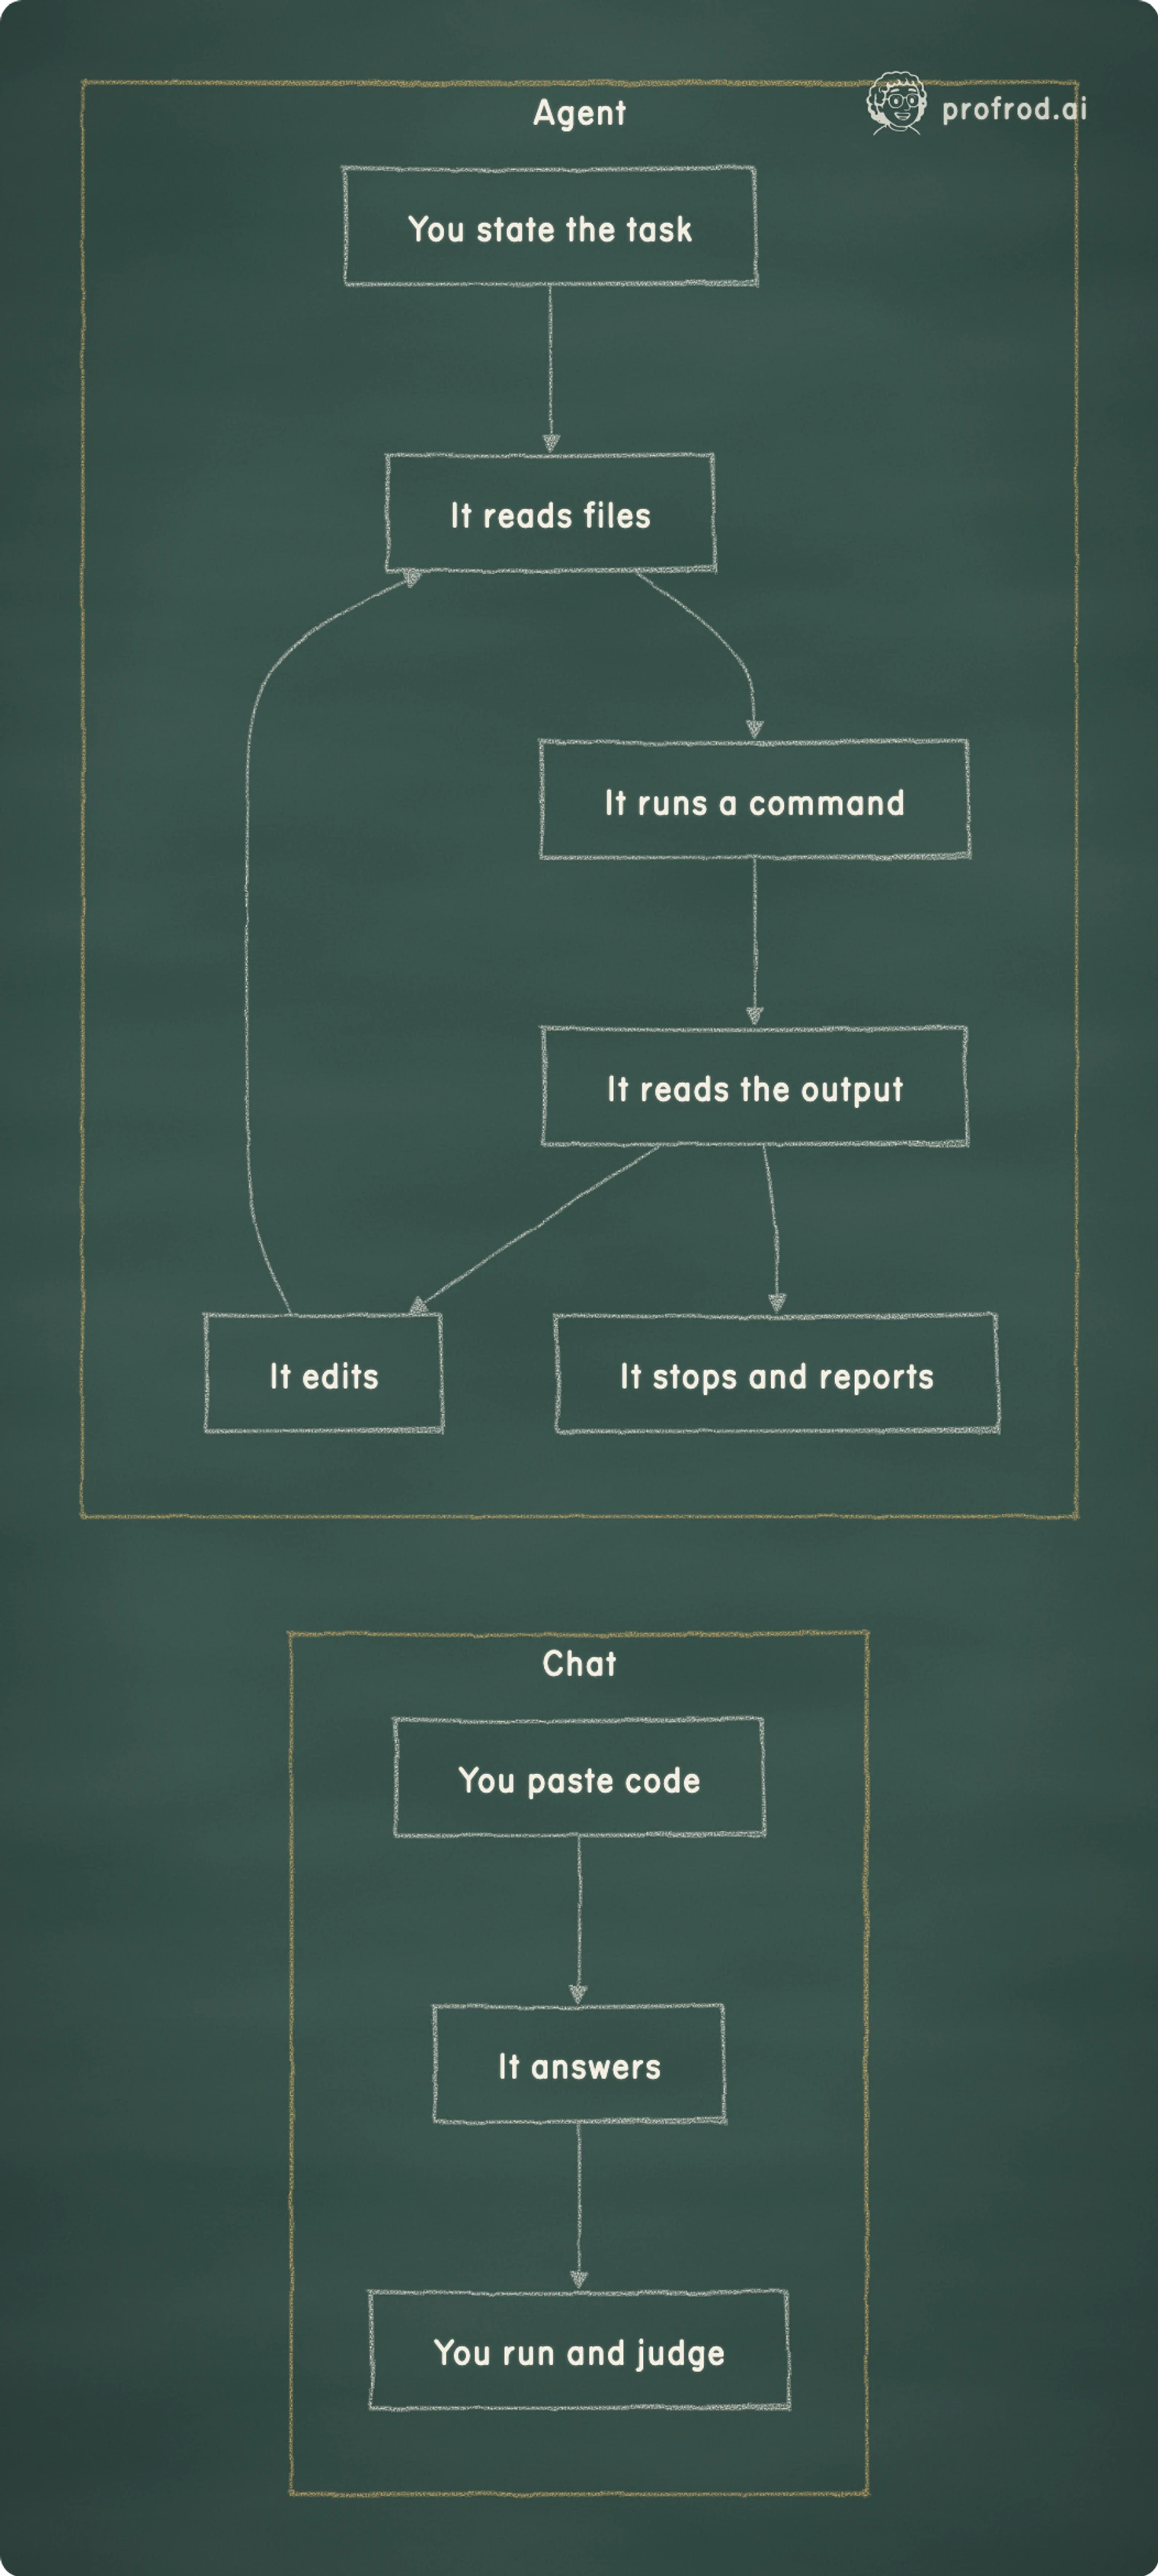
Each turn of the loop is a model call that chooses one action: read this file, run this command, change these lines. The model sees the result, then chooses the next action. Chapter 3 of the book builds this loop from scratch in Python, including the limits that make it stop.
For research work, the loop matters because a single request, such as "rerun the Chapter 16 statistics and compare them with the recorded receipt", can take twenty or forty steps: find the script, read its arguments, set up the environment, run it, parse the output, compare numbers, write a summary.
Why reliability compounds
Suppose each step succeeds with probability p, and the steps fail independently. The session succeeds only if every step does. For two steps that probability is p × p; for n steps it is p multiplied by itself n times:
P(all n steps succeed) = p^nNow put numbers in:
| Per-step success p | Steps n | p^n |
|---|---|---|
| 0.95 | 10 | 0.599 |
| 0.95 | 20 | 0.358 |
| 0.99 | 20 | 0.818 |
| 0.99 | 100 | 0.366 |
Scroll horizontally to view columns.
A step that is right 95% of the time gives a twenty-step session a 36% chance of going through without an error. Each row is plain arithmetic: 0.95 multiplied by itself twenty times is 0.358.
Two things break the simple model, and both matter. Steps are not independent: one wrong assumption early, such as reading the wrong config, can doom every later step. And an agent can recover: when a command fails loudly, it reads the error and tries again. A failure that surfaces becomes a retry. A failure that stays silent, such as a metric computed on the wrong split, carries through to the final summary.
Checks change the arithmetic
That is the practical lesson. You cannot make each step perfect, but you can make errors visible inside the loop, where the agent and you can see them: a test that fails when a metric is wrong, a hash that changes when an evaluation file changes, a script that prints n next to every score. Each check turns a silent error into a loud one, and a loud error is one the loop can repair.
The Chapter 3 reliability exercise asks you to test a reliability claim like this one against a simulation. Do it once; the gap between the independent model and a simulated loop with retries is worth seeing for yourself.
Who decides what
The Anthropic study cited in the previous lesson found that people made about 70% of the planning decisions in a session and about 20% of the execution decisions. In research terms: you own the question, the metric, the baseline and the evaluation set. The agent owns the typing. The rest of this course is about making your part explicit enough that the agent's part can be checked.
Rod Rivera, who teaches this course, spent fifteen years shipping machine learning inside large companies (Alibaba Cloud, Huawei, Samsung) and now teaches AI product engineering at Nebius Academy and as Professor of the Practice at ITAM.
Name the files, the command, the expected output and how you will know it is right, before the agent starts.
The agent reads, runs and edits inside the folder you started it in, within the permissions you set.
The session is not done when the agent stops typing. It is done when you have checked the evidence.
Install Claude Code from a blank machine, then set up the practice repository and run its checks.
Reply here and it goes straight to Rod. Same as replying to one of his emails.


