What Token Factory Is: The Managed Side of the Self-Hosting Trade
Prerequisite: Week 0. Helpful: Lessons 02 and 05 of the NVIDIA NIM course, which derive prefill, decode and batching. After this lesson, you can: say what a managed hosted API moves off your plate compared with a self-hosted container, explain what Token Factory's base and fast flavors trade, and compute how a rate limit caps your throughput.
Nebius are friends of this site. Nobody paid for this course. Rod teaches a module for Nebius Academy (AI Performance Engineering). The relationship is disclosed on this course's page with its start date.
Two ways to buy the same tokens
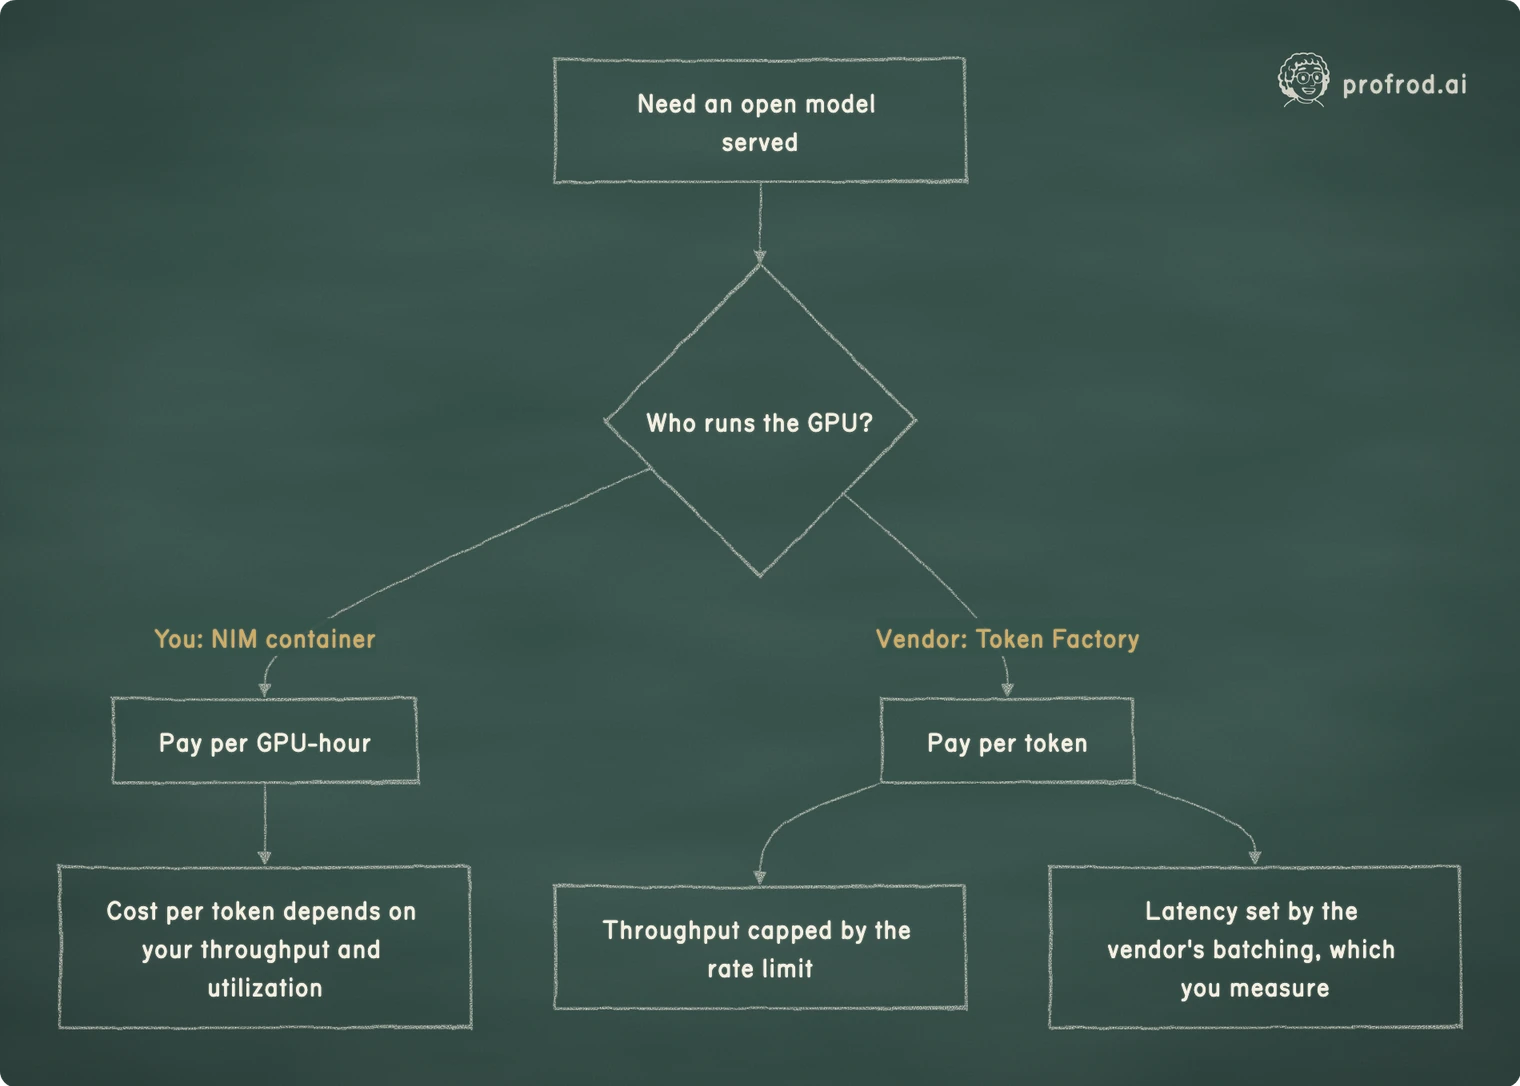
NVIDIA NIM, in the companion course, ships a container you run on a GPU you rent or own. You pay
per GPU-hour, and your cost per token depends on how full you keep the GPU. Nebius Token Factory is
the managed side: Nebius runs the GPUs and you call an OpenAI-compatible API at
https://api.tokenfactory.nebius.com/v1/. You pay per token, and the vendor carries the
utilization risk.
Neither is better in general. The engineering question is which costs you less per successful task at the latency you need, and whether you need the weights on your own hardware for reasons that are not about cost, such as data residency or an air-gapped deployment.
Batching still happens, on their side
The NIM course derives why batching raises throughput: a decode step reads the model's weights
once, so serving many sequences in the same step shares that read. A hosted service does the same
across its customers. Nebius's inference overview
(docs.tokenfactory.nebius.com/ai-models-inference/overview) lists continuous batching, a
key-value cache, paged attention, quantization and speculative decoding among its optimizations,
and it exposes the batching trade directly as two flavors:
- Base and Fast, which Nebius says "deliver identical model outputs. Differences lie in token pricing, latency, and the level of applied optimizations."
- The Fast flavor "uses smaller batch sizes, increased compute allocation, and techniques such as
speculative decoding to reduce latency." You select it by appending
-fastto the model name.
That is the NIM course's batching table seen from the buyer's side. A smaller batch means each step
serves fewer sequences, so each user's tokens arrive faster and each token costs the vendor more
GPU time. A price difference between flavors is the vendor charging you for their lower
utilization. Nebius's June 2026 deprecation notice retired several -fast variants, so check which
models offer one before you plan on it.
A rate limit is a throughput cap
A hosted API caps how much you can send. Nebius's rate-limit page
(docs.tokenfactory.nebius.com/ai-models-inference/rate-limits) describes dynamic limits in
requests per minute (RPM) and tokens per minute (TPM). Its example table starts from a baseline of
60 RPM and 400,000 TPM. When your average use in a 15-minute window reaches 80% of the limit, the
next window's limit rises by 20%, up to 20 times the base allocation; your own defaults are shown in
the console. Over the limit you get HTTP 429, and the headers x-ratelimit-remaining-requests and
x-ratelimit-remaining-tokens tell you how close you are.
Little's law turns a limit into concurrency. On average, requests in flight equal the arrival rate times the time each request takes. At 60 RPM, one request per second, with requests that take 5 seconds end to end:
in flight = 1 request/s × 5 s = 5 requests at a timeAnd the TPM limit caps tokens. At 400,000 TPM with 1,800 tokens per request (1,500 in, 300 out):
400,000 / 1,800 ≈ 222 requests per minute from the token limit
60 requests per minute from the request limit
At this baseline the request limit binds first. At 20 times the base, 1,200 RPM and 8,000,000 TPM, the token limit allows about 4,444 requests per minute, so the request limit still binds. Lesson 02 shows a workload where neither ceiling is close to enough.
What the catalog looks like today
On September 30, 2026 Nebius's public catalog (tokenfactory.nebius.com/model-catalog.md, backed
by the JSON at tokenfactory.nebius.com/api/public/models_info) listed 25 models with prices in
USD per million tokens, per Nebius's playground documentation. Output prices for its chat and
vision-language models ranged from $0.24 (nvidia/Nemotron-3_5-Lightning, and
nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B) to $15 (moonshotai/Kimi-K3): a factor of 62.5 inside
one vendor's catalog.
Each entry also carries a tokens_per_second value. Nebius's documentation describes it as
"approximate generation speed of the model in tokens per second. Actual performance may vary." It
is the vendor's figure, measured in a way the page does not describe. Treat it as a claim to test
with Lesson 04's protocol, not as a measurement.
The catalog moves. When this lesson was first written on August 20, 2026, two Nebius pages fetched
minutes apart named different point releases of the same model family, and none of the five model
IDs this site's older Token Factory lessons used appeared on either page. On September 30 the
public catalog did list one of the five, Qwen/Qwen3-235B-A22B-Instruct-2507; a marketing page is
not the catalog. Lesson 03 shows how to
query the live list and the dated deprecation notices instead of trusting any page, this one
included.
The one vendor number in this course
Nebius's Token Factory page cites a named customer, Prosus, with "up to 26× lower cost" and "up to
200B tokens/day," re-read on September 30, 2026 at nebius.com/services/token-factory. That is a
claim about one customer's workload, not a rate this course can promise you. Lesson 02 tests it
against the price list.
Cost per task, derived: an eval run and an agent loop priced at dated rates, the rate limit as the real constraint on a large job, and what "26x" means inside one catalog.
Reply here and it goes straight to Rod. Same as replying to one of his emails.


