
An eval set from three sources
An evaluation set assembled from three places: a spreadsheet of hand-written prompts, a JSONL file
exported from a labeling tool, and a batch of cases someone pasted from a bug tracker. The same prompt
appears twice with different whitespace. The label column says correct, Correct, pass and
1, meaning the same thing. Some reference answers are empty, and it is not clear whether empty
means "no reference" or "export failed."
It is the same mess as any old customer list, except that here a mistake changes the number you report. The cleaning is not the interesting part. Any competent coding agent will tidy a file. The interesting part is finding out whether it quietly threw away forty rows while it was tidying.
The set and its failure cases are built illustrations, not a real export or a timed run. The failure shapes (inconsistent labels, a silently dropped row, a merge that should not have happened) are the common ones this process catches. This site has not run this yet: a seeded file, cleaned by an agent, with the three counts below recorded, is still to do.
Audit before you fix
The instinct is to ask for the clean version straight away. Don't. Ask what is wrong first, and read the answer before anything changes.
A new folder with one file in it. You want to be able to see exactly what changed, and you want the original untouched.
"Read cases.jsonl. Describe what is inconsistent about it, field by field. Do not change anything yet."
You find out what the agent thinks the problems are before it acts on that judgment. Most surprises happen here, cheaply.
This is the step people skip. If it says one wrong thing about your data, for example that source
is a file name when it is actually the labeling team, you have just saved yourself an afternoon of
undoing.
What usually comes back: inconsistent label spellings, prompts that differ only in whitespace or casing, empty fields that mean "unknown" in some rows and "none" in others, and near-duplicates that are only duplicates if you squint.
That last one is the decision the agent must not make alone. Two prompts that differ by one word might be a duplicate, or might be a deliberate pair that tests whether the model notices the word. You know; the file does not.
Separate standardizing from merging
Start the agent in that folder and ask, roughly:
Standardize this file. Map every label spelling to
passorfail. Trim whitespace in prompts. Keep every row's originalid. Write the result tocases-clean.jsonland do not delete any row. Mark suspected duplicates in a new field calledduplicate_ofinstead.
The instruction that matters is the last one. You are separating two operations that feel like one: standardizing (safe, reversible, mechanical) and merging (a judgment about what the cases are for). Let the agent do the first and only propose the second.
Three counts that turn a hope into a check
An agent that tidies your data will tell you it tidied your data. It will sound confident. It will usually be right. And when it is wrong, it is wrong silently. A parsing error on row 412 drops the rest of the file. A "cleanup" step removes rows with empty reference answers. You find out weeks later, when a result does not replicate.
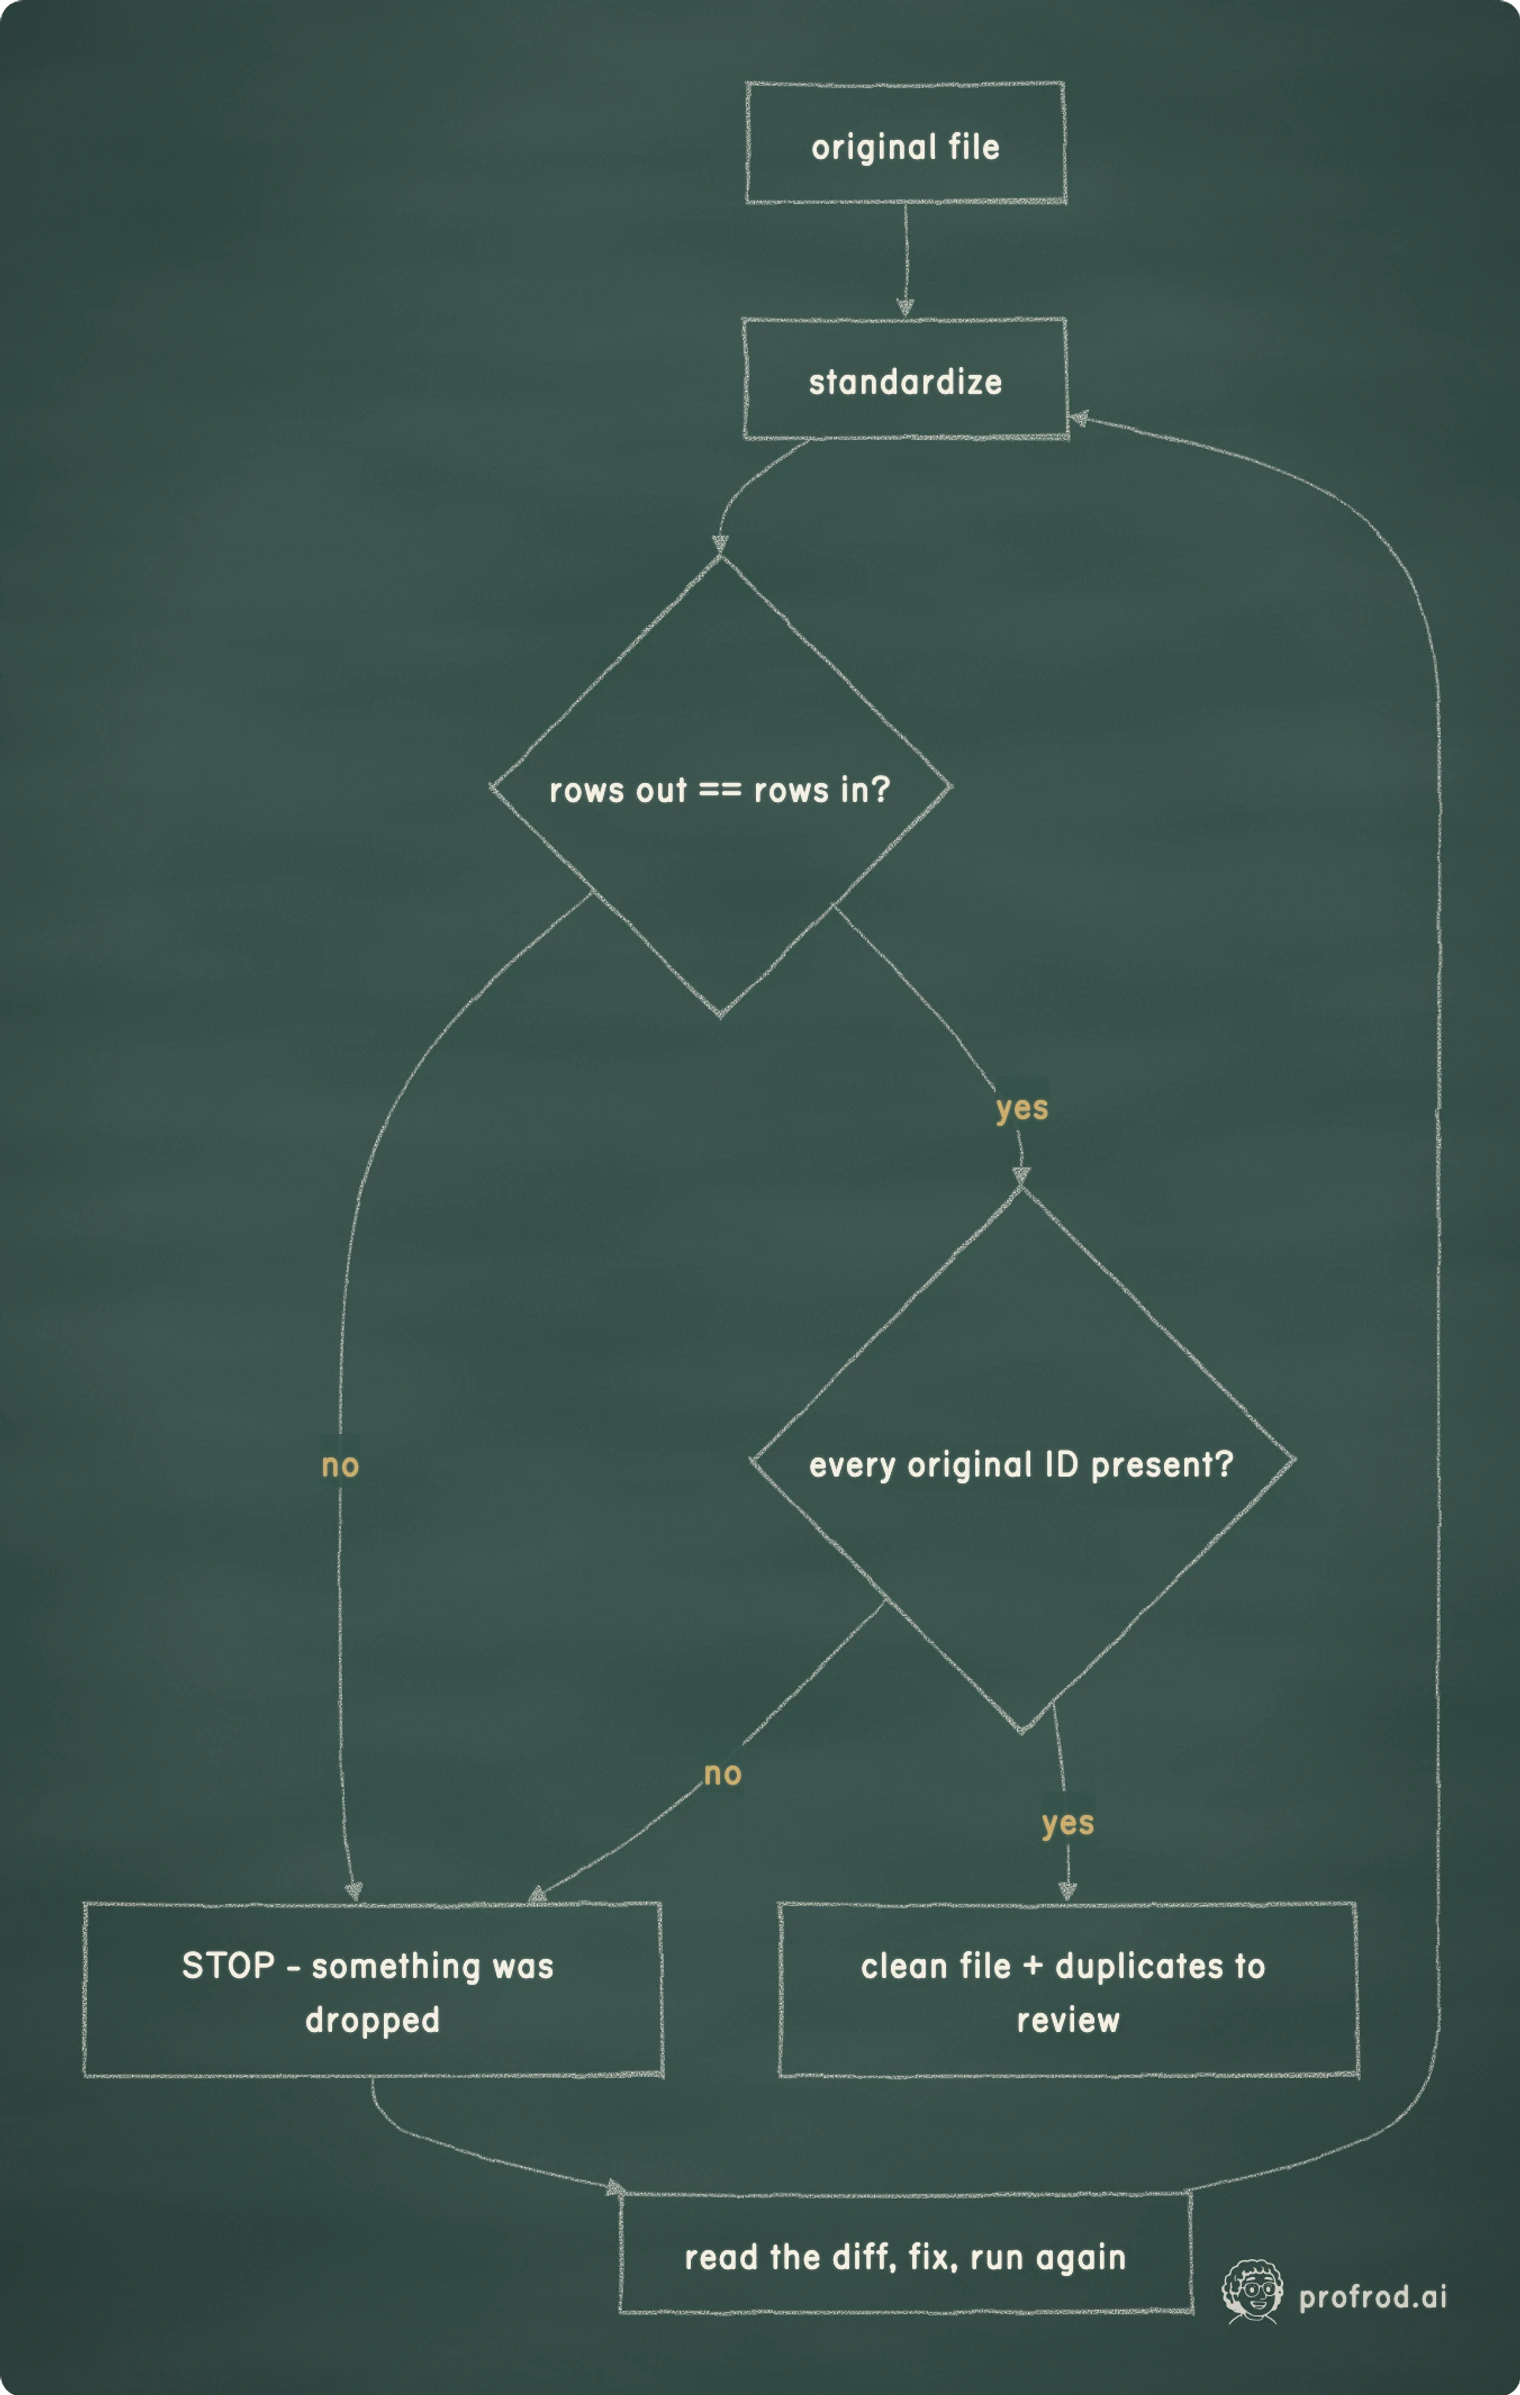
Three answers, and each one catches a different failure.
Row count in against out. It must match exactly, because you told the agent to delete nothing. If it does not match, stop. You have found a bug, not a cleaning.
Unmatched originals, by ID. This catches the subtler case where the count is right but the contents shifted: a row silently replaced rather than dropped.
Distinct values changed, with counts. This finds the real mistakes. "Correct → pass (88)" is fine. "Correct → pass (88), incorrect → pass (3)" is a bug you would never have found by reading the file, because a substring match turned three failures into passes.
You can ask the agent for these counts, but then the agent is checking its own work. A short script you run yourself is evidence it cannot write:
import json
from collections import Counter

def load(path):
    with open(path) as f:
        return [json.loads(line) for line in f if line.strip()]

before, after = load("cases.jsonl"), load("cases-clean.jsonl")
by_id = {row["id"]: row for row in after}

print("rows in:", len(before), "rows out:", len(after), "repeated ids out:", len(after) - len(by_id))
print("originals with no match:", [row["id"] for row in before if row["id"] not in by_id])

changed = Counter((row["label"], by_id[row["id"]]["label"])
                  for row in before
                  if row["id"] in by_id and row["label"] != by_id[row["id"]]["label"])
for (old, new), n in changed.most_common():
    print(f"label {old!r} -> {new!r}: {n}")
The repeated-ID count matters because a row can be duplicated in the output while another is lost, leaving the total unchanged. The same rule holds when an agent changes code: gate on checks the agent did not write.
Why a dropped row moves the number
In an eval set, a dropped row moves the number you report, and it tends to move it in your favor.
Rows that break a parser are rarely random. They are the long ones, the ones with odd characters, the edge cases, which are often the cases a model fails. Suppose the set has 1,000 cases and the model passes 700:
pass rate            = 700 / 1000 = 0.700
drop 50 failing rows = 700 / 950  = 0.737
Nothing about the model changed, and the pass rate rose 3.7 points. Compare that with the error bar on the honest number. A 95% interval for a proportion is about 1.96 × √(p(1 − p)/n):
1.96 × √(0.7 × 0.3 / 1000) = 1.96 × 0.0145 = 0.028The phantom gain is larger than the error bar. A reviewer comparing this run with last week's would see a difference that looks real. Duplicates do the opposite damage: they inflate n and make the interval narrower than it should be. The essay on duplicate records works through that case.
Not a dramatic crash. A quiet, plausible, correct-looking output that is missing something. A green result is not a check; it is a claim. The counts are the check, and they cost one short script.
The list you have to read yourself
Whatever the agent could not resolve goes in a file you open, never into a default it picked on your behalf.
Everything you were unsure about: put it in
needs-a-human.jsonlwith a field saying why.
Twenty rows you decide in five minutes beat two thousand rows you trust in none. The suspected duplicates go here too. You are the only one who knows whether those two near-identical prompts are one case or a deliberate pair.
Why this matters in a lab
Much of research engineering is data work of exactly this kind: assembling eval sets, merging results from runs, cleaning labels. The worst outcome of a silent row problem is a result that does not replicate. A reported gain that came from a dropped row is not a model improvement, and whoever reproduces it will find that out. Building sets that hold up is the core of evals roles.
If a work sample hands you a messy dataset, the counts are the part a reviewer can check. Report rows in, rows out, rows merged and why, and the distinct values you changed. It takes a paragraph and it shows the habit that matters more than the cleaning.
The first task to give an agent is not the most annoying one. It is the one you can check most easily. Cleaning a file qualifies: the correct answer is countable. Start where verification is cheap, and you build the habit before you need it somewhere it is expensive.
The book builds an evaluation harness that says what it checked, with error bars derived and measured on real models.


