Why This Course: Review Agent Edits to Research Code Like a Lab
The instinct you already trust
You already trust your Tab-complete instincts, and they earned it. Reject a bad suggestion, accept a good one, keep typing. A wrong accept costs a few tokens on a line you are already reading.
That instinct carries straight over to Cursor's Agent, and it goes wrong there. In research code, the damage looks worse than a crash: the eval still runs and prints a number, and the number is wrong.
The gap this course closes
Cursor's Agent does not touch one line. Given a task in plain language, it reads across your repo, plans a set of edits, and can write to as many files as the job needs before you see a diff. Then it asks for the same answer Tab trained you to give without thinking: keep it, or throw it away.
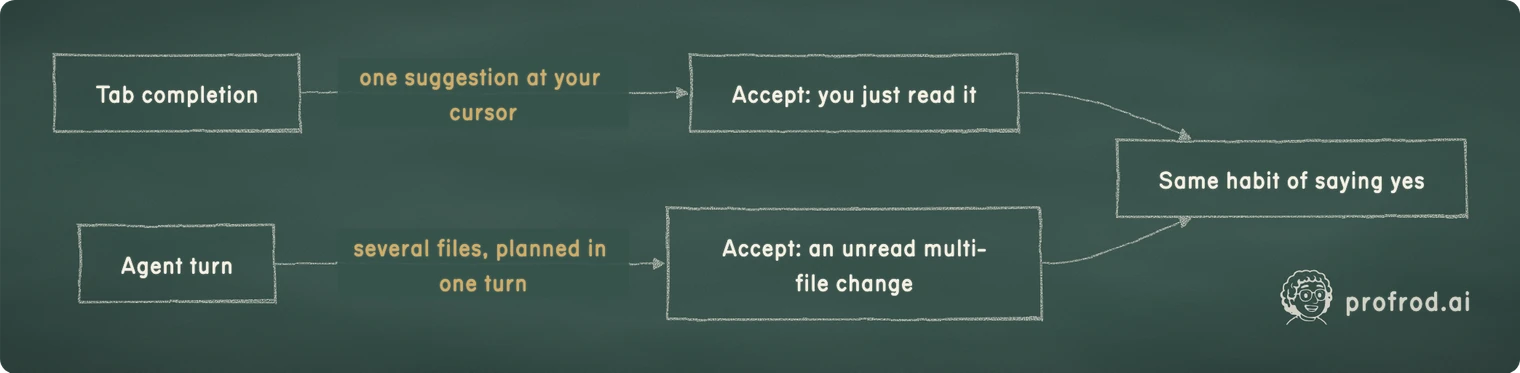
Now put that Agent turn inside an evaluation harness. It edits run.py, adds a sweep.py, and touches metrics.py "to handle an edge case." Every file compiles. The tests pass. The script prints an accuracy. What you have not checked is which split each line reads, whether the metric still computes what your paper's table says it computes, and whether the run gives the same number twice. Those three questions are where research code breaks, and none of them shows up as an error.
Why a lab cares
An applied-AI or research team runs on numbers other people trust: an eval table, an ablation, a comparison between two checkpoints. A reviewer on that team reads your change and asks what could make the number wrong. If an agent wrote half of the change, the reviewer still asks the same thing, and you are the one who has to answer.
The same question shows up in hiring. A take-home or a work-sample exercise gives you a small research task and reads the result. If the task's instructions allow AI tools, a strong submission makes it plain what the agent did and how you checked it. Lesson 11 covers how that reads.
The habit that carries over wrong
If you have clicked accept on an Agent turn faster than you meant to, that is Tab habit doing what it was trained to do, applied to a tool that needed something else from you.
The fix is not to distrust the agent, and it is not to slow every Tab completion to review pace. It is to match your review to what the change can break. For research code, that means a short, fixed list: the split each line reads, the metric's definition, the seeds, and anything outside the scope you asked for.
Lesson 8 walks the case this course is built around: an Agent turn that adds a response cache to an eval harness. The diff is clean, the tests pass, and the cache hands a second model the first model's answers. Two different models then score the same on all 200 items. You run it yourself, start to finish, on a harness small enough to read in one sitting.
What you'll be able to do
By the end, you can tell Cursor's three modes apart and pick the right one. You can write .cursor/rules so the agent knows your split and seed conventions without being told each session. You can review a multi-file agent edit to an eval script the way a lab reviewer would. You can measure your own review's precision and recall on seeded defects, with the arithmetic shown. You can keep your test split out of the agent's reach, and you can describe agent-assisted work honestly in a take-home.
None of that depends on better prompts. It depends on knowing what you are about to accept.
Start here, not in the deep end
Why Tab instincts, unchanged, lead you to accept multi-file changes to research code that you never read.
Reply here and it goes straight to Rod. Same as replying to one of his emails.


