Why This Course: The Work Research Teams Hand to Coding Agents
A research team hands a coding agent work like this: rerun a baseline on a new evaluation split, add a metric to the harness, port a data loader, sweep one hyperparameter over five seeds, write the script behind a paper's table. Each task ends in a number that someone will put in a results table and argue from.
That is the trust problem. The agent ran code you did not watch, then told you what happened. "Accuracy rose to 0.87" can mean a real improvement, a lucky seed, a smaller evaluation set, or an evaluation file the agent edited on its way to a passing run. This course teaches you to use Claude Code on research code so that each number arrives with the command that produced it, the commit it ran on, the seed, the size of the evaluation and an error bar.
What the work requires
An applied-AI or research team expects you to do three things with an agent's result: reproduce it, measure it with honest uncertainty, and say what it does not show. None of that is new. What changes with an agent is the volume: it can run more experiments in an afternoon than you can review, so the review has to be built into how you ask for the work.
Anthropic's own study of about 400,000 Claude Code sessions from about 235,000 people, run between October 2025 and April 2026, points the same way. The report found that people made about 70% of the planning decisions in a session but only 20% of the execution decisions, and that sessions rated novice reached its strictest measure of success 15% of the time, against 28 to 33% for sessions rated intermediate or above. You decide the question, the metric and the baseline. The agent decides how to type it. Your research judgment is what catches the session when it drifts.
The practice repository
Every exercise points Claude Code at one public repository: the course folder for the book, courses/sovereign-agent-book in profrodai-resources. It holds each chapter's notebooks, the chapter code and the receipts that code produced. You will work mostly with Chapter 16's evaluation code: a harness with development, regression and held-out cases, and an evaluation-statistics unit that builds the Wilson interval and McNemar's paired test. The code runs offline with uv on Python 3.12 and needs no API key. Claude Code itself needs a plan or API access that includes it; this free course does not pay for the tool.
It does not describe how any particular lab uses coding agents internally. It teaches the checks the work itself requires, shows the arithmetic, and marks each measurement as either run by this course, recorded in the book's repository, or left for you to run.
What you will practice
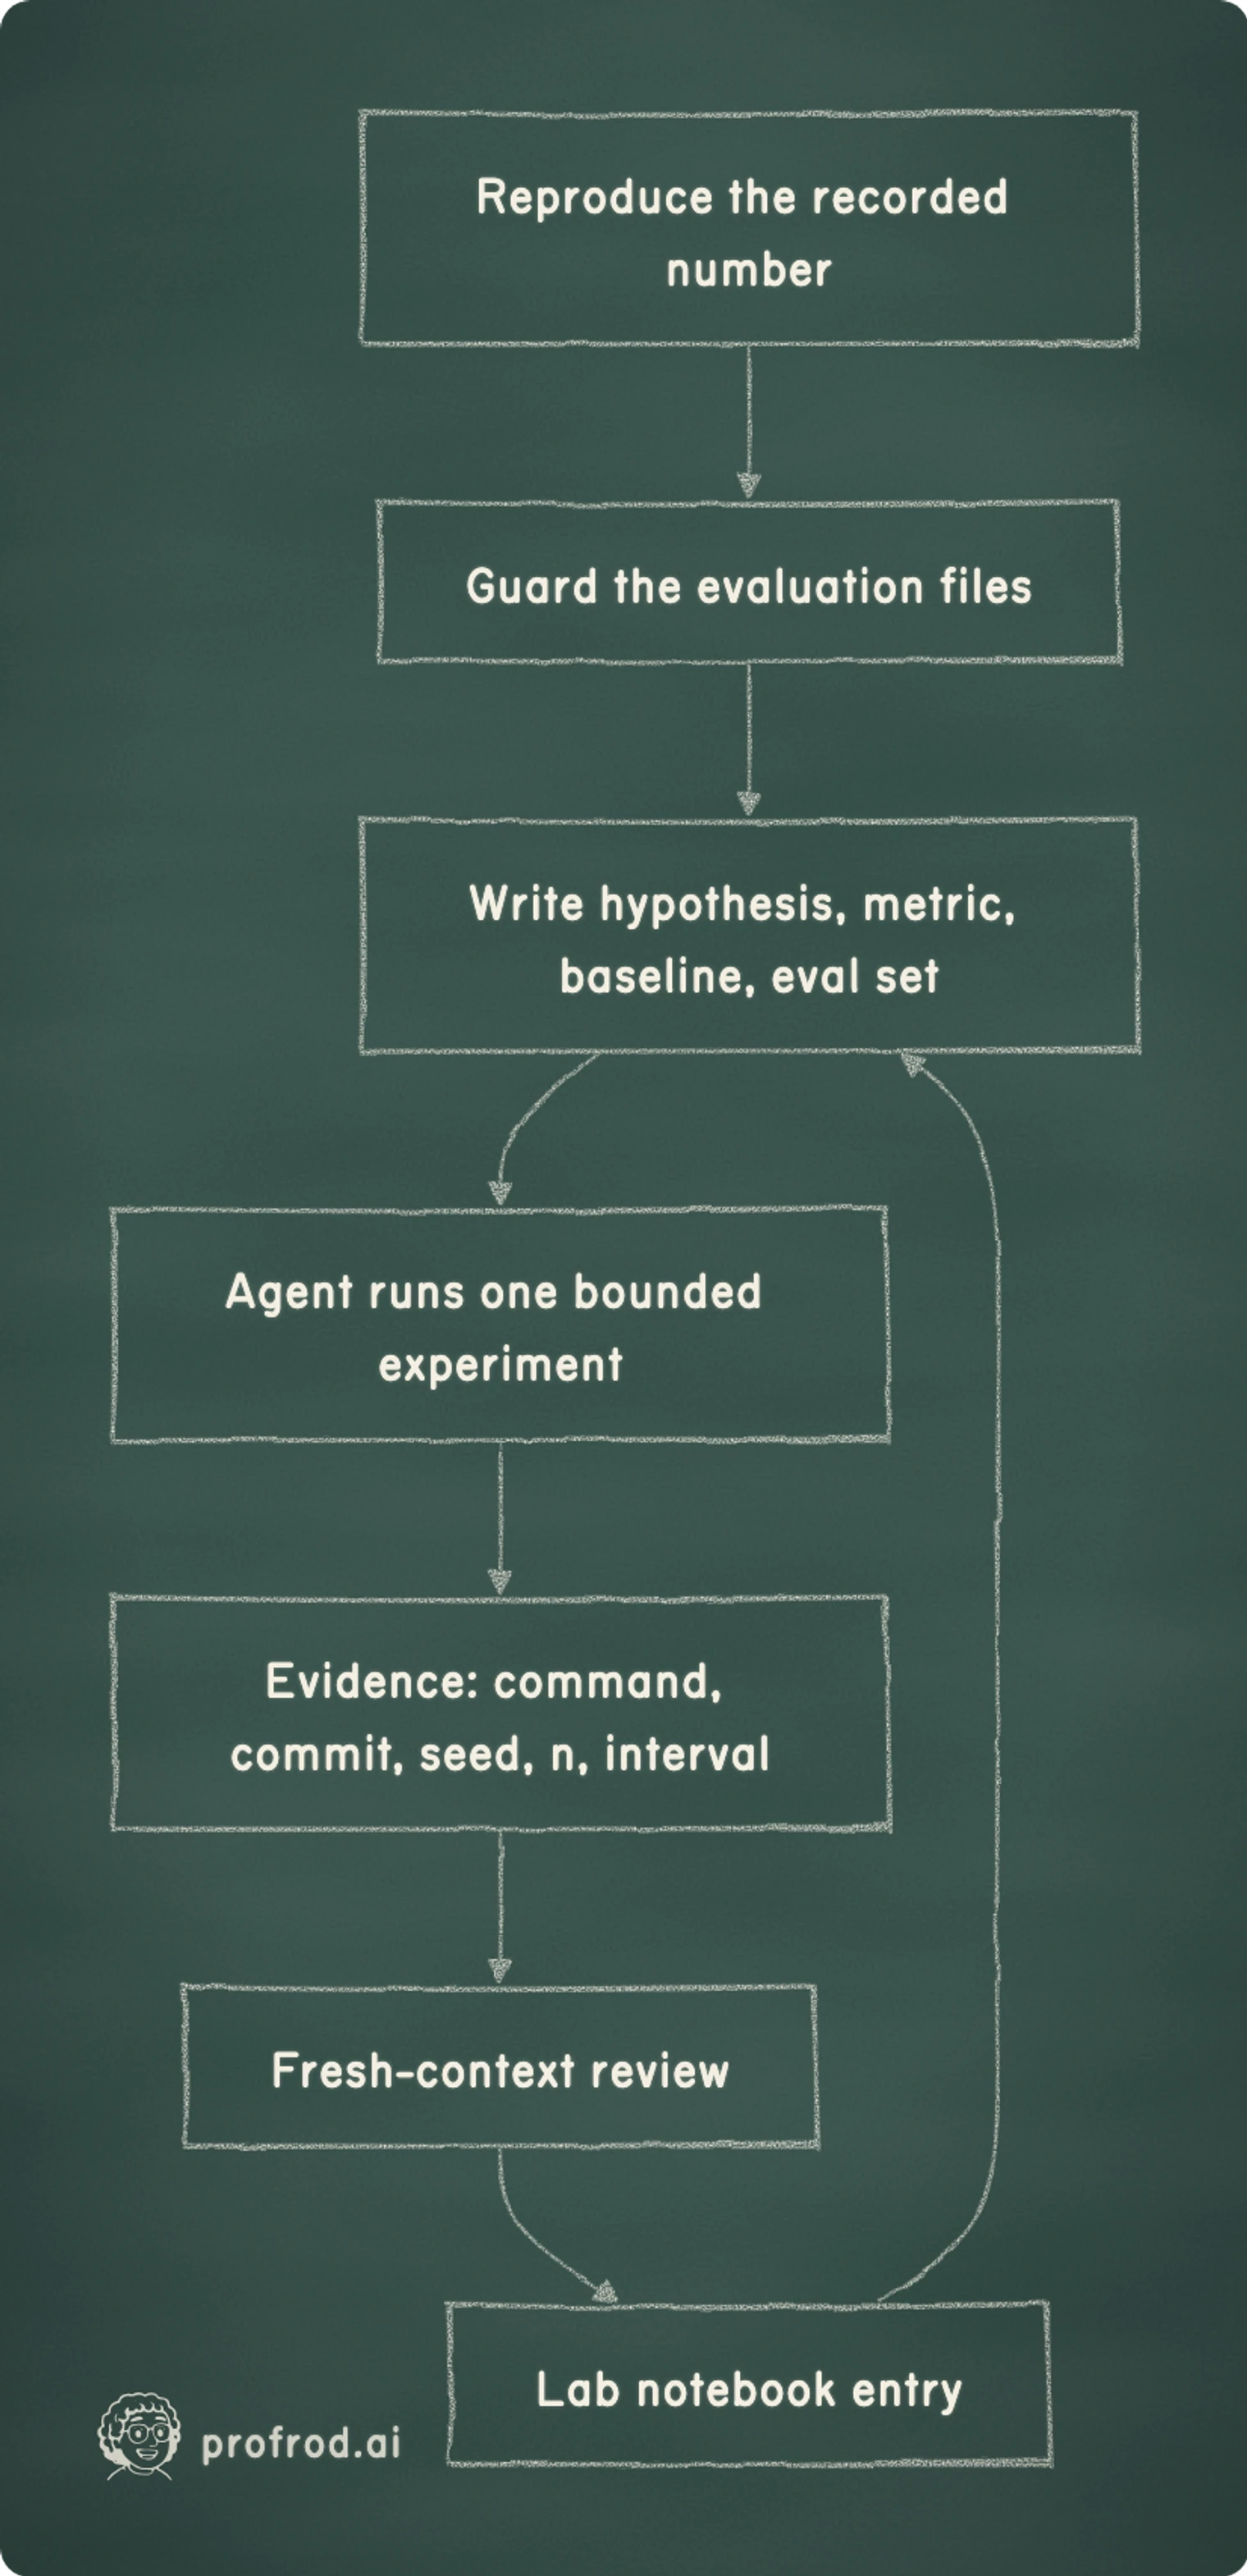
Setup from a blank machine; reproducing a recorded result before you change anything; locking the evaluation files with rules Claude Code enforces; planning an experiment before code; sizing it to one question; demanding evidence with a binomial interval; writing durable project instructions; running experiments in parallel; reviewing agent-written research code with a fresh context; and a first-week plan that includes how to talk about agent-assisted work in an interview loop or a take-home.
Before the next lesson, pick one number from your own work or from the practice repository that you would like to be able to defend. Keep it in mind as you read.
How an agent loop differs from a chat exchange, and why reliability compounds over the steps of a session.
Reply here and it goes straight to Rod. Same as replying to one of his emails.


