Week 0: What a Hosted Token Costs
Prerequisite: none. This is a short orientation, not a lesson. After this, you can: say what this course derives, what it has not measured, and whether it is worth four lessons of your time.
Nobody paid for this course
Rod teaches a module for Nebius Academy, AI Performance Engineering. That relationship is disclosed on this course's page: Friends of this site since 2026-08-20. Nobody paid for this course. It buys no softer review. The course names where the product's own pages disagree with each other, where its catalog has retired models this site still uses, and where a vendor number needs checking.
The hosted side of the trade
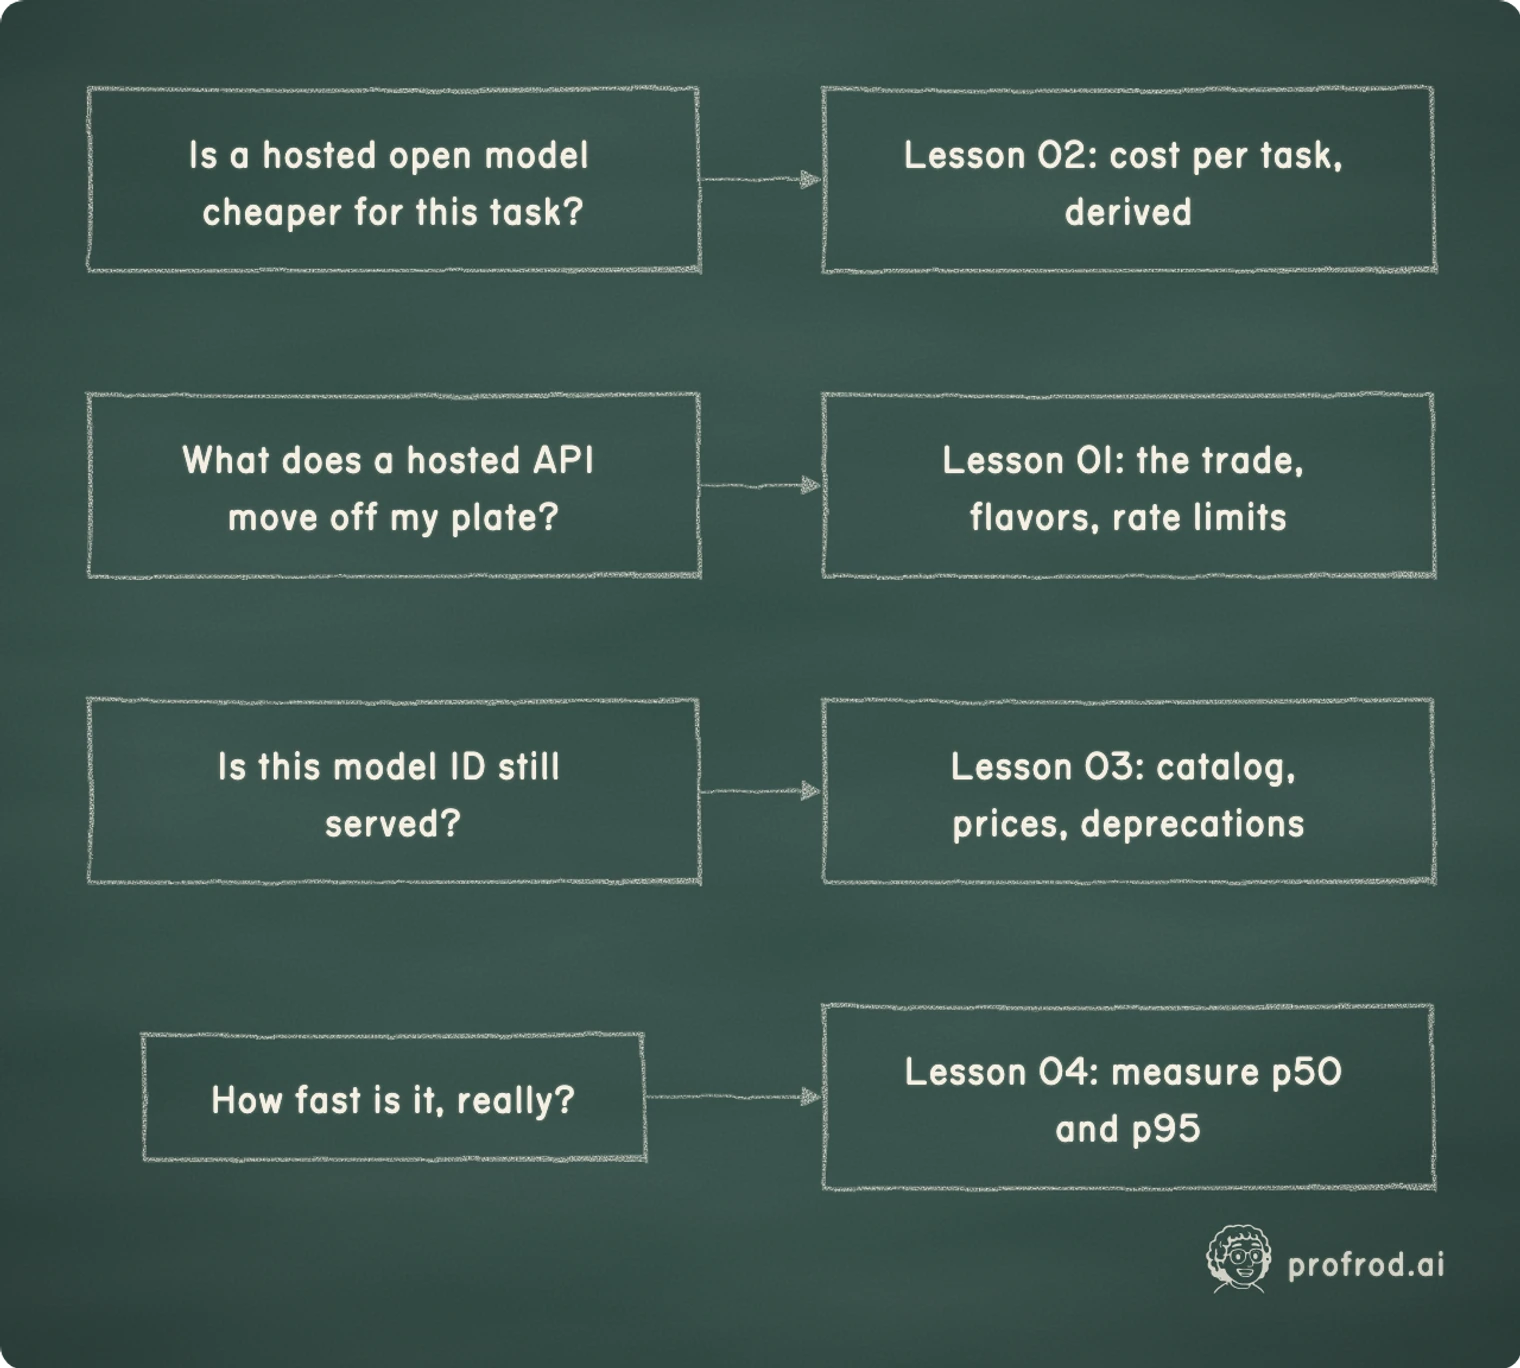
The companion course, Inference Economics on NVIDIA NIM, works from the GPU up: you rent the hardware and pay for every hour, busy or not. A hosted API is the other side. Someone else runs the GPUs and batches your requests with everyone else's, and you pay per token. That moves three things onto your desk, and an applied-AI engineer is expected to handle each one:
- A price list: dollars per million input and output tokens, which you turn into cost per task and, with an eval, cost per successful task.
- A rate limit: requests and tokens per minute, which caps your throughput no matter how cheap the tokens are.
- A catalog that changes: models retire on a published date, and a latency or success rate you measured belongs to one model ID.
What this course caught on this site
This site's course on tools, memory and multi-agent systems has a lab, in its lesson 08, that calls
meta-llama/Llama-3.3-70B-Instruct on Token Factory. Nebius's August 2026 deprecation notice,
read again on September 30, 2026, says that model and nine others left Token Factory's serverless
API on August 31, 2026, and that "Token Factory does not automatically reroute requests from
deprecated models." When this course was first written on August 20, it recorded
Qwen/Qwen3-30B-A3B-Instruct-2507 as the named replacement. On September 30 the notice named
nvidia/Nemotron-3_5-Lightning. Either the notice changed or the first reading was wrong; Lesson 03
shows the current text and how to check it yourself. That lab has not been updated yet.
What this course has not done
No Token Factory API key was available while this course was revised, so it has measured no latency, throughput or cost on Token Factory and presents none as measured. Its prices come from Nebius's public catalog, read on September 30, 2026. Its measured numbers, where it needs any, come from the book. Lesson 04 gives you the protocol to measure the rest yourself.
Two lessons were planned and cut before the first version: fine-tuning and dedicated endpoints. No first-party record exists of Rod running either on Token Factory, and a lesson without one is not written here to fill a slot.
What a managed API moves off your plate compared with self-hosting, and what base and fast flavors and rate limits do to latency and throughput.
Reply here and it goes straight to Rod. Same as replying to one of his emails.


