
The sentence the pricing pages leave out
You ask one short question in an agent session that has been open since the morning. It is billed as if you asked the model to reread the whole morning, because that is what happened.
The model remembers nothing between requests. An agent loop resends the full context every time: the system prompt and tool definitions, instruction files, every message and every tool result. Each tool call inside a turn is another request. So cost scales with the context you carry, not the size of what you ask.
That holds for any agent you build or evaluate, and it is a common interview question: what does one task cost, and what would you change to halve it? This piece derives the answer for a general loop and uses Claude Code as the worked instance, because its costs documentation states the behavior plainly: a one-line question in a session that has been open all day still draws usage for the whole conversation.
Prices are Anthropic's list prices from its pricing page, and Claude Code behavior is as the vendor's docs describe it at code.claude.com/docs, both checked on September 30, 2026. All prices are in USD. The task sizes are illustrative, constructed to show the shape of the calculation, not measured from a session. The mechanics are durable; the numbers are not. The register at the end says where to recheck each one.
Derive the cost of one agent task
Model a task as a loop of n model calls. The first request carries P₀ tokens: system prompt, tools, instruction file and your request. Each round trip appends about Δ tokens of model output and tool results. Call k (counting from 0) sends P₀ + k·Δ tokens, so without caching the input over the task is
input tokens = n·P₀ + Δ·n(n − 1)/2
The second term grows with the square of the number of calls.
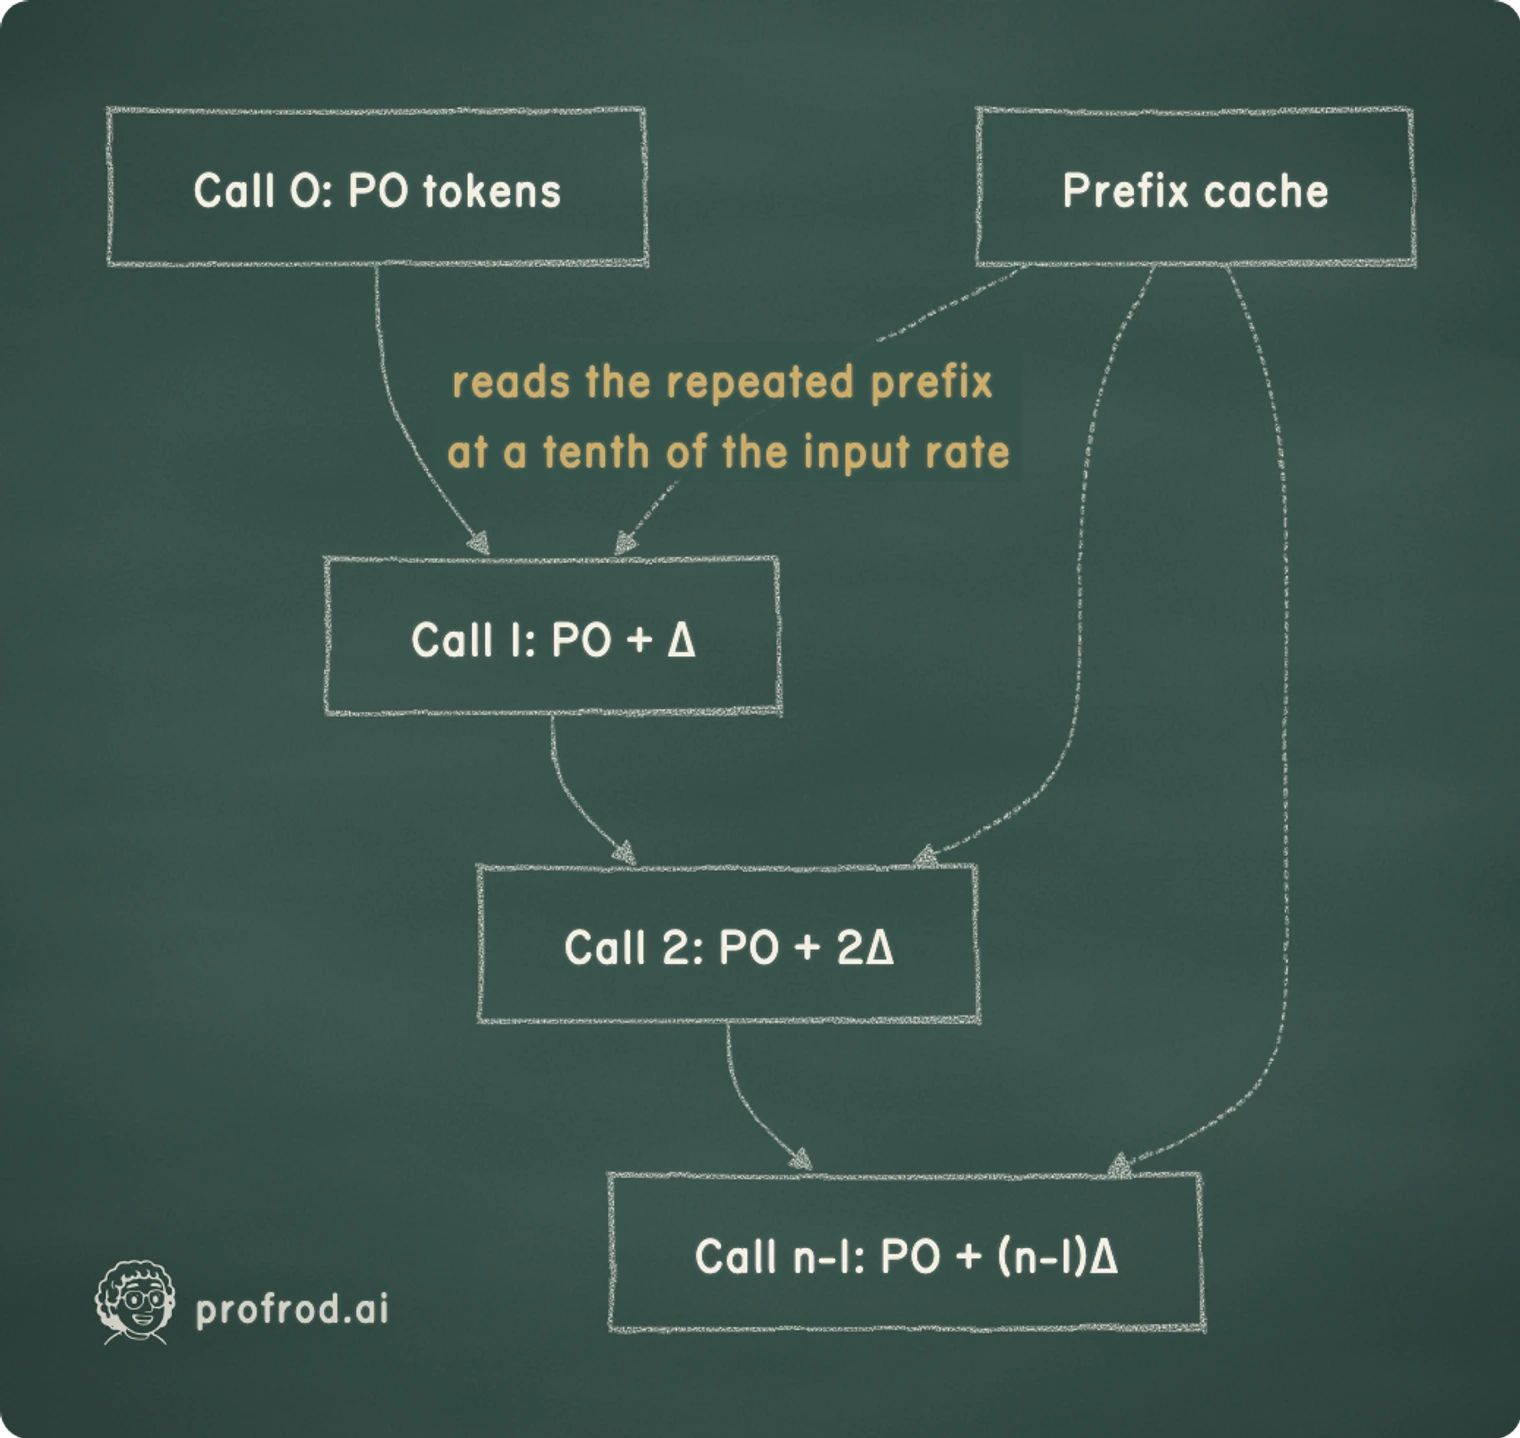
Chapter 19 of the book derives the same sum and plots it.
With caching, request k reads everything the previous request cached, P₀ + (k − 1)·Δ tokens, at the read rate, and writes the new Δ at the write rate. On September 30, 2026, Anthropic's pricing page listed Claude Sonnet 5.5 at $2 per million input tokens, $2.50 for five-minute cache writes (1.25x), $0.20 for cache reads (0.1x) and $10 for output. Here is the function, with an illustrative task of 30 calls, a 20,000-token starting prompt, 3,000 tokens added per round trip and 800 output tokens per call:
def task_cost(calls, first, added, output_per_call, price_in, price_out,
              write=1.25, read=0.10, cached=True):
    """Dollars for one task of `calls` model requests; prices per million tokens."""
    if not cached:
        billed = calls * first + added * calls * (calls - 1) // 2
    else:
        billed = write * first                   # the first request writes the prefix
        for k in range(1, calls):
            previous = first + (k - 1) * added   # read back from the cache
            billed += read * previous + write * added
    return (billed * price_in + calls * output_per_call * price_out) / 1_000_000

print(round(task_cost(30, 20_000, 3_000, 800, 2.00, 10.00, cached=False), 4))
print(round(task_cost(30, 20_000, 3_000, 800, 2.00, 10.00), 4))
It prints 4.05 and 0.8671. Check the uncached line by hand: 30 × 20,000 + 3,000 × 30 × 29 / 2 = 600,000 + 1,305,000 = 1,905,000 input tokens at $2 per million is $3.81, plus 24,000 output tokens at $10 per million is $0.24. With caching, 1,798,000 tokens come back as reads, and the input bill falls to $0.63. The output line, $0.24, does not move: caching does nothing for output.
Cache hygiene is the largest dial
The saving above assumes every read lands. Prompt caches match on the prefix, so a change anywhere early in the prompt recomputes everything after it. In any agent loop, that means: switching models (each model has its own cache), changing the tool definitions, editing the system prompt or putting something that changes (a timestamp, a status line) near the top, and pausing longer than the cache lifetime.
The lifetime has a price. In the illustrative task, a pause past the lifetime before call 15 turns a read of 62,000 tokens into a write: 62,000 × (1.25 − 0.1) × $2 per million ≈ $0.14, about a sixth of the whole cached task.
- Switching models reads the history with no hits. The
opusplansetting switches between Opus and Sonnet as you enter and leave plan mode, so each toggle is a switch. - Changing effort level recomputes the whole request on most models. On Opus 5.5, Sonnet 5.5 and Fable 5.1 with an API key or a Claude subscription, the cache is kept.
- Turning on fast mode misses the cache once per conversation, at fast-mode rates.
- Changing the tool set invalidates the cache unless tool search is on (the default on supported models).
- Upgrading Claude Code usually rebuilds the cache, because the system prompt or tools changed.
- Lifetime: one hour for the main conversation on a subscription within plan usage; five minutes on an API key, a cloud provider or usage credits, and for subagents unless you set longer.
- Scope: effectively one machine and directory, because the prompt names the working directory and git status. Parallel git worktrees build separate caches.
Source: Claude Code prompt caching, checked September 30, 2026.
The diagnostic is the same in any loop: watch cache-write tokens (cache_creation_input_tokens in Anthropic's API). If they stay high turn after turn, something is changing your prefix.
Thinking bills as output
On Anthropic's pricing, thinking tokens are billed at the output rate, five times the input rate for Sonnet 5.5 at the list prices above, and caching does not discount output. Anthropic's docs say extended thinking is on by default in Claude Code and cannot be turned off on Opus 5.5, Sonnet 5.5 and the Fable models; the effort level is the dial. Lower effort for scoped mechanical work and raise it where the failure mode is under-investigation.
Price the solved task, not the attempt
An agent does not solve every task. If an attempt costs c and succeeds with probability p, and a failed attempt can be detected and retried independently, the number of attempts until success is geometric with mean 1/p. So
cost per solved task = cost per attempt / pass rate
At the illustrative $0.87 per attempt and a pass rate of 0.6, a solved task costs $0.87 / 0.6 ≈ $1.45. The pass rate is an estimate, and the ratio inherits its error. From 50 tasks, a binomial interval is 0.6 ± 1.96·√(0.6 × 0.4 / 50) = 0.6 ± 0.136, so the cost per solved task lies roughly between $0.87 / 0.736 = $1.18 and $0.87 / 0.464 = $1.87. A cheaper model that halves the attempt cost but drops the pass rate below half the original costs more per solved task. The review-queue article adds the human review each attempt costs.
The independence assumption is the weak point. A task the agent fails once it tends to fail again, so retries buy less than 1/p suggests. Chapter 16 covers why repeats are not new cases and how to estimate pass@k honestly.
Check the decision
A subscription is a different meter: per the vendor's docs, a per-seat allowance that resets on a rolling five-hour window and a weekly window, rather than dollars per token. The dollar figure in /usage is a local estimate at list price, and the Console is the authoritative bill. For scale, the vendor's costs page reports an average of around $13 per developer per active day across enterprise deployments; that is Anthropic's figure, not a measurement from this site.
Measure it: a protocol for your own agent
This site has not run this protocol yet; the numbers above remain illustrative until it does. It is how you would replace them with measured ones, for Claude Code or any agent that logs its usage.
Take 20 or more issues from a research repository, each with a failing test that defines success, and a rule that no test file may change. Freeze the commit.
For Claude Code, run claude -p "<task>" --output-format json. The JSON includes total_cost_usd, a per-model cost breakdown and usage fields; the docs describe these as client-side estimates. Consider --bare so hooks, plugins and CLAUDE.md from the host do not vary between runs, and a budget cap with --max-budget-usd.
Record task ID, commit, model and effort, input, cache-read, cache-write and output tokens, estimated dollars, wall time, and pass or fail from the tests, not from the agent's own summary.
Report total cost, the number solved, cost per solved task, and the pass rate with its binomial interval. Reconcile the estimated dollars against the provider's bill for at least one day.
Each line is a priced, scored observation. A set of them tells you which model and effort level give the lowest cost per solved task on your work, which is the question a team deploying agents has to answer before scaling anything.
What an interviewer would ask
Expect to be handed a transcript length and a price table and asked for the bill, and then for the dial that matters most. A strong answer names the quadratic resend, the read discount, the events that break the cache, and then says what the bill is per solved task, with an error bar on the pass rate. A weaker answer quotes a per-token price and stops. Inference engineer and applied AI engineer roles both ask for this kind of reasoning; on October 2, 2026, the jobs board found inference and serving mentioned in 44% of research engineer postings and 32% of applied AI postings.
Register of claims to recheck
Checked September 30, 2026. This is the fastest-changing material on the site. Recheck every figure before relying on it.
| Claim | Recheck at |
|---|---|
| Sonnet 5.5 prices; write 1.25x and 2x, read 0.1x | platform.claude.com/docs/en/about-claude/pricing |
| Cache lifetimes by billing and request type; invalidating actions; cache scope | code.claude.com/docs/en/prompt-caching |
Enterprise averages, /usage estimate, thinking billed as output | code.claude.com/docs/en/costs |
total_cost_usd in --output-format json, and --bare | code.claude.com/docs/en/headless |
Scroll horizontally to view columns.
The chapter derives prefill, decode, the key-value cache and the cost of an agent loop from first principles, with measured runs, and ends with an exercise that prices a loop with caching.


