
From a software factory to any factory
A dark factory is a manufacturing term for a plant that runs with the lights off, because no one works on the floor. A dark software factory applies the idea to code: a request goes in, coding agents write the change, tests and checks decide whether it ships, and no person touches each change on the way. Cognition (Devin), Factory (its Droids), Augment and Warp all now build or sell exactly this, and the labs directory lists the companies working on it.
The idea does not stop at software products. Once a piece of work is written as code, the same factory can run it. A monthly report is a script plus its data. A publishing schedule is a calendar file plus the checks that prove each piece went live. A reconciliation is a diff with a tolerance. zeo, the factory this site runs on, applies the pattern to all of these: records, reviews, schedules and releases, as well as software. In a world where most work can be coded, the question stops being can an agent do it and becomes what checks it.
It means what serverless means. There are still servers; you no longer manage them as the unit you scale. A dark factory still has a person. That person writes the specifications, owns the checks and reads what review samples. People are no longer the thing that grows with output.
This page is about what that person can and cannot do, because that is what caps the factory.
What a factory scales, and what it cannot
A new agent starts with the factory's written rules, its repositories and its prior records. There is no onboarding period, because there is nothing social to learn.
Every output that matters must be checked. This is the real constraint, and the next section puts a number on it.
The scarcest resource in the factory, and the one the whole design exists to protect.
The arithmetic of one reviewer
Suppose the operator can spend V minutes a day reviewing, each output takes r minutes to check, and a fraction f of outputs gets reviewed. The number of outputs the factory can ship per day is
N = V / (r × f)With illustrative numbers, not measurements: five hours of review (V = 300) and six minutes per output (r = 6). Reviewing everything (f = 1) caps the factory at 300 / 6 = 50 outputs a day. No amount of extra compute moves that number, because compute was never the constraint.
Review one output in five (f = 0.2) and the ceiling rises to 300 / (6 × 0.2) = 250. The price is paid in errors that nobody sees. If a fraction e of outputs is wrong, the expected number that escape review each day is
escaped = N × e × (1 − f)At e = 0.05, that is 250 × 0.05 × 0.8 = 10 wrong outputs a day, shipped under the factory's name. At full review it is zero, and the factory is five times smaller.
You can make each check cheaper (lower r: tests, schemas, a grader whose agreement with people you have measured) or make fewer outputs wrong (lower e). Buying more agents moves neither. That is why the factories that get further are the ones that invest in checks, and why who may change the acceptance tests matters so much.
The control layers of a factory that holds up
Stafford Beer's Viable System Model, written for organizations in the 1970s, turns out to be a good map of a factory's controls. Ashby's Law of Requisite Variety explains why: a control system must carry at least as much variety as the work it regulates, and agents are how a small team acquires that variety.
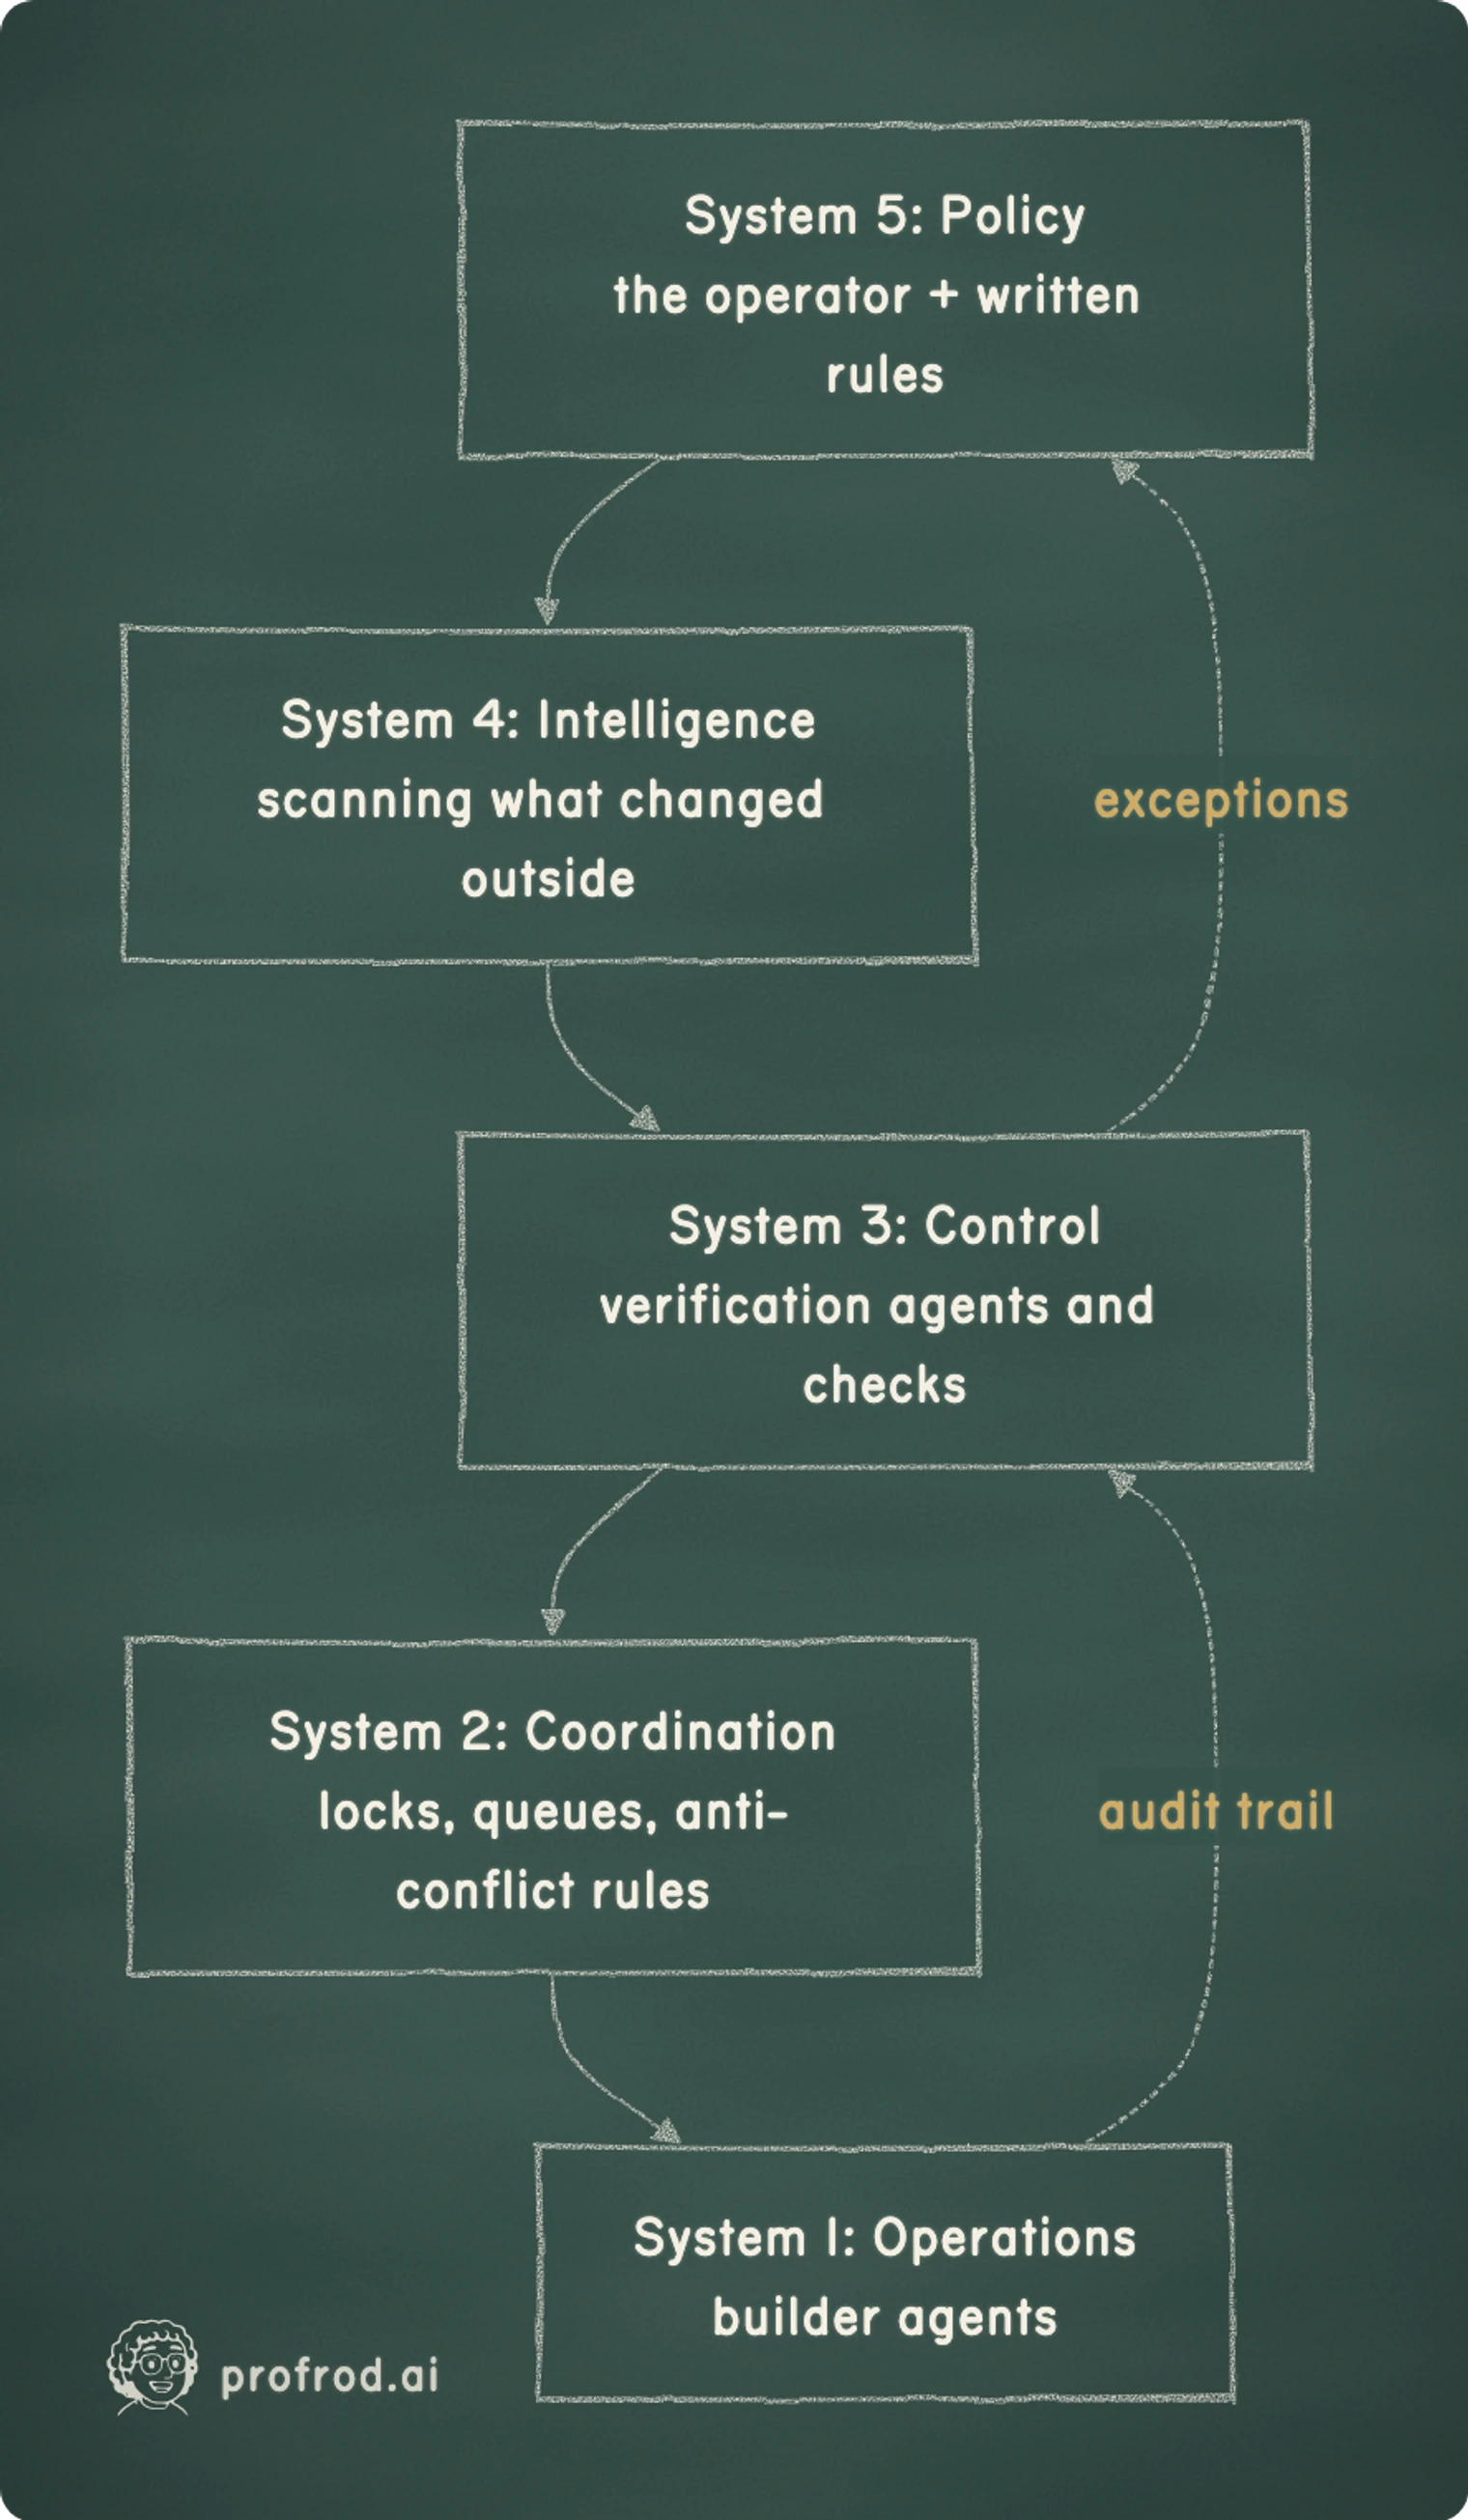
The factories that hold up in production have all five layers. The ones that fail usually lack System 3: an audit layer independent of the agent that did the work. An agent has no self-interest, yet the old agency problem survives in a new form. What economists called shirking is now hallucination and reward hacking; what they called monitoring cost is now verification gates and audit trails. Test gaming, measured on small models, shows what that looks like when the agent can edit its own tests.
Where a factory breaks: unwinding
A factory is strongest at producing and weakest at unwinding. Agents generate at enormous volume. Real work also needs transactions that close deterministically, liability and exception handling. A factory can produce ten thousand outputs in an afternoon; it cannot as easily reverse a cascading error across three external systems after an agent wrote a null value into something binding.
If the cost of recovering from autonomous errors grows faster than the volume of output, the factory stops multiplying one person's work and becomes a liability trap. Everything in a serious design (gates that fail closed, escalation over silent failure, an independent audit layer) exists to keep recovery cost growing more slowly than output.
A case study: the factory that runs this site
profrod.ai is built and run by zeo, which is why none of this is abstract here. One operator directs agent streams. Each stream works under a written statement of work that names, in one line, how anyone would know the work is finished, and the operator reviews what lands before it merges. The controls of that factory shows the records and the checks that refuse a claim without a stopping condition.
What running it has taught matches the arithmetic above. The number of agents was never the limit. The limit was how many results the operator could read closely in a day, and the work that raised it was making each result cheaper to check.
One judgment, three runs
Before this page was about factories, it audited eleven families of management theory against the same condition: which conclusions survive when the workforce stops being human? The same author ran the audit three times, in separate sessions, without looking back. Seven of the eleven verdicts changed between runs. Only four (cybernetics, agency theory, motivation theory and strategy) held.
That instability is the lesson worth keeping, and it is an evaluation lesson: a single run of a judgment is one sample, and a second run can disagree with it. Did model A really beat model B? measures the same effect on agents. The organizational questions themselves, which management theories survive and what an organization built this way owes its people, belong to Zero Employee, the separate community built around them.
Why this matters in a lab
Cognition, Factory and the coding teams at every frontier lab are building factories like this one, and the question at the center of this page has a research name. Scalable oversight asks how people can supervise systems whose output they cannot easily evaluate; AI control asks which protocols (trusted monitoring, audit sampling, restricted permissions) keep an untrusted agent's mistakes from shipping. The operator with 300 review minutes is the small, practical version of both.
An interviewer for an applied-AI or agents role could fairly ask: an agent produces 500 outputs a day and you can check 50; what do you do? A strong answer derives the escaped-error formula, proposes cheaper checks with measured agreement, and states what a sampled review cannot catch. Chapter 11 of the book derives when an agent may act without a human check.
What would prove this wrong
Three findings would. If recovery cost grows faster than output volume. If verification capacity turns out to be capped well below useful scale, so that no cheaper check exists for most work. If a factory's memory proves impossible to maintain across stateless sessions. Each can be watched in the open, including on this site.
The five-part workshop builds a small factory from scratch: the request, the tests, the checker and the record.


