The number that looked like good news
A research team runs a coding agent against its issue queue: evaluation-harness fixes, data-pipeline changes, experiment scripts. At the end of the month someone reports that accepted pull requests rose from 340 to 410. It goes on a slide. During the same month the team changed which tasks the agent attempted, swapped in a newer model halfway through, and added a second reviewer. Did the agent improve, did easier tasks grow, or did the extra reviewer pass borderline work that would have been rejected? A raw accepted count cannot say.
This is the operational review problem: deciding from a month of agent work what to change next. It is the same problem as comparing two models on an evaluation whose composition changed, and it uses the same tools: fixed denominators, stratified comparison and error bars. Anthropic's writing on evaluating agents makes the related point that tasks, environments, trajectories and outcomes need separating, and that one aggregate cannot establish every requirement. A month of production records is that problem looked at backward.
Why a success-only ledger misleads
A ledger that counts only accepted outputs is a survivorship filter. It deletes failed attempts, escalations and work still waiting, and so changes the denominator. If the agent attempted 500 tasks and 410 were accepted, the rate is 82%. If 40 attempts are dropped as "not real," the same 410 over 460 reads 89%. Nothing about the agent changed.
The fix is definitional. Decide before the month starts what counts as an attempt, and put every logical task in exactly one status at the cutoff: accepted, refused or unresolved. Keep individual attempts in a linked event log so retries do not look like extra completed tasks. Refused means the output failed an acceptance check or a reviewer rejected it. Unresolved means acceptance is still undetermined at the cutoff: waiting for review, or waiting on an external result, such as a job submitted to a cluster that has not finished. It is a status at a point in time, not an outcome.
The worked table
A bounded teaching example. Every number is constructed for this walkthrough, not measured from any team.
| Task family | Attempted | Accepted | Refused | Unresolved | Review minutes | Notes |
|---|---|---|---|---|---|---|
| eval-harness fix | 120 | 96 | 18 | 6 | 410 | Stable family, same model all month |
| data-pipeline change | 150 | 118 | 24 | 8 | 560 | Model swapped mid-month |
| experiment script | 90 | 71 | 11 | 8 | 300 | New family, added in week 2 |
| cluster job | 60 | 41 | 9 | 10 | 240 | Submits jobs; highest unresolved share |
Scroll horizontally to view columns.
Two things stand out. "Accepted outputs rose" says nothing about which family drove the rise: experiment scripts are a new family, so their 71 acceptances are new volume, not better performance on old work. And cluster jobs have the highest unresolved share, 10 of 60 or about 17%. Unresolved does not mean failed. A job may still be queued, or it may have run with an unknown result; the status alone does not say whether anything happened on the cluster. Counting those as accepted overstates reliable output; counting them as refused understates it.
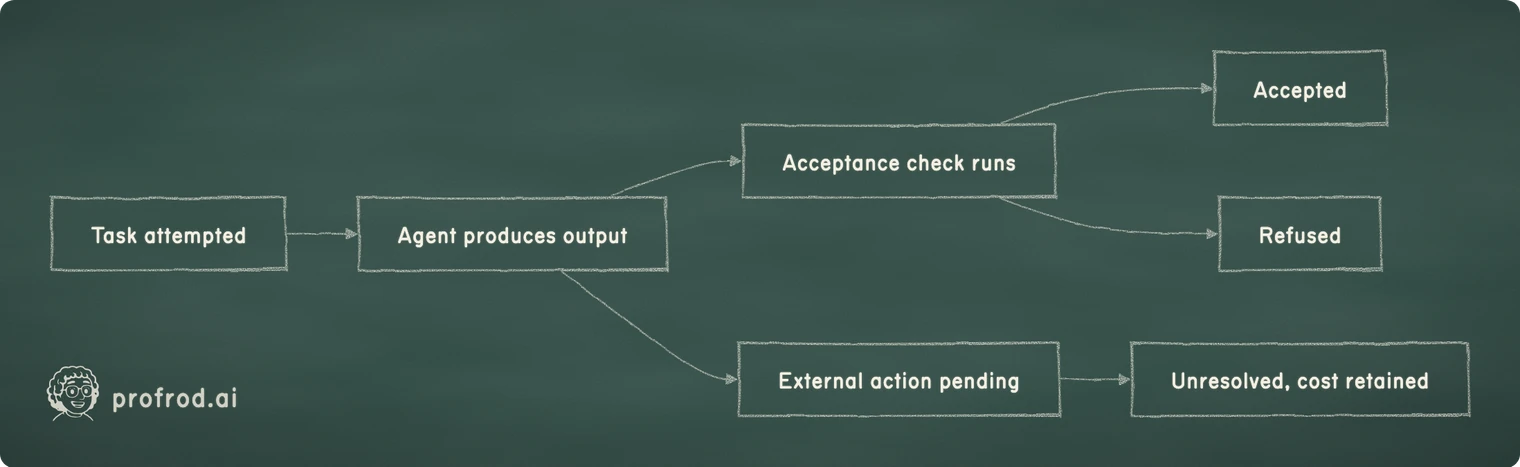
An attempt has more than one exit, and "unresolved" later reconciles into accepted or refused when the external system reports. The cost already spent, in tokens and review minutes, stays attached to the attempt whichever exit it reaches.
Put an error bar on every rate
A rate from a few dozen attempts is an estimate. With acceptance rate p over n attempts, a 95% binomial interval is about p ± 1.96·√(p(1 − p)/n), the interval Chapter 16 of the book derives.
| Family | Rate | n | Half-width | Interval |
|---|---|---|---|---|
| eval-harness fix | 96/120 = 0.800 | 120 | 0.072 | 0.728 to 0.872 |
| data-pipeline change | 118/150 = 0.787 | 150 | 0.066 | 0.721 to 0.852 |
| experiment script | 71/90 = 0.789 | 90 | 0.084 | 0.705 to 0.873 |
| cluster job | 41/60 = 0.683 | 60 | 0.118 | 0.566 to 0.801 |
| all families | 326/420 = 0.776 | 420 | 0.040 | 0.736 to 0.816 |
Scroll horizontally to view columns.
The cluster-job family looks worst, but its interval overlaps every other family's. One month of 60 attempts cannot show it is worse. It can show that it deserves attention and a larger sample. The intervals also assume attempts are independent; tasks from one project or one day are often correlated, which makes the true uncertainty wider.
Compare families before aggregating
Summed, the table gives 420 attempted, 326 accepted, 62 refused and 32 unresolved: a blended rate near 78%. That is fine as a headline and poor for deciding what to fix, because the blend is a weighted average of family rates, with weights set by how many attempts each family received. Change the weights, by adding an easy family or routing hard tasks elsewhere, and the blend moves with no family changing at all. The uplift article shows how far that goes: a pooled number can even reverse the direction every family shows.
Agree on the definitions of accepted, refused and unresolved before the month starts. Every logged task lands in exactly one at the cutoff; unresolved items get reconciled later, not deleted.
Aggregate attempts, outcomes and review minutes within each family and week. A weekly total alone mixes families; a family-by-week table preserves both.
If the model changed mid-month, split each family's counts at the change and compare rate and review minutes per accepted item within the same family, with intervals.
Pick one change to test, such as routing cluster-job tasks to a different model, and write in advance what stops it, such as any job submitted outside the approved queue.
A reconciliation, worked through
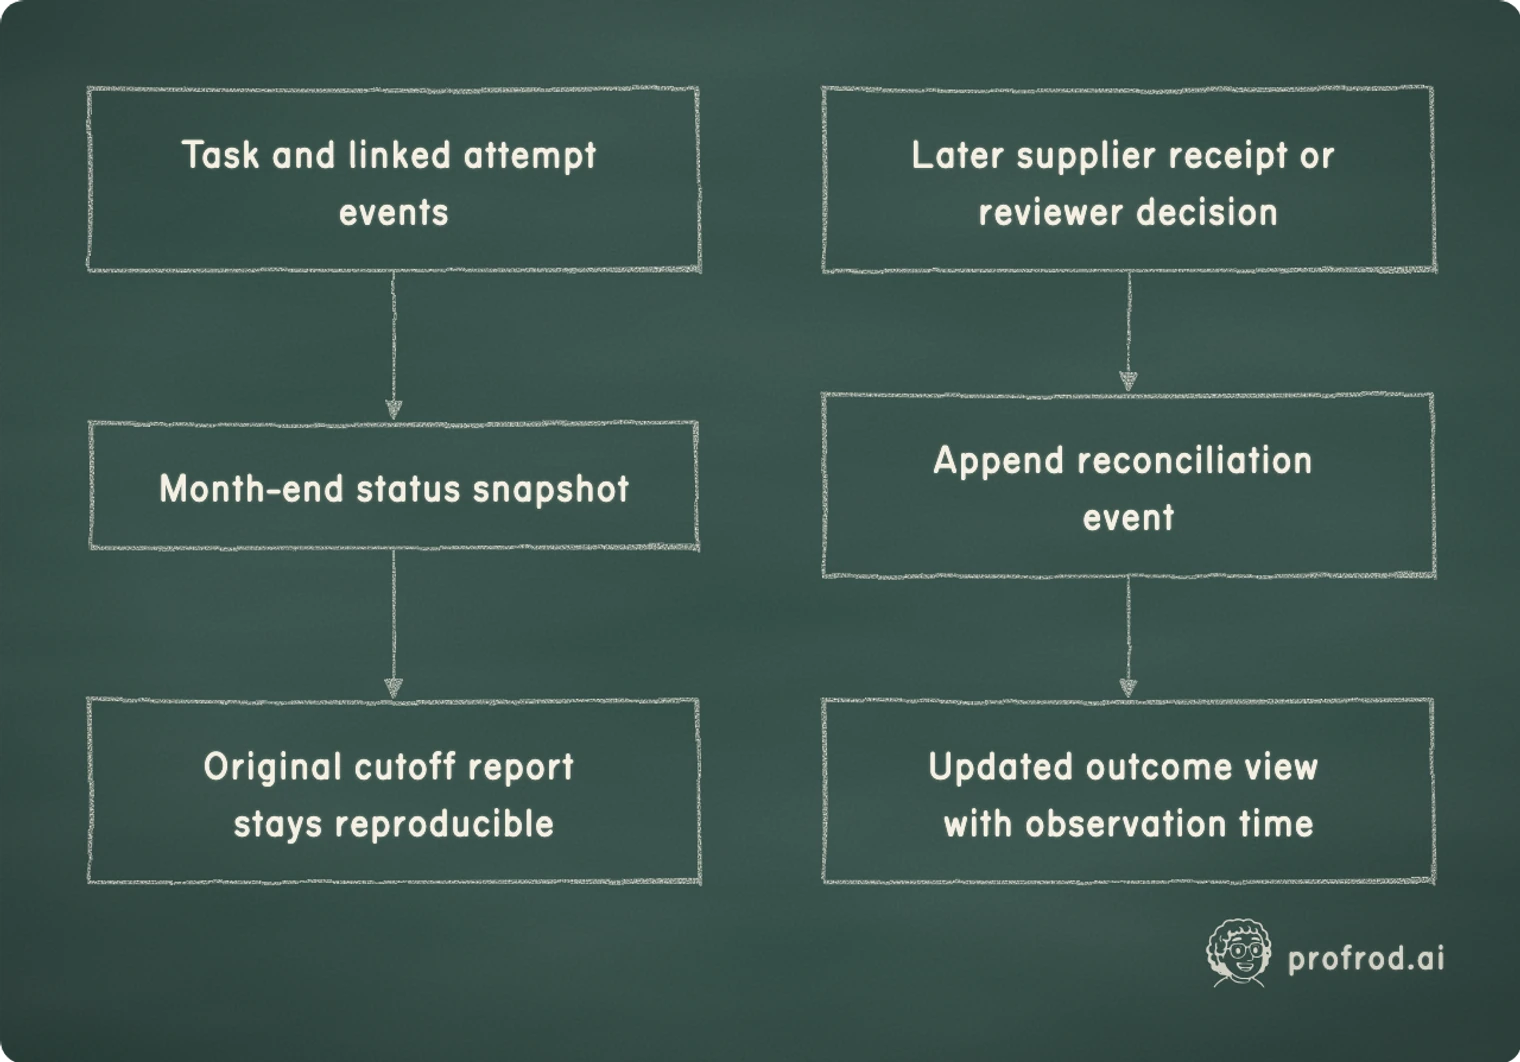
Take one constructed row: family cluster job, attempted 10, accepted 7, refused 2, unresolved 1, review minutes 35. The counts must reconcile: 7 + 2 + 1 = 10. The rate is 7/10 = 70%, not 7/9 = 78% after quietly dropping the unresolved attempt. The 35 review minutes stay in the cost record; that time was spent whatever the outcome.
The next week the job finishes and its log shows the run completed as specified. The ledger becomes accepted 8, refused 2, unresolved 0, still 10 attempted. Append the reconciliation as a new timestamped event rather than overwriting the original record, so anyone auditing later sees both what was known at the cutoff and what was learned afterward.
Check the decision
Calculate the review burden without dropping unresolved work
The table contains 1,510 review minutes for 326 accepted tasks, about 4.63 minutes per accepted task. Keep all review minutes in the numerator, including time spent on refused and unresolved work. By family: 410/96 = 4.27, 560/118 = 4.75, 300/71 = 4.23 and 240/41 = 5.85. A family with zero accepted tasks has an undefined ratio; report its minutes and its zero rather than dividing by zero.
These ratios are accounting summaries, not estimates of time saved. A saving needs a matched baseline and must include setup, maintenance and escalation. Pricing verified output attaches token cost and review time to the decision level they belong to.
Running new routing logic against a mocked scheduler and counting calls in your harness shows your code called the function you expected. It does not show what the real cluster did, whether it deduplicated a retried submission, or whether a job ran twice. Treat a mocked count as evidence about your program only.
What would falsify the improvement claim
State what would prove the opposite before trusting the good news. If, split by family and matched before and after the model change, the acceptance rate for eval-harness fixes or pipeline changes fell while review minutes per accepted item rose, that contradicts improvement on those families, whatever the blend shows. If the unresolved share for cluster jobs grew because the new model submitted jobs the old one would not have, that is a more serious failure than lower accuracy: check whether the submissions broke the declared stop condition rather than averaging them away.
Why this matters in a lab
The review you just did is an evaluation with a moving test set. The same traps appear when a team compares two model checkpoints on an eval whose categories changed, or reports a benchmark score after adding easier items. A candidate who fixes the denominator, stratifies before pooling, attaches intervals and keeps pending results out of the success count is doing evaluation science, whatever the data source.
Every count, rate and minute in this article is a constructed teaching fixture. The method transfers: every attempt reaches an exit, families are compared before they are pooled, unresolved cost stays in the ledger, and the claim is tested against what would falsify it before anyone celebrates.
The chapter runs a full day of the book's agent and reports what passed, what failed and what stayed unknown, with the evidence for each.


