Draft chapter. The textbook guide covers setup and the supplied code. Practice in Exercise Book 4, then check Solutions 4 once you have tried it. Both ninety-minute units run on Google Colab with the standard library only.
An agent that works for hours, and an evaluation sweep that runs overnight, both need state that survives a crash: what was done, what was half done, and a record that can be replayed to check it. Lab teams checkpoint training runs, resume agent jobs and rerun evaluations from exactly this kind of store, and they ask candidates how they would keep it from lying after a failure. This chapter builds one and proves its central property, with Lucy's stock as the running case.
Lucy counts two tubs of vanilla on Monday night. On Tuesday morning the supplier delivers seven more, and the agent from Chapter 3 records the delivery. Then the laptop's battery dies. When Lucy opens the shop again, how many tubs does the agent believe she has?
A Python dictionary has no answer: it vanished with the process. A file has an answer, but not necessarily the right one. If the program wrote "delivery of seven received" and died before it wrote "vanilla is now nine", the file now holds two records that disagree. The next morning the agent will read one of them, and it will be confidently wrong.
This chapter builds the place where Lucy's shop state lives. A change that the program reports as done must survive the process ending. A change that was interrupted must leave no trace. Two facts that must agree, the stock count and the record of how it got there, must never be observed disagreeing. We build that from SQLite, one visible operation at a time, and then we measure what it costs when two parts of the program try to write at once.
Learning objectives
By the end you will be able to:
- Create a file-backed database, write a row, close it, and recover the row from a new connection.
- Explain a table, a primary key, a constraint and a parameterized statement, using Lucy's stock.
- State the shop's invariant precisely, show a program that breaks it, and prove that a transaction around the two writes keeps it.
- Define event append as a function, prove it is idempotent, and refuse an event whose identity is reused with different content.
- Migrate a schema from one version to the next inside one transaction, and refuse a database written by a newer program before changing anything.
- Derive how often a second writer is refused, and how long it waits, when another writer holds the lock, and compare the derivation with a measurement.
You bring Python functions, dictionaries, classes and exceptions, and the loop from Chapters 1–3. No SQL is assumed. Every piece of SQL is explained before it is used.
Keep your implementation in a file
Create book/textbook/learner/profrod_sovereign_agent_ch04_state_store_learner.py in your checkout and build it as you read. The repository includes a completed comparison copy at that path; the Chapter 4 checkpoint loads the learner file and checks it against this chapter's acceptance examples with an independent reader:
uv run python book/textbook/checkpoints/profrod_sovereign_agent_ch04_sqlite_state_checkpoint.pyThe code needs Python 3.12 or newer, which includes the Python 3.12 that Google Colab runs. Nothing here imports the finished project's sovereign_agent.database. You write every line of the store yourself.
A table, a row and a file
A Python dictionary such as {"vanilla": 2} maps a product's identity to its quantity. A table holds the same idea in a file: each row is one product, and each column is one attribute of it. We need two columns: sku, the product's identity, and tubs, how many whole tubs are on the shelf.
import sqlite3
import tempfile
from pathlib import Path

workspace = Path(tempfile.mkdtemp(prefix="ch04-"))
path = workspace / "shop.sqlite3"

writer = sqlite3.connect(path, autocommit=True)
writer.execute("CREATE TABLE stock (sku TEXT PRIMARY KEY, tubs INTEGER NOT NULL CHECK (tubs >= 0))")
print(writer.execute("SELECT sku, tubs FROM stock").fetchall())[]sqlite3.connect opens the file, creating it if needed, and returns a connection: a handle through which the program talks to the database. The connection is not the database. The file is. CREATE TABLE declares the columns. PRIMARY KEY says that no two rows may share a sku. CHECK (tubs >= 0) is a constraint: a rule the database itself enforces, so that no path through the program, correct or not, can store a negative count. An empty table answers an empty list. It does not invent a zero.
autocommit=True needs a word now, because this chapter depends on it. By default, Python's sqlite3 module opens transactions for you behind the scenes, at moments its own rules choose. With autocommit=True (available from Python 3.12) it never does: each statement stands alone unless we open a transaction. That is what lets the rest of this chapter decide exactly which writes belong together.
writer.execute("INSERT INTO stock (sku, tubs) VALUES (?, ?)", ("vanilla", 2))
writer.close()

reader = sqlite3.connect(path, autocommit=True)
print(reader.execute("SELECT sku, tubs FROM stock").fetchall())[('vanilla', 2)]The ? marks are parameters. The values travel to the database separately from the SQL text, so a product called vanilla'); DROP TABLE stock; -- would be stored as a strange product name and never read as an instruction. Never build SQL by pasting values into the string.
Closing and reopening is the first real test of durability in this chapter. The same connection returning a row it just wrote proves very little: it may be reading its own uncommitted work. A separate connection finding the row proves the row reached the file.
for attempt in [("vanilla", 5), ("chocolate", -1)]:
    try:
        reader.execute("INSERT INTO stock (sku, tubs) VALUES (?, ?)", attempt)
    except sqlite3.IntegrityError as error:
        print(f"refused {attempt}: {error}")
print(reader.execute("SELECT sku, tubs FROM stock").fetchall())refused ('vanilla', 5): UNIQUE constraint failed: stock.sku
refused ('chocolate', -1): CHECK constraint failed: tubs >= 0
[('vanilla', 2)]Two writes that must agree
A stock count alone cannot answer Lucy's next question: why is it two? The shop needs a second table, a log of events, each recording one change: which product, by how much, and a stable identity for the change itself. Opening counts, deliveries and sales are all events.
Having two tables creates something to protect. Call the stock table , a map from product to tubs, and the event log , a set of events with product and change . The shop's invariant is
Every count is explained by its events, exactly. If ever fails, one of the two tables is lying, and a program reading the other one will act on a false belief.
A delivery of tubs of with identity is a change made of two writes:
If holds before, it holds after both writes: the left side of grows by for , and so does the right. But after alone, the right side has grown and the left has not. The state breaks by exactly . A program that can stop between and can leave the shop in a state that should never exist.
reader.execute(
    "CREATE TABLE events (event_id TEXT PRIMARY KEY, sku TEXT NOT NULL, delta INTEGER NOT NULL)"
)
reader.execute("INSERT INTO events VALUES ('e1', 'vanilla', 2)")


def deliver_without_transaction(db, event_id, sku, delta, fail=False):
    db.execute("INSERT INTO events VALUES (?, ?, ?)", (event_id, sku, delta))
    if fail:
        raise RuntimeError("stopped between the two writes")
    db.execute("UPDATE stock SET tubs = tubs + ? WHERE sku = ?", (delta, sku))


def invariant(db):
    stock = dict(db.execute("SELECT sku, tubs FROM stock"))
    sums = dict(db.execute("SELECT sku, SUM(delta) FROM events GROUP BY sku"))
    return stock == sums, stock, sums


try:
    deliver_without_transaction(reader, "e2", "vanilla", 7, fail=True)
except RuntimeError as error:
    print(error)
print(invariant(reader))stopped between the two writes
(False, {'vanilla': 2}, {'vanilla': 9})The event says nine tubs; the shelf says two. Because the connection commits each statement on its own, the first write is already in the file. The raised exception did not undo it, and nothing would.
Own the transaction boundary
A transaction groups writes so that the file shows either all of them or none of them. BEGIN IMMEDIATE starts one and takes the database's write lock at once. COMMIT publishes the group. ROLLBACK discards it. Until COMMIT, no other connection sees any of the group's writes.
This gives the property we need, called atomicity. Every state another connection can observe is either the state before a committed transaction or the state after it. Now prove the invariant survives. Suppose holds in the initial state, and every transaction, run in full, maps a state satisfying to one satisfying ; our delivery does, as shown above. Every observable state is reached from the initial one by a sequence of complete transactions, because partial ones are never visible. So by induction on the number of committed transactions, holds in every observable state. The proof needs both halves: each change must preserve when complete, and nothing incomplete may ever be observed. The transaction supplies the second half; your code must supply the first.
reader.execute("DELETE FROM events WHERE event_id = 'e2'")  # clean up the broken state first


def deliver(db, event_id, sku, delta, fail=False):
    db.execute("BEGIN IMMEDIATE")
    try:
        db.execute("INSERT INTO events VALUES (?, ?, ?)", (event_id, sku, delta))
        if fail:
            raise RuntimeError("stopped between the two writes")
        db.execute("UPDATE stock SET tubs = tubs + ? WHERE sku = ?", (delta, sku))
    except BaseException:
        db.execute("ROLLBACK")
        raise
    db.execute("COMMIT")


try:
    deliver(reader, "e2", "vanilla", 7, fail=True)
except RuntimeError as error:
    print(error)
print(invariant(reader))
deliver(reader, "e2", "vanilla", 7)
print(invariant(reader))stopped between the two writes
(True, {'vanilla': 2}, {'vanilla': 2})
(True, {'vanilla': 9}, {'vanilla': 9})The failed delivery left nothing; the complete one left both writes. Notice except BaseException, not except Exception: a KeyboardInterrupt between the writes must also roll back. Notice too that the handler re-raises. Rolling back is not recovery; the caller still needs to know the delivery did not happen.
Writing BEGIN, try, ROLLBACK and COMMIT around every change would be tedious, and one forgotten ROLLBACK would be a bug. Python's with statement exists for exactly this shape: set something up, run a block, and tear it down whether the block succeeds or raises. contextlib.contextmanager turns a generator into something with can use. Code before yield runs on entry, and the yield hands the block its connection. If the block raises, the exception reappears at the yield, where our handler catches it.
from contextlib import contextmanager


@contextmanager
def transaction(db):
    db.execute("BEGIN IMMEDIATE")
    try:
        yield db
    except BaseException:
        db.execute("ROLLBACK")
        raise
    else:
        db.execute("COMMIT")


with transaction(reader) as db:
    db.execute("INSERT INTO events VALUES ('e3', 'vanilla', -1)")
    db.execute("UPDATE stock SET tubs = tubs - 1 WHERE sku = 'vanilla'")
print(invariant(reader))
reader.close()(True, {'vanilla': 8}, {'vanilla': 8})The finished store below adds two more things to this manager. It refuses a second BEGIN while one is open, because nested transactions have rules we have not taught. And it treats a failed COMMIT as a failure: if the commit raises, it rolls back what is still pending and re-raises, so a delivery can never be reported as done when the file does not hold it.
Events never change meaning
An event's identity is a promise: e2 means "seven tubs of vanilla delivered", forever. Two things can threaten that promise.
The first is replay. The agent sends a write, the process dies before it learns whether the write committed, and on restart it sends the write again. The second is reuse: a bug, or another program, sends e2 again with different content.
Treat the log as a set of events, and let be the set of identities in it. Define appending an event with identity as
is idempotent: . If , the append failed and the caller has nothing to repeat. Otherwise after the first append, so the second append takes the first case and returns its input unchanged. So the agent may retry a write whose outcome it does not know, as many times as it likes, and the log ends the same as if the write had happened once. What made the retry safe is the stable identity the caller chose before the first attempt. A timestamp or a random identity generated per attempt would turn each retry into a new event.
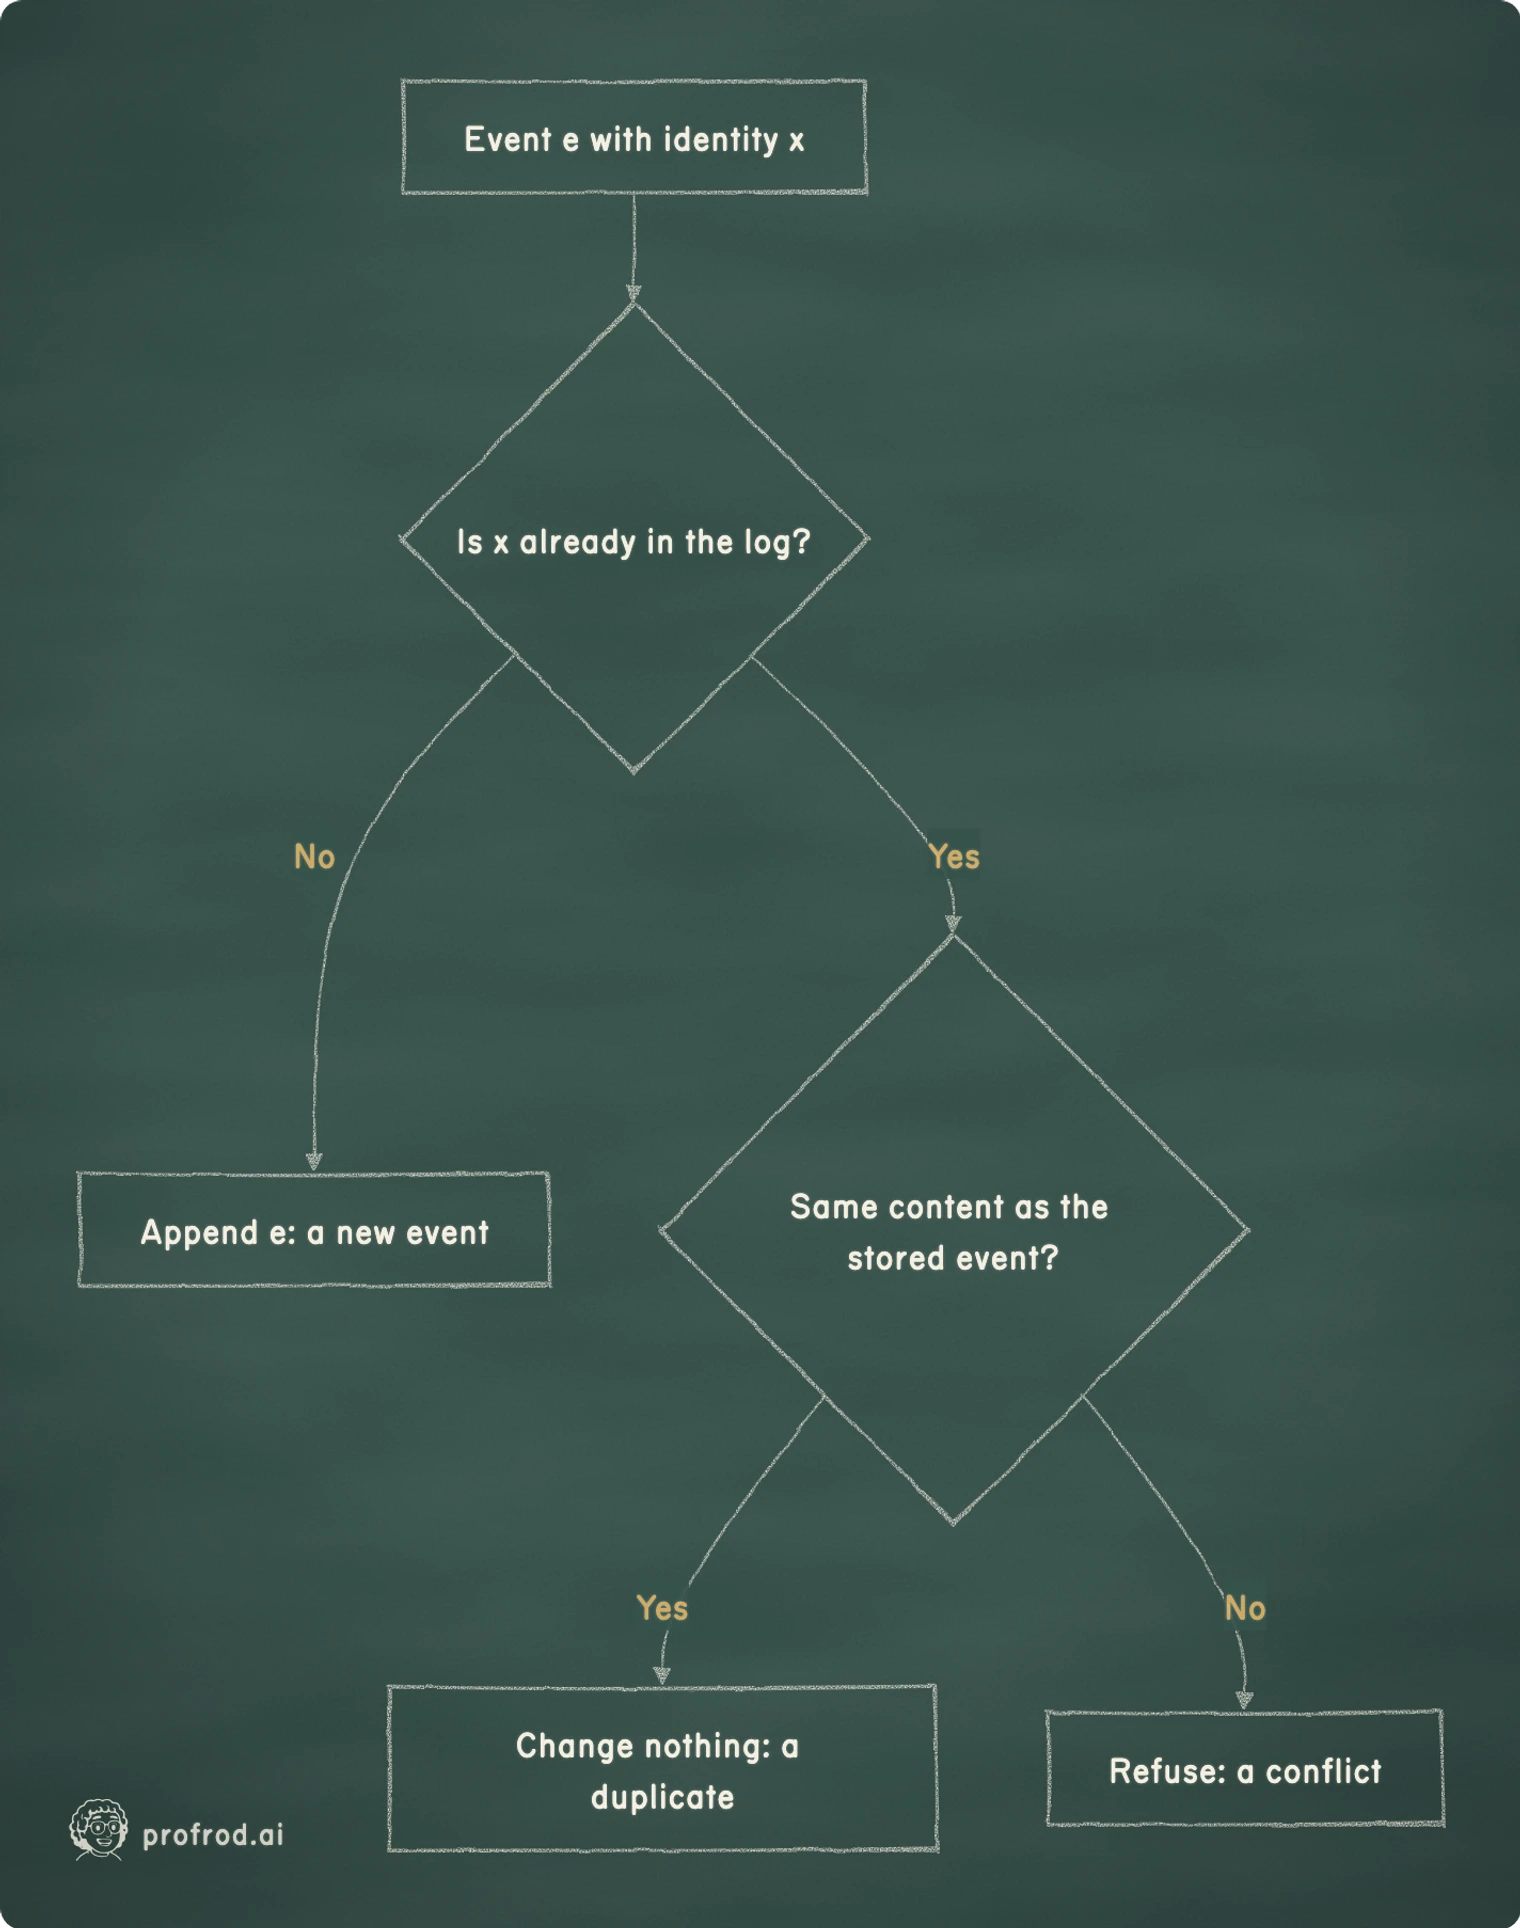
flowchart TD
    E[Event e with identity x] --> Q{Is x already in the log?}
    Q -->|No| N[Append e: a new event]
    Q -->|Yes| S{Same content as the stored event?}
    S -->|Yes| D[Change nothing: a duplicate]
    S -->|No| C[Refuse: a conflict]
The same definition says what the database must refuse. INSERT OR REPLACE, which SQLite offers, would implement : the old meaning of silently disappears. That is exactly the third case, and the store must raise instead. We compare events by a canonical text form of their content, with keys sorted and no stray spaces, so two equal events are equal byte for byte. And we let the database itself refuse UPDATE and DELETE on the event table, with triggers, so no later chapter can change history by accident.
Versions form a line
The schema will grow. This chapter adds a reason to each event. Chapter 5 adds memory tables, and Chapter 8 adds durable work. A database file written today will be opened by the program of next month, and occasionally a file written by next month's program will be opened by today's.
Number the schema versions ; version 0 is an empty file. A migration turns a database at version into one at version . Upgrading from version to version applies the migrations in order, . There is exactly one path, because the versions form a line and each step has one migration. We store the current version in the database, in a meta table.
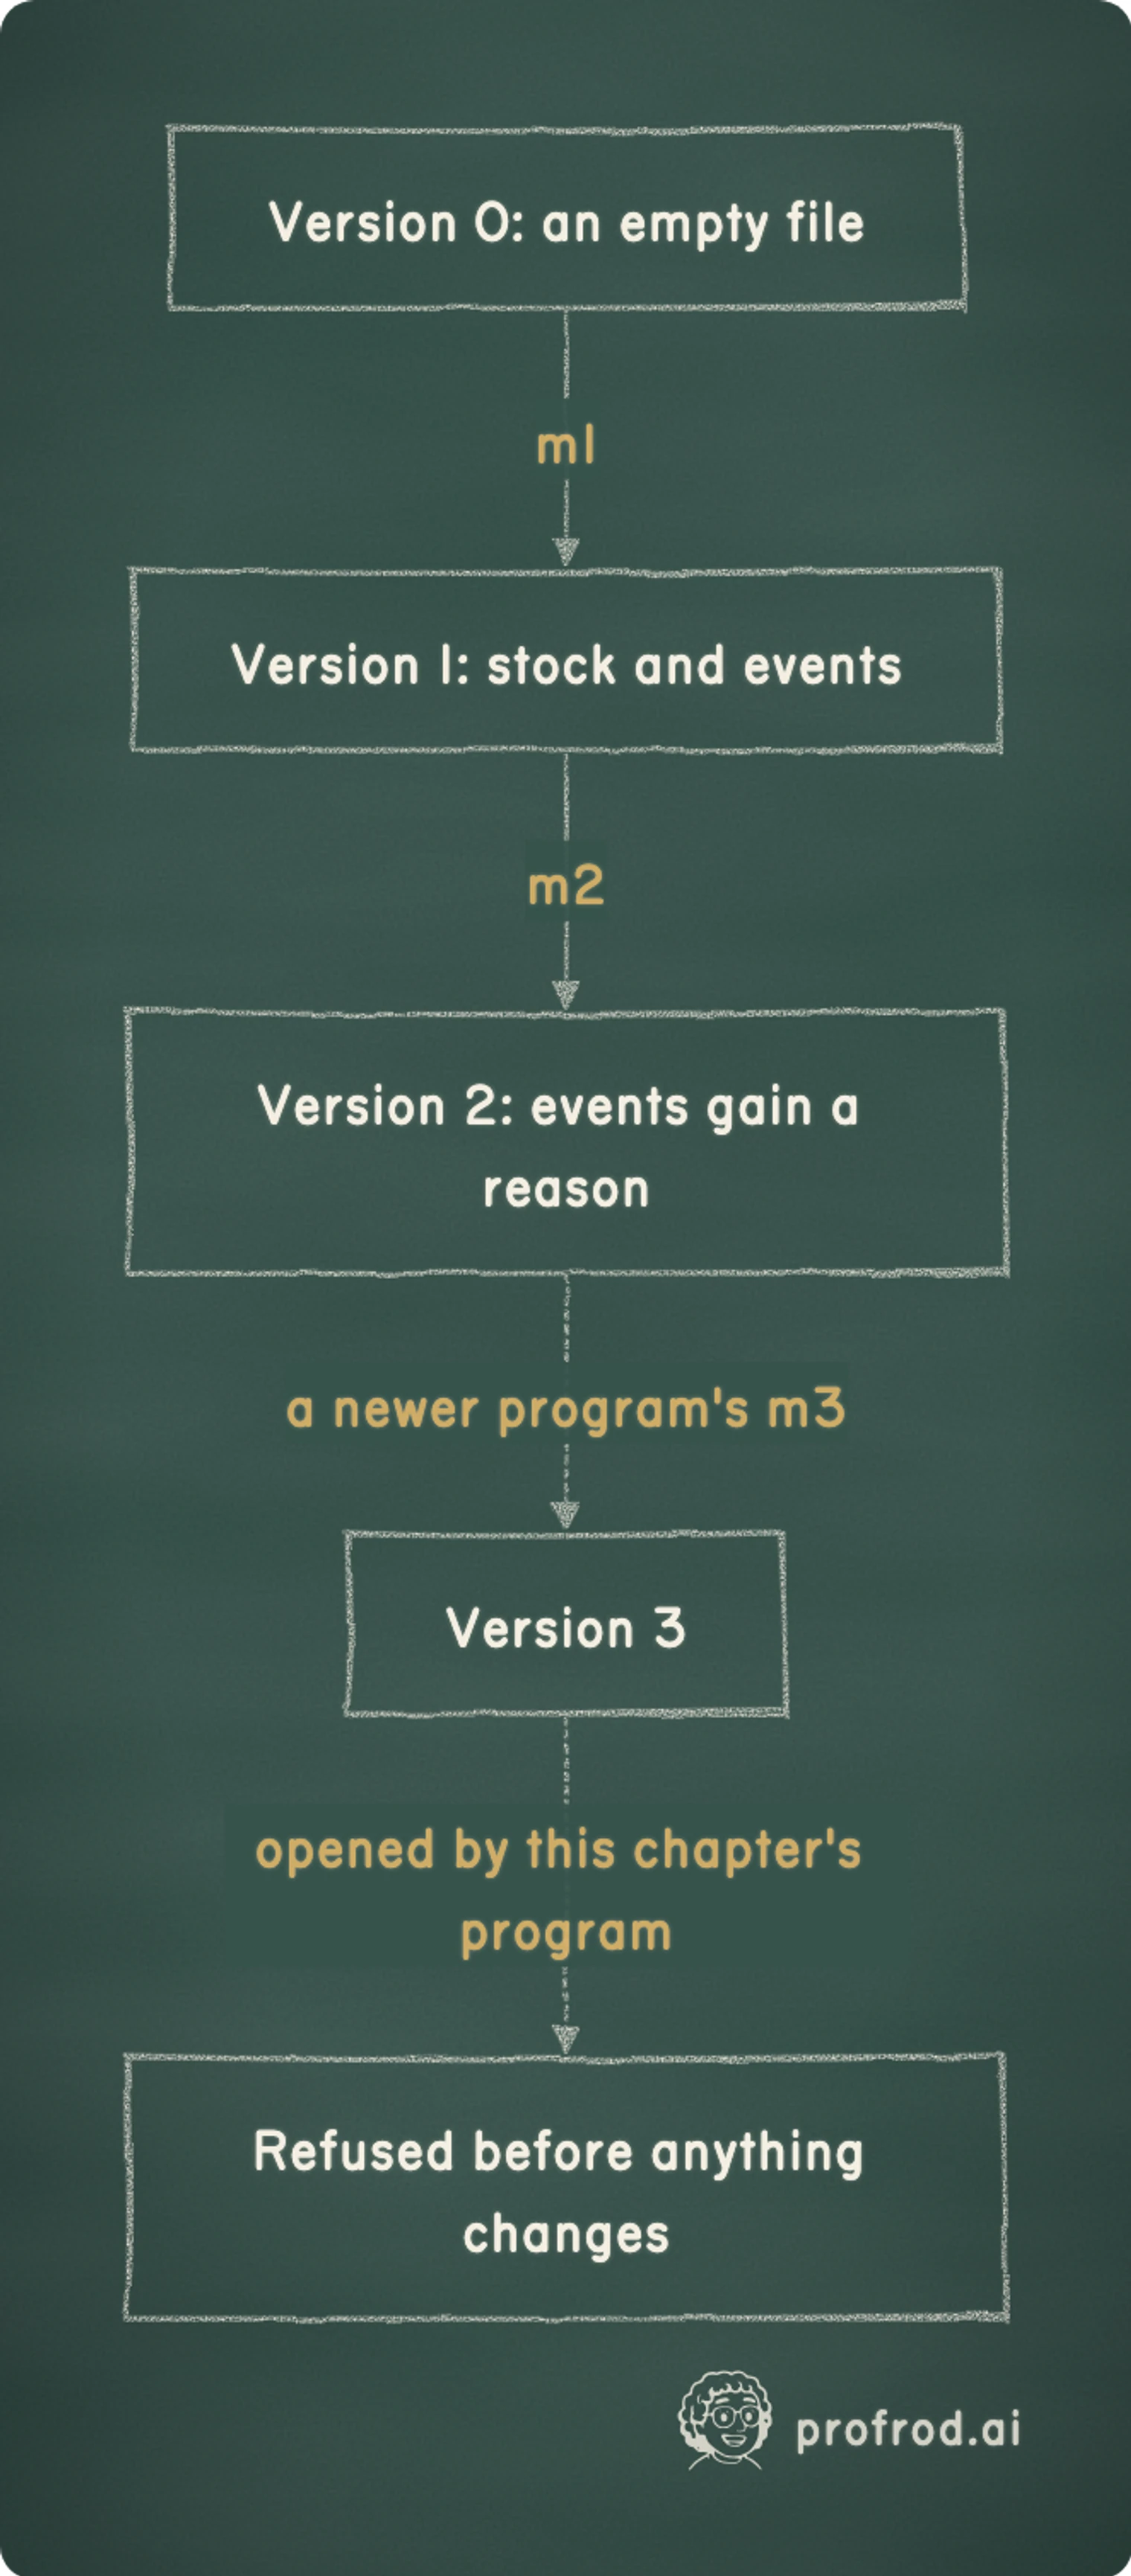
flowchart LR
    V0[Version 0: an empty file] -->|m1| V1[Version 1: stock and events]
    V1 -->|m2| V2[Version 2: events gain a reason]
    V2 -.->|a newer program's m3| V3[Version 3]
    V3 -.->|opened by this chapter's program| R[Refused before anything changes]
One more design choice matters before the rules. The schema has several owners. This chapter owns the stock tables; Chapter 5 will own memory's tables, and Chapter 8 durable work's. If they all shared one line of versions, the order in which chapters happen to be written would decide each other's numbers, and two chapters would eventually claim the same version for different tables. So each owner keeps its own line under its own name: this chapter's version lives at stock.version, and a later chapter calls the same migrate method with its own name and its own migrations.
Two rules make migration safe.
Each migration commits together with its version number. If and the write "version is now " share one transaction, then after a crash the file is at version with the old tables or at version with the new ones. It is never in between. Running initialize again after the crash therefore picks up exactly where it stopped. Running it on an up-to-date file applies nothing, so initialization, like append, is idempotent.
A newer version is refused before anything changes. Today's program knows migrations up to . It cannot know what a file at version means: a column might hold something new, or a table might have moved. Writing to that file would destroy information the newer program depends on. So initialize reads the version first, and if it is above it raises inside the transaction, which rolls back to the unchanged file.
Assemble the store
Each responsibility has now appeared as a small, visible operation. The store puts them together behind two methods: immediate() for a group of writes, and apply() for the one change the shop makes, an event and its stock update.
import json
from collections.abc import Callable, Iterator
from dataclasses import dataclass


class StoreError(Exception):
    """A state change the store refused. The database is unchanged."""


class EventConflictError(StoreError):
    """An event identity that already exists with different content."""


class UnsupportedSchemaError(StoreError):
    """A database written by a newer program than this one."""


class NestedTransactionError(StoreError):
    """A transaction opened while another is still open on the same store."""


@dataclass(frozen=True)
class StockEvent:
    event_id: str
    sku: str
    delta: int
    reason: str

    def payload(self) -> str:
        return json.dumps(
            {"sku": self.sku, "delta": self.delta, "reason": self.reason},
            sort_keys=True,
            separators=(",", ":"),
        )


MIGRATIONS: dict[int, tuple[str, ...]] = {
    1: (
        "CREATE TABLE stock (sku TEXT PRIMARY KEY, tubs INTEGER NOT NULL CHECK (tubs >= 0))",
        "CREATE TABLE events (event_id TEXT PRIMARY KEY, sku TEXT NOT NULL,"
        " delta INTEGER NOT NULL, payload TEXT NOT NULL)",
        "CREATE TRIGGER events_no_update BEFORE UPDATE ON events"
        " BEGIN SELECT RAISE(ABORT, 'events are append-only'); END",
        "CREATE TRIGGER events_no_delete BEFORE DELETE ON events"
        " BEGIN SELECT RAISE(ABORT, 'events are append-only'); END",
    ),
    2: ("ALTER TABLE events ADD COLUMN reason TEXT NOT NULL DEFAULT 'unrecorded'",),
}
SCHEMA_VERSION = max(MIGRATIONS)
print(SCHEMA_VERSION, StockEvent("e1", "vanilla", 2, "opening count").payload())2 {"delta":2,"reason":"opening count","sku":"vanilla"}class StateStore:
def __init__(self, path, *, busy_timeout_s: float = 1.0) -> None:
self.path = Path(path)
self.connection = sqlite3.connect(self.path, autocommit=True, timeout=busy_timeout_s)
self.connection.execute("PRAGMA journal_mode = WAL")
self.connection.execute("PRAGMA synchronous = FULL")
self._open = False
def close(self) -> None:
self.connection.close()
@contextmanager
def immediate(self) -> Iterator[sqlite3.Connection]:
if self._open:
raise NestedTransactionError("a transaction is already open on this store")
self.connection.execute("BEGIN IMMEDIATE")
self._open = True
try:
yield self.connection
except BaseException:
self.connection.execute("ROLLBACK")
raise
else:
try:
self.connection.execute("COMMIT")
except BaseException:
if self.connection.in_transaction:
self.connection.execute("ROLLBACK")
raise
finally:
self._open = False
def schema_version(self, owner: str = "stock") -> int:
exists = self.connection.execute(
"SELECT 1 FROM sqlite_schema WHERE type = 'table' AND name = 'meta'"
).fetchone()
if not exists:
return 0
row = self.connection.execute(
"SELECT value FROM meta WHERE key = ?", (f"{owner}.version",)
).fetchone()
return int(row[0]) if row else 0
def migrate(self, owner: str, migrations: dict[int, tuple[str, ...]]) -> tuple[int, int]:
latest = max(migrations)
with self.immediate() as db:
before = self.schema_version(owner)
if before > latest:
raise UnsupportedSchemaError(
f"{owner} tables are version {before}; this program supports up to {latest}"
)
db.execute("CREATE TABLE IF NOT EXISTS meta (key TEXT PRIMARY KEY, value INTEGER)")
for version in range(before + 1, latest + 1):
for statement in migrations[version]:
db.execute(statement)
db.execute(
"INSERT INTO meta (key, value) VALUES (?, ?)"
" ON CONFLICT (key) DO UPDATE SET value = excluded.value",
(f"{owner}.version", latest),
)
return before, latest
def initialize(self) -> tuple[int, int]:
return self.migrate("stock", MIGRATIONS)
def apply(self, event: StockEvent, *, between: Callable[[], None] | None = None) -> str:
payload = event.payload()
with self.immediate() as db:
row = db.execute(
"SELECT payload FROM events WHERE event_id = ?", (event.event_id,)
).fetchone()
if row is not None:
if row[0] == payload:
return "duplicate"
raise EventConflictError(
f"event {event.event_id} already exists with other content"
)
db.execute(
"INSERT INTO events (event_id, sku, delta, payload, reason) VALUES (?, ?, ?, ?, ?)",
(event.event_id, event.sku, event.delta, payload, event.reason),
)
if between is not None:
between()
# Update the product's row; only a product seen for the first time gets a new row.
# (An INSERT ... ON CONFLICT upsert would check tubs >= 0 against the inserted delta,
# so an ordinary sale from a positive count would be refused.)
updated = db.execute(
"UPDATE stock SET tubs = tubs + ? WHERE sku = ?", (event.delta, event.sku)
).rowcount
if updated == 0:
db.execute("INSERT INTO stock (sku, tubs) VALUES (?, ?)", (event.sku, event.delta))
return "applied"
def stock(self) -> dict[str, int]:
return dict(self.connection.execute("SELECT sku, tubs FROM stock ORDER BY sku"))Three lines in __init__ deserve their own sentence. timeout=busy_timeout_s sets how long this connection waits for another writer's lock before giving up; the last section measures what that choice costs. journal_mode = WAL writes changes to a separate write-ahead log first and folds them into the main file later, which lets readers keep reading while one writer writes. synchronous = FULL makes COMMIT wait until the log has been flushed to storage; the section on durability explains what that does and does not buy.
The store also needs an honest witness. observe opens its own connection and reads the file directly, never through the store's methods. A store that is wrong about its own state therefore cannot also convince the check that it is right.
def observe(path) -> dict[str, object]:
    reader = sqlite3.connect(path, autocommit=True)
    try:
        stock = dict(reader.execute("SELECT sku, tubs FROM stock ORDER BY sku"))
        events = [row[0] for row in reader.execute("SELECT event_id FROM events ORDER BY rowid")]
        sums = dict(reader.execute("SELECT sku, SUM(delta) FROM events GROUP BY sku ORDER BY sku"))
        version = reader.execute("SELECT value FROM meta WHERE key = 'stock.version'").fetchone()[0]
    finally:
        reader.close()
    return {"stock": stock, "events": events, "sums": sums, "version": version}


def interrupt():
    raise RuntimeError("stopped between the two writes")


store = StateStore(workspace / "lucy.sqlite3")
print(store.initialize())
print(store.apply(StockEvent("e1", "vanilla", 2, "opening count")))
print(store.apply(StockEvent("e1", "vanilla", 2, "opening count")))
for attempt, between in [
    (StockEvent("e1", "vanilla", 5, "opening count"), None),
    (StockEvent("e2", "vanilla", 7, "delivery"), interrupt),
    (StockEvent("e3", "vanilla", -3, "sale"), None),
]:
    try:
        store.apply(attempt, between=between)
    except (StoreError, RuntimeError, sqlite3.IntegrityError) as error:
        print(f"{attempt.event_id}: {type(error).__name__}: {error}")
print(observe(store.path))(0, 2)
applied
duplicate
e1: EventConflictError: event e1 already exists with other content
e2: RuntimeError: stopped between the two writes
e3: IntegrityError: CHECK constraint failed: tubs >= 0
{'stock': {'vanilla': 2}, 'events': ['e1'], 'sums': {'vanilla': 2}, 'version': 2}Read the last line against the invariant. After a duplicate, a conflict, a failure between the writes and a refused negative count, the shelf and the log still agree. The refused sale is worth a second look. The CHECK constraint on the stock table rejected the stock write, and because the event write shared its transaction, the event disappeared with it. The constraint on one table protected the other.
legacy_path = workspace / "last-year.sqlite3"
legacy = sqlite3.connect(legacy_path, autocommit=True)
for statement in MIGRATIONS[1]:
    legacy.execute(statement)
legacy.execute("CREATE TABLE meta (key TEXT PRIMARY KEY, value INTEGER)")
legacy.execute("INSERT INTO meta VALUES ('stock.version', 1)")
legacy.execute("INSERT INTO events VALUES ('old-1', 'strawberry', 4, '{}')")
legacy.execute("INSERT INTO stock VALUES ('strawberry', 4)")
legacy.close()

upgraded = StateStore(legacy_path)
print(upgraded.initialize())
print(upgraded.connection.execute("SELECT event_id, reason FROM events").fetchall())
upgraded.connection.execute("UPDATE meta SET value = 3 WHERE key = 'stock.version'")
try:
    upgraded.initialize()
except UnsupportedSchemaError as error:
    print(error)
print(observe(legacy_path)["stock"])
upgraded.close()
store.close()(1, 2)
[('old-1', 'unrecorded')]
stock tables are version 3; this program supports up to 2
{'strawberry': 4}The version-1 file gained its reason column, with the default value for last year's event, and its stock is untouched. When the marker claims a future version 3, initialize refuses before running any migration.
Two writers, one lock
SQLite allows many readers but only one writer at a time. BEGIN IMMEDIATE takes the write lock; COMMIT or ROLLBACK releases it. If a second connection asks for the lock while it is held, the answer depends on its busy timeout: with a timeout of zero it is refused at once with database is locked; with a positive timeout it waits, up to that long, for the lock to free.
In Lucy's shop this happens when the agent's worker records a delivery at the same moment Lucy's till records a sale. Let us derive what to expect before measuring.
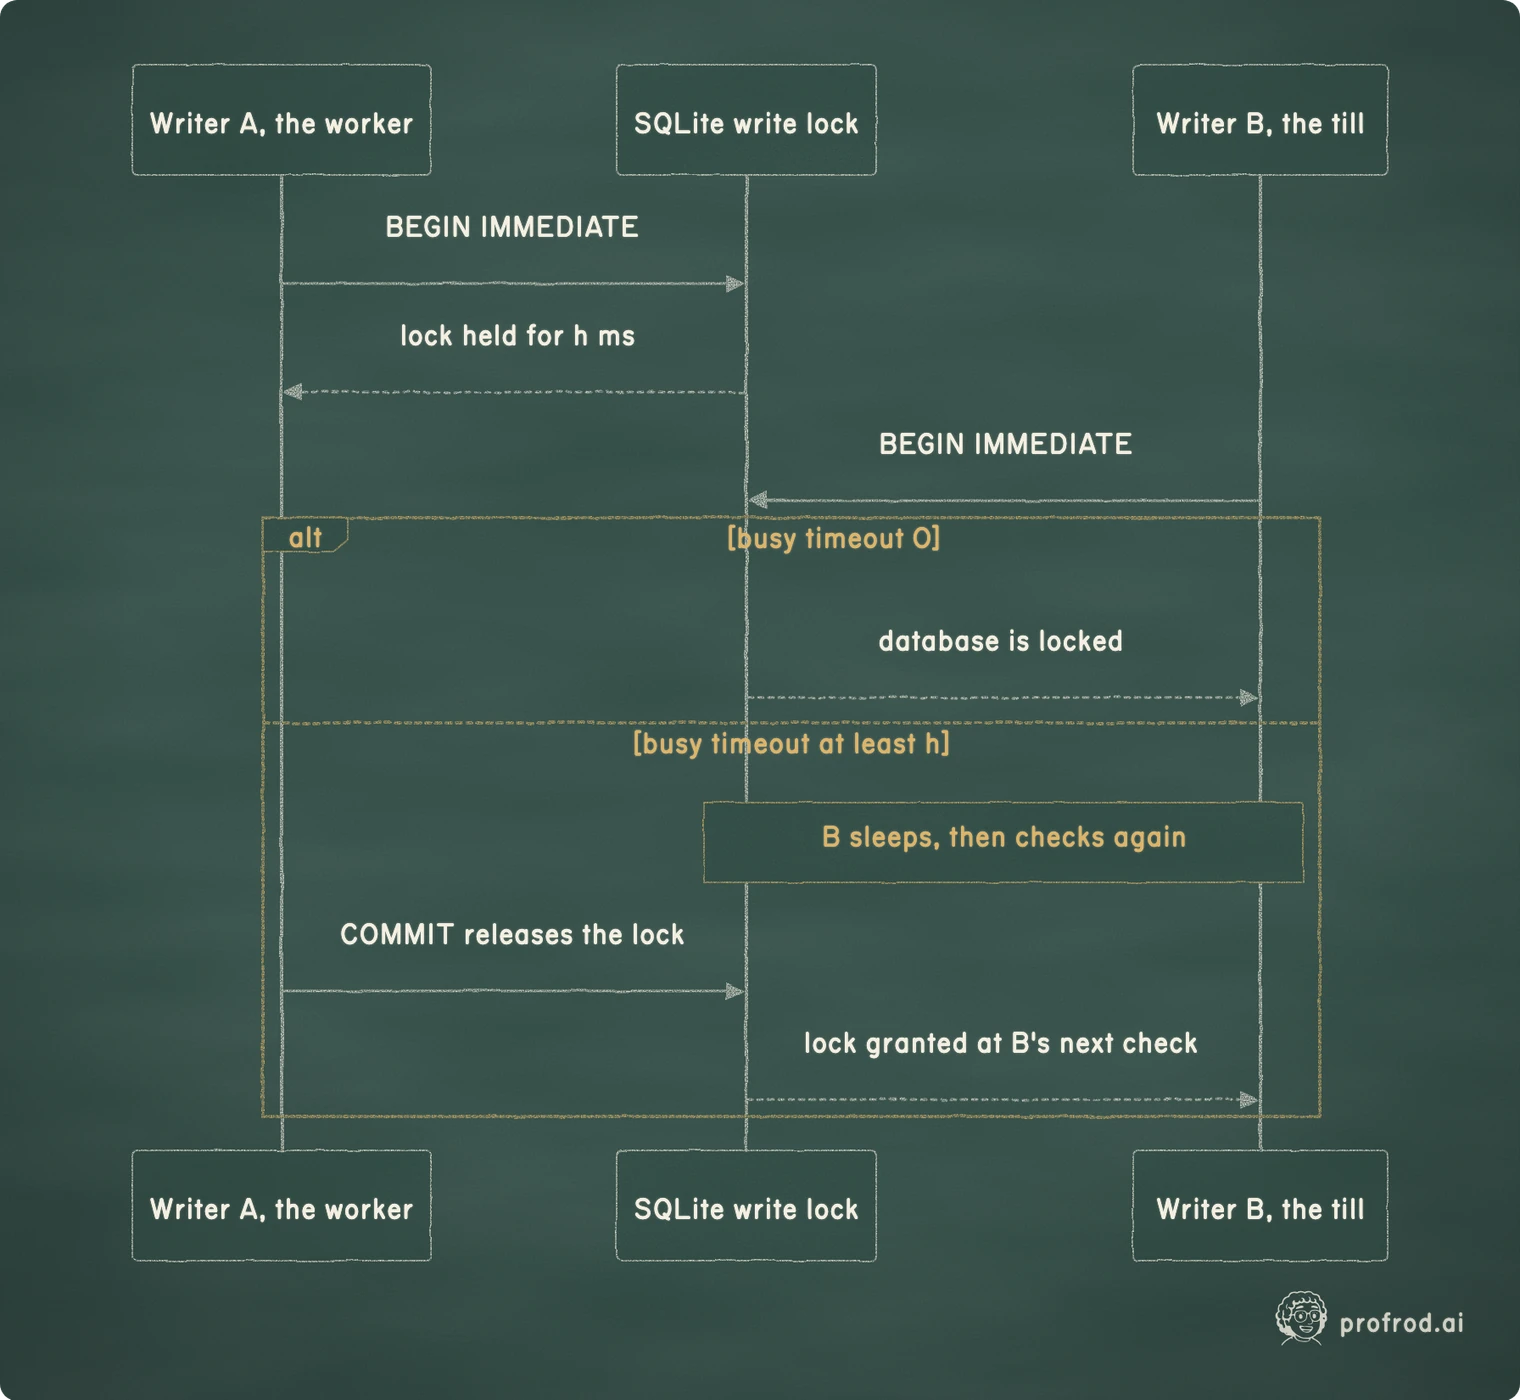
sequenceDiagram
    participant A as Writer A, the worker
    participant L as SQLite write lock
    participant B as Writer B, the till
    A->>L: BEGIN IMMEDIATE
    L-->>A: lock held for h ms
    B->>L: BEGIN IMMEDIATE
    alt busy timeout 0
        L-->>B: database is locked
    else busy timeout at least h
        Note over B,L: B sleeps, then checks again
        A->>L: COMMIT releases the lock
        L-->>B: lock granted at B's next check
    end
Derive the refusal rate and the wait
The model. Writer A takes the lock for milliseconds in every period of milliseconds. Writer B tries to write at a moment that is uniform over the period, independent of A's schedule.
How often B is refused with timeout zero. B is refused exactly when falls inside one of A's hold intervals. That is a set of length inside a period of length , so
With A holding the lock for 30 ms in every 100 ms, three writes in ten are refused.
How long B waits with timeout at least . B is never refused, because the longest possible wait is . When B arrives inside a hold, which happens with probability , the time left until A releases is uniform on , with mean . When B arrives outside a hold, it waits nothing. So
The wait grows with the square of the hold time. Halving how long each transaction holds the lock cuts the average wait of everyone else by four. This is why the store keeps its transactions short and never waits on a model, a network call or a person while holding the lock.
A second model, closer to SQLite
The derivation assumes B notices the free lock the instant A releases it. SQLite's default busy handler does not work that way: it sleeps and checks again, with delays of 1, 2, 5, 10, 15, 20, 25, 25, 25, 50, 50 and then 100 ms. So B's checks happen at cumulative times , and when the lock frees at time after B arrived, B notices at the first check . With uniform on ,
For and , the checks that matter are at 1, 3, 8, 18 and 33 ms. The wait is ms, against ms for the instant-wake model.
Run the contention experiment
The chapter's experiment runs A in a separate process, fires 300 writes from B at uniformly random moments for each setting, and records a receipt:
uv run python book/textbook/experiments/profrod_sovereign_agent_textbook_ch04_state_v1.py --out ch04-state-receipt.jsonOne run, recorded on 2026-09-29 on macOS 26.6.2 (arm64) with Python 3.14.3 and SQLite 3.50.4, gave the table below. The course keeps its receipt as docs/evidence/book-ch04/ch04-state-receipt-v1.json, and the checkpoint recomputes every rate and interval in it.
| Timeout | Refused (95% interval) | Model | Mean wait | Instant-wake model | Stepped model | |
|---|---|---|---|---|---|---|
| 10 ms | 0 | 33/300 = 0.110 (0.079–0.150) | 0.100 | n/a | n/a | n/a |
| 30 ms | 0 | 84/300 = 0.280 (0.232–0.333) | 0.300 | n/a | n/a | n/a |
| 50 ms | 0 | 154/300 = 0.513 (0.457–0.569) | 0.500 | n/a | n/a | n/a |
| 10 ms | 1 s | 0/300 (0.000–0.013) | 0 | 1.63 ms | 0.50 ms | 0.83 ms |
| 30 ms | 1 s | 0/300 (0.000–0.013) | 0 | 8.92 ms | 4.50 ms | 6.23 ms |
| 50 ms | 1 s | 0/300 (0.000–0.013) | 0 | 21.72 ms | 12.50 ms | 16.23 ms |
The refusal rate matches : every prediction lies inside its interval. A timeout at least as long as the hold removes refusals entirely. The waits tell a more interesting story. The stepped model is much closer than the instant-wake model, but the measured waits are still 0.8 to 5.5 ms longer, and the gap grows with the hold. The model has left out a cost. With synchronous = FULL, A keeps the lock through its COMMIT, and that commit waits for the storage to confirm the write, so the real hold is plus the commit's flush. That is a hypothesis, not a result. The exercises ask you to test it. Your machine will give different numbers; record them with the receipt, and read the refusal rate against before reading anything else.
What to do with a refusal. The store's answer is a bounded busy timeout, chosen from the expected hold time, and nothing more. When a write is still refused after the timeout, the store raises. It does not quietly retry the whole business operation, because a retry at this level cannot know whether the operation's other effects, such as a supplier order, already happened. Deciding whether to retry belongs to the caller, who can use the event identity to make the retry idempotent.
What durable means here
"Committed" should mean "still there after the program is gone". The experiment tests that claim with a real process death. A child process records e2 and calls os._exit between the event write and the stock write: no exception handler runs, no finally block, nothing. An independent reader then opens the file:
| Where the child died | Stock | Events | Invariant |
|---|---|---|---|
Inside StateStore.apply (one transaction) | vanilla 2 | e1 | holds |
| Between two separately committed writes | vanilla 2 | e1, e2 | broken |
The transaction's protection does not depend on Python cleaning up. The uncommitted group was only ever in the write-ahead log, and a later reader ignores log frames that belong to no committed transaction.
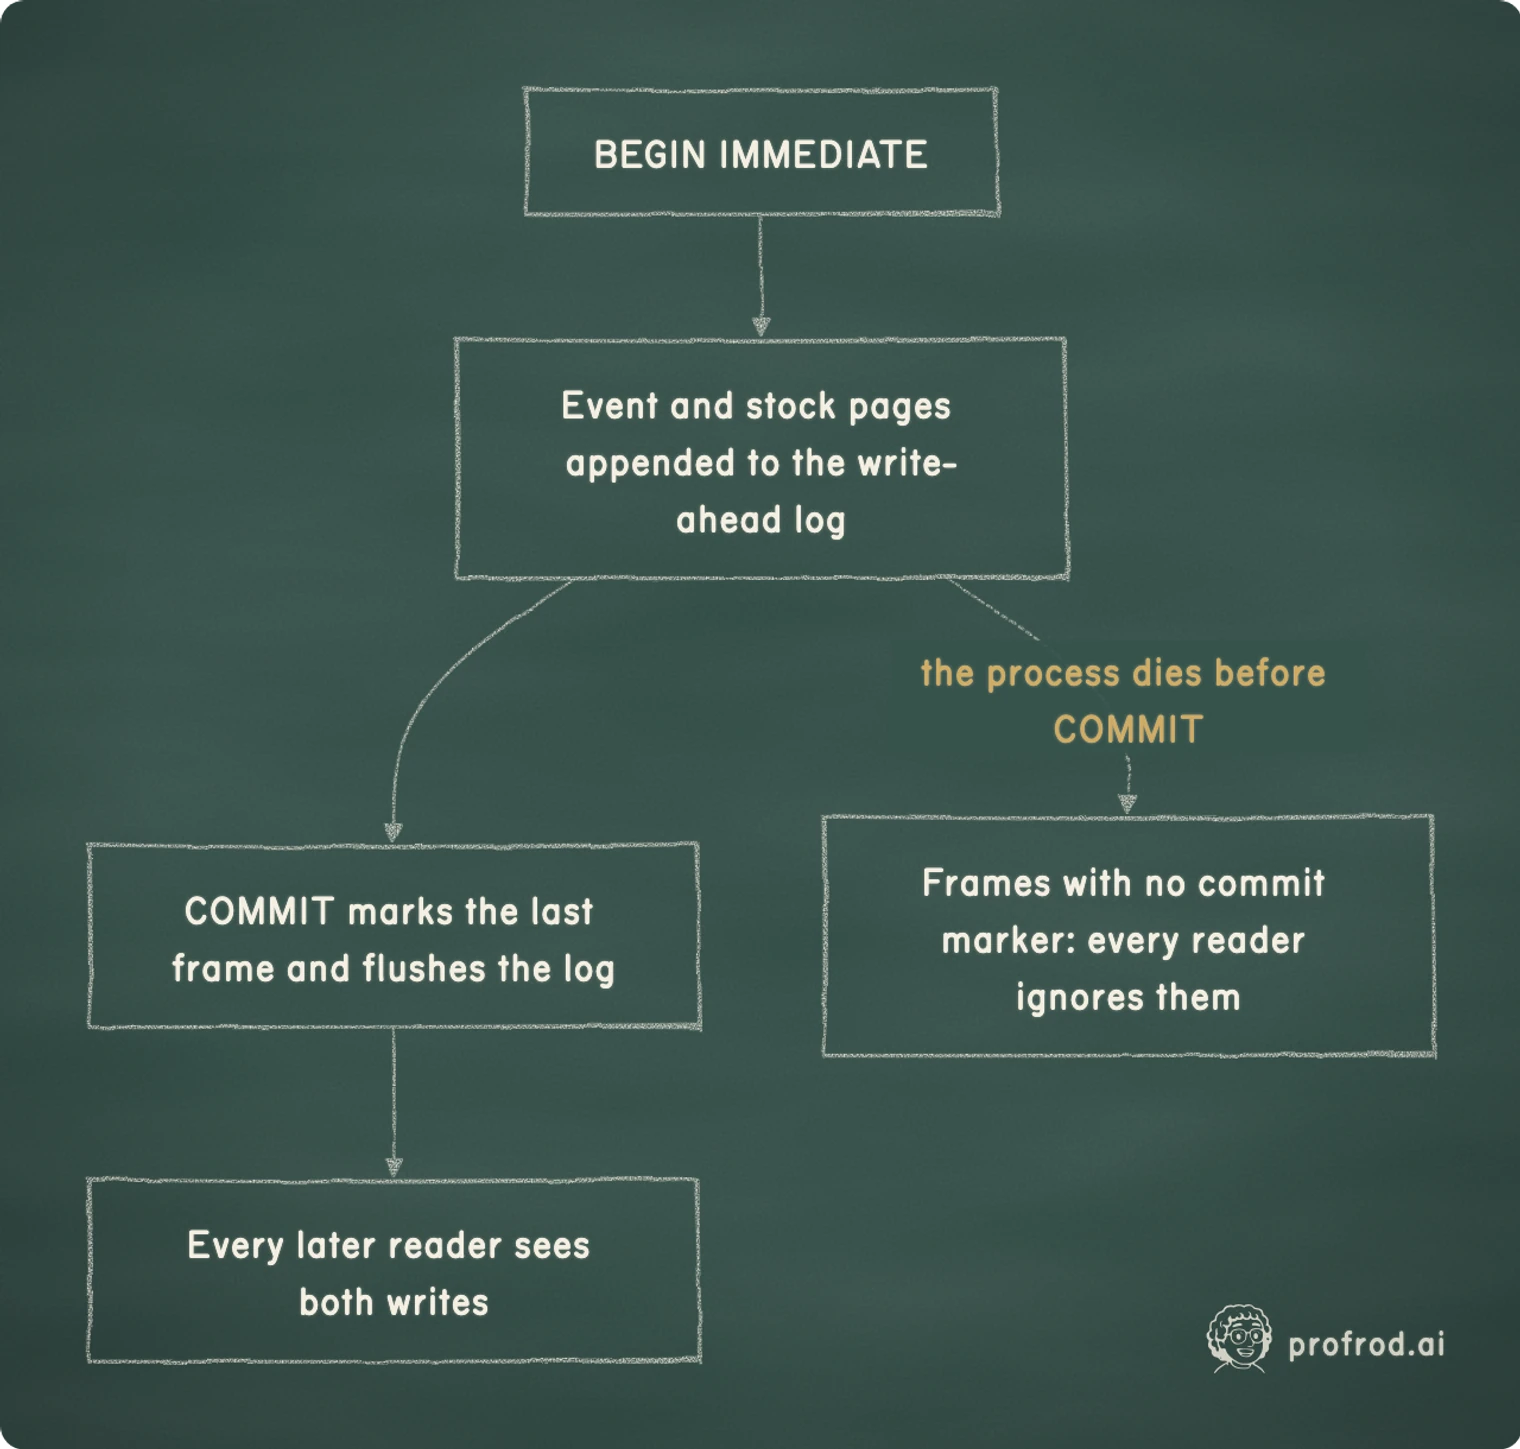
flowchart LR
    B[BEGIN IMMEDIATE] --> W[Event and stock pages appended to the write-ahead log]
    W --> C[COMMIT marks the last frame and flushes the log]
    C --> V[Every later reader sees both writes]
    W -.->|the process dies before COMMIT| I[Frames with no commit marker: every reader ignores them]
Two settings decide how far "durable" reaches. In WAL mode, a commit appends to the write-ahead log; with synchronous = FULL, SQLite also flushes the log to storage before COMMIT returns, so a committed transaction survives a power failure as long as the storage honors the flush. With synchronous = NORMAL, the flush happens only at checkpoints. The file cannot be corrupted either way, but the most recent commits can be lost to a power failure. Our store chooses FULL and pays for it on every commit, which the contention measurement has just shown.
Be exact about the evidence. This chapter tested a process dying. It did not cut the power, and it did not test a disk that acknowledges a flush it has not performed. Those claims rest on SQLite's documentation and on the hardware, not on anything run here.
Hand the store to memory
Chapter 5 receives StateStore and its immediate() transactions, and nothing else. Memory adds its own tables by calling store.migrate("memory", ...) with its own migrations, on its own line of versions. It writes its records inside immediate() blocks. It keeps the invariant discipline for its own facts: a change and its record commit together. It does not get the connection to issue its own BEGIN, and it does not get a helper that hides transactions. A new rule about what must agree becomes a new invariant, and the store's job is to make it impossible to observe that invariant broken.
In a coding agent
Claude Code keeps a session on disk as an append-only log. It stores transcripts as JSONL at ~/.claude/projects/<project>/<session-id>.jsonl, one JSON object per message, tool use or metadata entry. claude --continue reopens the latest conversation in a directory, and claude --resume picks one. The documentation warns that the entry format is internal and changes between versions, and points scripts to /export instead.
The difference from this chapter is what the log is for. Lucy's store enforces invariants inside transactions, so every observable state is a valid one. A transcript is a record of a conversation. It lets a session continue, but it does not make the work it describes consistent. That is why Chapters 8, 12 and 13 keep business state in the database, not in the conversation.
Try it in Claude Code: find your latest session's .jsonl file, count its lines, then resume it by path with claude --resume <transcript-path>.
Expected observations
Run the checkpoint from the repository root:
uv run python book/textbook/checkpoints/profrod_sovereign_agent_ch04_sqlite_state_checkpoint.pyIt prints twelve ok lines and ends with Chapter 4 checkpoint: durable state holds across reopen, failure, replay and version. Four of them carry the chapter's argument:
- A failure between the two writes leaves vanilla at 2 and only
e1in the log. - An identical replay of
e1is a duplicate, ande1with other content is a conflict that leavese1unchanged. - A sale from nine tubs leaves six, with both events kept.
- A file at a future schema version is refused, with its rows untouched.
The last line is a negative control. The observer is shown a half-applied change and must catch it. If that line fails, the fault is in your observer, not your store.
The experiment's receipt should show every refusal rate inside its 95% interval around , and no refusals once the timeout is at least the hold. Your mean waits will differ from ours, because they depend on your storage. Read them against both wait models rather than against our numbers.
Learner verification
Do not verify the store with store.stock(). It reads through the connection under test, so it can agree with a mistake the store makes about itself. After your program has closed the file, open it with a separate connection and run the invariant as a query:
SELECT sku, tubs,
       (SELECT SUM(delta) FROM events WHERE events.sku = stock.sku) AS explained
FROM stock
WHERE explained IS NULL OR tubs != explained;
An empty result is the invariant holding: every count is explained by its events. A row names the product whose count and events disagree, or a count with no events behind it at all. Then break it on purpose. Stop your program between the two writes of a change made without immediate(), and run the query again. It must now return the product whose count and events disagree. A check that cannot fail on a broken file proves nothing about a good one.
Finally, read the version with SELECT value FROM meta WHERE key = 'stock.version', and confirm that running initialize a second time leaves it, and every row, unchanged.
Exercises that change the decision
Exercise 1: Find the state that should not exist
Remove the with self.immediate() from apply in your learner file, so the two writes commit separately. Run the checkpoint. Which check fails, and which observation does it print? Then restore the transaction and explain in two sentences why the independent observer caught what store.stock() alone could not.
Exercise 2: Retry an unknown outcome
Write deliver_with_retry(store, event, attempts) for a caller that saw its connection drop and does not know whether the delivery committed. Show with the observer that three retries of the same StockEvent leave exactly one event and the right stock. Then generate a fresh event_id per attempt instead, and describe what the observer shows.
Exercise 3: Test the missing cost
The measured waits exceed the stepped model by 0.8 to 5.5 ms. Change the experiment's holder to use PRAGMA synchronous = NORMAL and run it again. If the gap shrinks, you have measured part of the commit's cost; if it does not, what else could hold the lock? Record both receipts and state your conclusion with the numbers.
Exercise 4: A migration you did not plan
Add migration 3, which records a unit column on stock with default 'tub'. Show that a version-2 file upgrades, that a second initialize changes nothing, and that the chapter's version-2 program now refuses the upgraded file. Explain why that refusal protects Lucy's data.
Active recall and vocabulary
- Connection: a handle to the database, not the database itself. The file is the state.
- Constraint: a rule enforced by the database at every write, for example
CHECK (tubs >= 0). - Parameter: a value sent separately from the SQL text, never pasted into it.
- Transaction: writes grouped so the file shows all of them or none.
BEGIN IMMEDIATE,COMMITandROLLBACKmark its edges. - Invariant: a statement about the state that must hold in every observable state, here .
- Idempotent: doing it twice leaves the same result as doing it once, here .
- Migration: the change from schema version to , committed together with the new version number.
- Busy timeout: how long a writer waits for another writer's lock before being refused.
Answer without looking back: why does a CHECK constraint on the stock table also protect the event log? What does say about halving the time a transaction holds the lock? What did the crash experiment establish, and what did it not?
Summary
You built Lucy's durable state from its smallest parts: a table, a parameterized write, a constraint, and a second connection that proves the write reached the file. You stated the invariant that ties stock to events. You showed a program that breaks it with a failure between two writes, and proved that a transaction keeps it in every observable state. Event append became a function you can reason about: identical replays are duplicates, reused identities are conflicts, and the database refuses to rewrite history. Schema versions form a line, each migration commits with its version, and a newer file is refused before anything changes. Finally you derived and measured the cost of sharing one write lock: refusals at matched, and waits exceeded the models by a gap you can now go and explain.
Continue to Chapter 5: memory. Exercise Book · Solutions Book · Textbook contents.
Keep building with Prof Rod
Found this material through a colleague, classroom or shared download? Get the complete book at profrod.ai/book and join the Prof Rod learner community. Bring one result, one question or one failure you learned from. Share this resource with another learner and keep its source links with it so they can find the full course and future updates.


