
You want a technical role at a frontier lab. The titles overlap: applied AI engineer, research engineer, research scientist, member of technical staff. The title tells you less than the duties, and the duties tell you what to practice.
This piece reads the market two ways. The jobs board counts what open postings mention. Then fifteen postings, read in full, show what those mentions look like as work. Every skill below links to its page on the board, and every kind of role to its role page.
What the board counts
On October 2, 2026, the jobs board listed 1,837 open technical roles at 49 labs: 173 research scientist roles, 123 research engineer roles and 323 applied AI roles. Almost half, 877, were software roles. The share of each segment's postings that mention a skill:
| Skill | Research scientist (173) | Research engineer (123) | Applied AI (323) |
|---|---|---|---|
| Evals and benchmarks | 62% | 66% | 53% |
| How language models work | 61% | 70% | 52% |
| Post-training and fine-tuning | 49% | 46% | 11% |
| Publications | 49% | 24% | 1% |
| Agents and tool use | 46% | 40% | 46% |
| Reinforcement learning | 44% | 45% | 2% |
| PyTorch | 44% | 47% | 5% |
| Inference and serving | 27% | 44% | 32% |
| Production systems | 21% | 42% | 64% |
| Working with customers | 15% | 19% | 96% |
| Retrieval and RAG | 6% | 5% | 24% |
Scroll horizontally to view columns.
Two patterns stand out. Research postings share a core: evals, how models work, post-training, RL and PyTorch, with publications weighing on research scientists. Applied AI postings lead with customers and production, and still mention evals in more than half.
The board's counts are pattern matches on posting text, after each lab's repeated template lines are removed, read on October 2, 2026. A mention is not always a requirement. The fifteen postings below were read on September 30, 2026, and each quote links to its posting. Both sources show what labs advertise. Neither shows how many people are hired, what the interview loop contains, or what the work is like day to day. Postings close and change; if a link is dead, treat that posting as a record of what was advertised on that date.
Fifteen postings, read closely
A percentage tells you a skill is common, not what "evals" means as a duty. For that, I read fifteen postings from four labs on September 30, 2026, and wrote down what each asks for in its own words.
| Lab and title | Kind of role | Listed pay in USD, as the posting states it |
|---|---|---|
| Anthropic, Applied AI Engineer, Enterprise Tech (A1) | Applied | $200,000 to $320,000 annual salary |
| Anthropic, Applied AI, Research Engineer (A2) | Applied | $300,000 to $400,000 annual salary |
| Anthropic, Research Engineer, Post-Training Model Evaluations (A3) | Research engineering | $500,000 to $850,000 annual salary |
| Anthropic, Research Engineer, Code RL (A4) | Research engineering | $500,000 to $850,000 annual salary |
| Anthropic, Research Engineer / Scientist, Alignment (A5) | Research engineering | $350,000 to $500,000 annual salary |
| Anthropic, Research Scientist, Interpretability (A6) | Research science | $350,000 to $850,000 annual salary |
| OpenAI, Applied AI Engineer, Startups (O1) | Applied | $211K to $278K, "Offers Equity" |
| OpenAI, Research Engineer, Frontier Evals & Environments (O2) | Research engineering | $295K to $380K, "Offers Equity" |
| OpenAI, Research Engineer, Retrieval & Search, Applied Engineering (O3) | Research engineering | $293K to $585K, "Offers Equity" |
| OpenAI, Research Scientist (O4) | Research science | $250K to $445K, "Offers Equity" |
| OpenAI, Research Engineer/Research Scientist, RL/Reasoning (O5) | Research engineering and science | $295K to $445K, "Offers Equity" |
| Google DeepMind, Research Engineer, Advancing Agent Quality (G1) | Research engineering | US $174,000 to $252,000, plus a 15% bonus target and equity |
| Google DeepMind, Staff Research Engineer, Applied AI (G2) | Applied | US $207,000 to $300,000, plus a 20% bonus target and equity |
| Google DeepMind, Post-Training Agentic Research Scientist (G3) | Research science | US $174,000 to $252,000, plus a 15% bonus target and equity |
| xAI, Member of Technical Staff, Post-Training and RL (X1) | Research engineering | $180,000 to $600,000 |
Scroll horizontally to view columns.
The codes in parentheses (A1, O2 and so on) are mine. I use them below so you can check each claim against its posting.
Each range is one lab's statement for one role at one location. Some are base salary only and some add a bonus target or equity. Ranges from different labs are not comparable line by line, and none of them is a market rate for a title.
Three kinds of work under overlapping titles
The fifteen postings sort into three groups by their duties. The labs do not use these labels; the grouping is my reading.
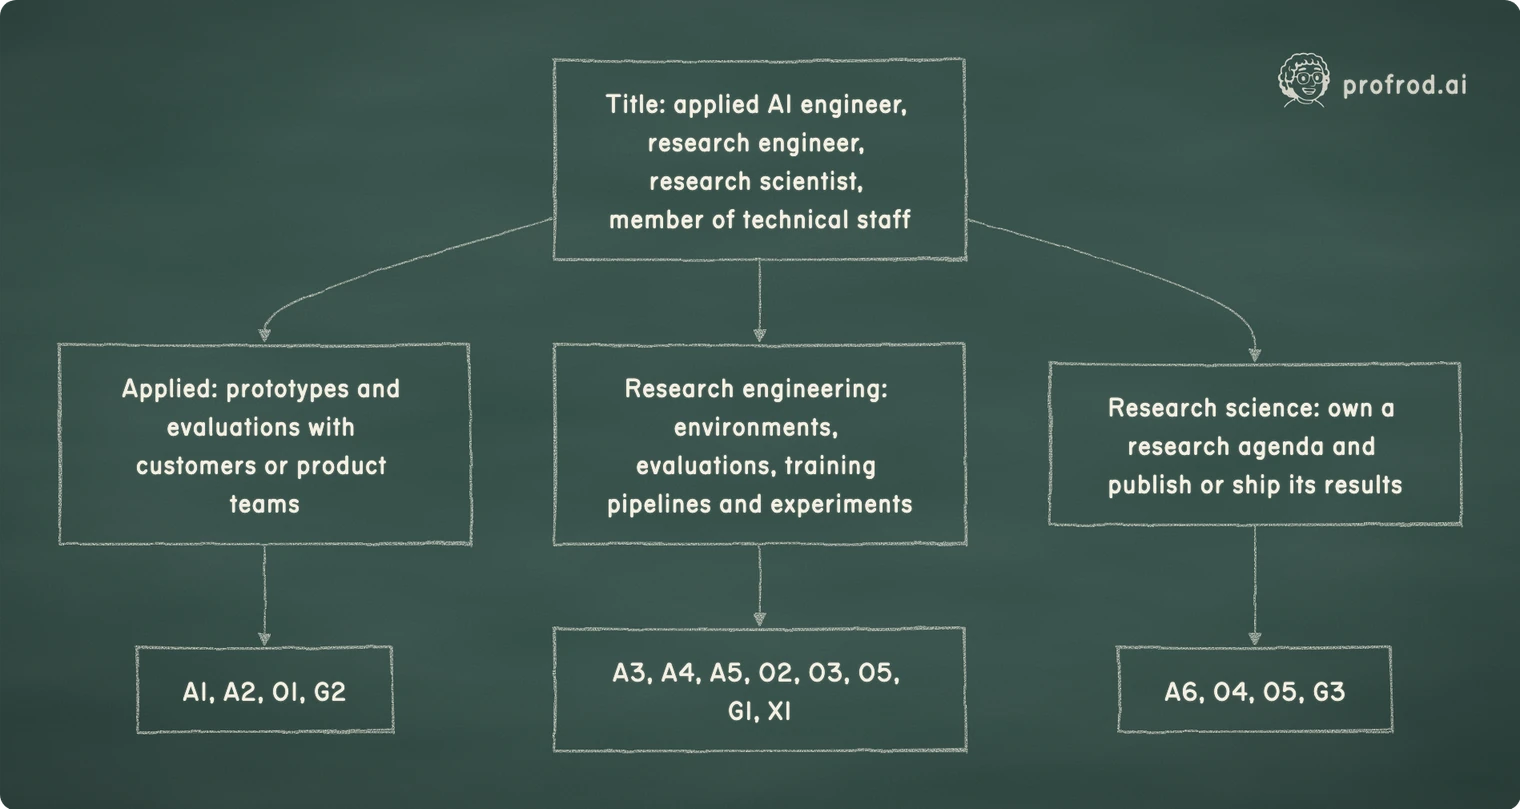
Applied roles (applied AI engineer, forward deployed engineer) work with models on real problems for customers or product teams. Anthropic's A1 will be "developing evaluation frameworks" and asks for "Production experience with LLMs, including advanced prompt engineering, agent development and frameworks, evaluation frameworks, transcript analysis, MCP, and deployment at scale." OpenAI's O1 asks that you have "Built and/or delivered prototypes on top of our API platform."
Research-engineering roles (research engineer, and specialties such as evals, post-training and reinforcement learning) build what training and evaluation run on. Anthropic's Code RL posting (A4) says you will "design RL environments and coding tasks, build the reward signals and verifiers that capture what 'good code' means, run training experiments on frontier models, diagnose why a model does (or doesn't) get better at a class of software-engineering work."
Research-science roles (research scientist, interpretability) own the question. OpenAI's O4 asks for "a track record of coming up with new ideas or improving upon existing ideas in machine learning, demonstrated by accomplishments such as first author publications or projects" and "the ability to own and pursue a research agenda."
Inference: the line between engineer and scientist is soft. O5 and A5 carry both words in the title, and Anthropic's interpretability posting (A6) says: "You view research and engineering as two sides of the same coin. Every team member writes code, designs and runs experiments, and interprets results." xAI's X1 uses the member of technical staff title for post-training work.
What recurs, and where to learn it
I marked a skill as present when a posting's own role text names it as a duty or a qualification, ignoring the paragraphs every posting from a lab repeats. The count is my coding of fifteen documents; the board's counts above are the wider sample.
| Skill | Postings that name it | In the lab's words | Where profrod.ai teaches it |
|---|---|---|---|
| Design, run and analyze evaluations | 9 of 15: A1, A2, A3, A4, A5, O2, G1, G2, G3 | "Care deeply about measurement quality, thinking twice before trusting a number" (A3) | Chapter 16, evaluation as measurement; Research Engineering and Evaluation Science (coming soon) |
| Design and interpret experiments | 6 of 15: A3, A4, A5, A6, O2, O5 | "define the hypothesis, build the pipeline, run the model, analyze the result, and decide what to do next" (O2) | Chapter 16 and Chapter 17, optimizing against an evaluation |
| Agents, environments and verifiers | 9 of 15: A1, A2, A4, A5, O2, O5, G1, G2, G3 | "Design, build, and scale realistic agent environments and task suites" (G1) | Chapter 3, the agent loop; Chapter 14, MCP; Chapter 18, delegation |
| Post-training and reinforcement learning | 9 of 15: A3, A4, A5, O2, O5, G1, G2, G3, X1 | "reward modeling, preference optimization (RLHF/DPO), and RL for improving reasoning, truthfulness, and real-world capabilities" (X1) | Post-Training: From Fine-Tuning to Reinforcement Learning (coming soon); preferences in Chapter 17 |
| Python, named explicitly | 8 of 15: A1, A3, A4, A5, A6, O1, G1, G3 | "deep Python expertise, including async/concurrent programming" (A4) | Every book chapter runs as Python 3.12 on Colab; concurrency in Chapter 13, leases and fencing |
| Communicate results, including null ones | 9 of 15: A1, A2, A3, A5, A6, O1, O2, O4, G2 | "You like writing up and communicating your results, even when they're null" (A6) | Chapter 20, honest reports |
| Diagnose why a model or agent fails | 5 of 15: A1, A3, A4, O5, G1 | "identify root-cause agent failure modes (e.g., passivity, hallucination, or brittle tool execution)" (G1) | Why Agents Fail: Harness Engineering for AI Projects; stage-by-stage retrieval diagnosis |
| Statistics and measurement variance | 3 of 15: A3, O2, G1 | "understanding scalability, reliability, and variance of our evaluation methodology" (O2) | Chapter 16; calibration in Chapter 11, when to ask |
| Performance and systems (inference, GPU kernels) | 3 of 15: A4, A5, O4 | "Past experience in creating high-performance implementations of deep learning algorithms" (O4) | Transformer and Inference Internals (coming soon); Chapter 9, prefill and decode |
| Retrieval and search | 1 of 15: O3 | "prior experience working with vector databases, search indices, or other data stores for search and retrieval use cases" (O3) | Chapter 5, memory and retrieval; Chapter 6, embeddings and vector search |
| Sandboxed code execution | 1 of 15: A4 | "Experience with virtualization and sandboxed code execution environments" (A4) | Chapter 15, prompt injection and isolation |
Scroll horizontally to view columns.
Three of the linked courses are marked coming soon: their syllabi are published and the lessons are not. The book chapters and the other courses are available now. The board's counts show a gap this hand-picked sample hides: PyTorch and publications appear in close to half of research scientist postings, and this site does not teach either yet.
Evaluation is the common thread
Evals lead the board's research counts, and nine of the fifteen postings name them. The research-engineering postings treat evaluation as a science in its own right. Anthropic's evaluations posting (A3) wants someone who will "work out which measurements tell us something real about the model, notice when they stop doing so, and find what we should be measuring but aren't." Its "Strong candidates may also have" list includes a "Background in statistics and experimental design." OpenAI's O2 asks you to "Dive deep into the science of measurement." Google DeepMind's G1 asks you to "calibrate them against human evaluation", where "them" is the automated raters the team builds.
Here is why that is not a soft skill. Suppose a model passes 70% of a 200-item evaluation. The 95% error bar on that pass rate is 1.96 × √(0.7 × 0.3 / 200) = 1.96 × 0.0324 = 0.064, about 6.4 points either way. A change that moves the score from 70% to 73% on those 200 items is inside the noise of a single run. Saying so plainly, and knowing how to design a comparison that could detect a 3-point change, is what "thinking twice before trusting a number" means in practice. Chapter 16 derives this interval and the paired comparison that tightens it, and its exercises are in the book's course repository.
Experience and credentials
The board gives the spread. On October 2, 2026, 62% of research scientist postings mentioned a PhD or MS, and 17% required a PhD with no alternative stated. For research engineers the figures were 36% and 8%; for applied AI roles, 4% and 0%. Among postings that state years, the median minimum was 3 for research scientists (72 of 173 state years), 3.5 for research engineers (50 of 123) and 4 for applied AI (202 of 323).
The fifteen postings show how individual labs word it:
- Google DeepMind lists minimums. G2 asks for a "Bachelor's degree in Electrical Engineering, Computer Engineering, Computer Science, or a related field, or equivalent practical experience" and "8 years of software development experience." G3's minimum is a "PhD degree in Computer Science, Artificial Intelligence, a related field, or equivalent practical experience."
- Anthropic lists years for its applied roles ("4+ years" in A1, "6+ years" in A2) and none for the research roles above. A5 lists what "Candidates need not have": "100% of the skills needed to perform the job" and "Formal certifications or education credentials." A5 also states: "For this role, we conduct all interviews in Python."
- OpenAI asks for "5+ years of experience" in its applied role (O1) and describes research roles by track record rather than years.
- xAI (X1) says: "If you previously worked on post-training, RLHF, or trained models used by millions of people it's a big plus, but relevant experience is not required."
Inference: "or equivalent practical experience" and "need not have" leave room for a candidate without the standard credential. The evidence that fills that room is work someone can inspect: an evaluation with its error bars, an experiment written up with its null result, an environment with a verifier that rejects a planted bad solution.
Check your reading
How to read the next posting you find
Mark each responsibility as applied work, research engineering or research science. Most postings lean one way; some, like O5, deliberately span two. The role pages list open postings by kind of work.
Look for "evaluation", "eval", "benchmark", "grader", "verifier" or "calibrate". If the posting names them, prepare to show an evaluation you designed, with its interval and what it could and could not detect.
A6 asks for "a strong track record of scientific research (in any field)". O1 asks for prototypes built on the lab's API. Match the artifact to the request: a write-up, a repository, a prototype, a paper.
Anthropic splits "You may be a good fit if you" from "Strong candidates may also have". Google splits "Minimum qualifications" from "Preferred qualifications". Anthropic's postings add: "We encourage you to apply even if you do not believe you meet every single qualification." Those are the labs' words about their own lists, not a promise about any application.
How I gathered the fifteen
On September 30, 2026, I read four job boards. Anthropic and xAI publish through Greenhouse (637 and 291 listings that day); OpenAI publishes through Ashby (839 listings). Google DeepMind has no public Greenhouse board; a request to one returned "Job not found", so I searched Google's careers site filtered to DeepMind. I filtered titles for applied AI engineer, research engineer, research scientist and member of technical staff, then chose fifteen that span the three kinds of work, preferring U.S. locations. Fifteen postings chosen by hand say nothing about how common each role is; that is what the board's counts are for.
What an interviewer would ask
The postings do not describe their interview loops, beyond A5's note that interviews are in Python. What they do describe are the duties, and a fair interviewer probes those. From the wording above, expect questions like these:
- "Your evaluation moved from 70% to 73%. Is that real?" (A3, O2). Answer with the interval and the design that would detect the change.
- "Your agent passes every test. How do you know it did not change the tests?" (A4, G1). See where a coding agent's expected values came from.
- "Walk me through an experiment that failed." (A6, O5). Have one written up, null result included.
- "Why did this agent fail on that task?" (G1). Show a diagnosis that locates the failing stage before proposing a fix.
If you cannot yet answer one of these with your own work, that is your next study item. The ten-question readiness check shows where you stand, and the study-plan builder asks four questions and returns an ordered plan through the book and courses.
Ten questions from the work these postings describe: derivation, measurement, experiment design, coding agents and write-ups. Your answers show where you stand and what to study next.


